❌

Visualização normal

Ontem — 9 de Novembro de 2026Cybersecurity News
  • ✇Cybersecurity News
  • Lone Hacker Uses BOSSAI Attack Mesh to Breach Taiwan Emergency Services and Universities Do Son
    Acronis TRU uncovered the BOSSAI attack mesh Taiwan campaign using 12 AI agents to breach emergency services, banks, and universities in 11 countries. Related Posts: Exposed Server Reveals DoNot APT Toolkit Targeting Pakistan Nuclear and Energy Sectors French Blood Bank Cyberattack Hits Plasma Storage APT29 Uses Watering Holes and Plerdy Tracker to Deploy Mobile Exploits The post Lone Hacker Uses BOSSAI Attack Mesh to Breach Taiwan Emergency Services and Universities appeared first on Daily C
     
  • ✇Security Affairs
  • SECURITY AFFAIRS AI-CYBERSECURITY NEWSLETTER ROUND 7 Pierluigi Paganini
    Security Affairs AI-CYBERSECURITY newsletter includes a collection of the best articles and research on AI in the international landscape Artificial intelligence is rapidly changing cybersecurity, reshaping both the techniques used by attackers and the tools available to defenders. AI agents can automate tasks, analyze large amounts of data, discover vulnerabilities and accelerate offensive operations. At the same time, AI is creating new capabilities for threat detection, incident analysis
     

SECURITY AFFAIRS AI-CYBERSECURITY NEWSLETTER ROUND 7

8 de Novembro de 2026, 12:28

Security Affairs AI-CYBERSECURITY newsletter includes a collection of the best articles and research on AI in the international landscape

Artificial intelligence is rapidly changing cybersecurity, reshaping both the techniques used by attackers and the tools available to defenders. AI agents can automate tasks, analyze large amounts of data, discover vulnerabilities and accelerate offensive operations. At the same time, AI is creating new capabilities for threat detection, incident analysis and response. Security Affairs’ new newsletter follows this evolution, covering every week the latest threats, attacks, vulnerabilities and developments at the intersection of AI and cybersecurity.

‘It’s 100 percent a national security threat’: Accenture contractor connected an AI agent to the Pentagon’s secure network, and then sent data to a high-risk website  

Security notice — malicious version of Anthropic.claude-code (2.1.312 and 2.1.313) identified in the Cursor VS Code Extension Marketplace  

UK and Germany to jointly develop military AI in 2027

Appraisal by AI: Model-driven victim prioritization in the VOLTA infostealer  

AI policy wonks declare ‘sovereign agents’ a threat to civilization

Progress on provable inference for large language models

The Rise of LLMJacking: How Threat Actors Monetize Compromised Cloud and Model Resources     

“Black October” for AI Developer Platforms   

ARTEX Exposed: Mapping the Infrastructure Behind the South Korean Bank Breaches  

A thousand fewer paths to root

Securing Muse: More Than $1 Million in Bug Bounties Paid Out

Free the Model, Sell the Gateway: Prompt Adware hidden in Jailbreak Bundles

WorkOS October 30th, 2026 Data Security Incident  

Covert underperformance on safety research tasks

GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents  

ThisBash Escape: Claude Dispatch Flaw Enables Browser Extensions RCE on the OS  

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, newsletter)

  • ✇Security Affairs
  • Security Affairs newsletter Round 603 by Pierluigi Paganini – INTERNATIONAL EDITION Pierluigi Paganini
    A new round of the weekly Security Affairs newsletter has arrived! Every week, the best security articles from Security Affairs are free in your email box. Enjoy a new round of the weekly SecurityAffairs newsletter, including international press. Inside ARTEX: AI Hacking Tools, Exposed Servers and South Korean Bank BreachesOne Product Isn’t the Problem: Monetizing an AI Portfolio Without Confusing Your CustomersU.S. CISA adds SonicWall SonicOS SSLVPN flaw to its Known Exploited Vulnerabil
     

Security Affairs newsletter Round 603 by Pierluigi Paganini – INTERNATIONAL EDITION

8 de Novembro de 2026, 10:48

A new round of the weekly Security Affairs newsletter has arrived! Every week, the best security articles from Security Affairs are free in your email box.

Enjoy a new round of the weekly SecurityAffairs newsletter, including international press.

Inside ARTEX: AI Hacking Tools, Exposed Servers and South Korean Bank Breaches
One Product Isn’t the Problem: Monetizing an AI Portfolio Without Confusing Your Customers
U.S. CISA adds SonicWall SonicOS SSLVPN flaw to its Known Exploited Vulnerabilities catalog
White House Network Appears in Global Residential Proxy Traffic
OpenAI Rates GPT-6 Cyber Critical After Major Vulnerability Discoveries
ENISA Warns of Cyberattacks Targeting Refrigeration Systems Across Europe
OpenAI Reports Covert Underperformance in GPT-6 Astra
UNM Health Shuts Clinics and Diverts Patients During Security Incident
Russian APT29 Targets Mobile Users with Watering Hole Attacks
U.S. CISA adds Apple flaw to its Known Exploited Vulnerabilities catalog
U.S. Charges Canadian Man in Alleged Hack of University Supercomputers
Two Barracuda ESG Flaws Could Be Combined for Full Root Access; Patches Released
Cyberattack Hits French Blood Banks as Hackers Target Refrigeration Systems Across Europe
CVE-2026-58868: Critical Android Bug Could Let Attackers Run Remote Code
U.S. CISA adds WordPress flaw to its Known Exploited Vulnerabilities catalog
Binance Hack: How Fake Job Interviews and AI Abuse Led to a $6.34 Billion Attack
Synology Warns of Ransomware Attacks Targeting NAS Devices Running Outdated DSM Versions
Inside XCPE, the botnet that turned 1.3M set-top boxes into proxy servers
NIS2 Makes Board Members Personally Liable for Access Control Decisions
Apple’s spyware notifications reach the Bundestag: what the BSI says to do now
VOLTA, the infostealer that asks an AI which victims are worth the effort
New wave of fridge cyberattacks hits European supermarkets, this time in Belgium, Luxembourg, Sweden and Estonia
Hackers Send Fake Nuclear Threat Alerts to Ukrainian and Russian Citizens
Chainalysis Investigates Security Incident Involving AI-Driven Attack Techniques
FBI Blames North Korea for $6 Billion Binance Crypto Theft
SMS of Death: Android under attack, an invisible SMS can block calls and emergency services

International Press – Newsletter

Cybercrime

How hackers broke into four of Canada’s top law firms, stole client files and caused chaos

Polymarket Pauses Trading as Prediction Market Investigates Security Incident

From help desk impersonation to AD CS abuse: Investigating ESC1 and ESC8 intrusion paths

29 October Binance Security Incident: Initial Findings and Response Update     

“Black October” for AI Developer Platforms  

Canadian man extradited to the U.S. for his role in computer hacking scheme targeting universities  

ARTEX Exposed: Mapping the Infrastructure Behind the South Korean Bank Breaches

French bank Credit Mutuel Arkea says €100 million missing after cyberattack  

Malware

Shutting the Door on the XCPE Botnet  

Free the Model, Sell the Gateway: Prompt Adware hidden in Jailbreak Bundles  

Hackers hijack cPGuard autoupdate to deploy backdoor, steal data  

CWPdoor: The Invisible Backdoor Living Inside Control Web Panel  

Hacking

SMS of Death 

Chainalysis Security Incident Information  

Russia and Ukraine say emergency alert apps were hit by apparent cyber-attacks  

European supermarkets hit by new fridge cyber attack  

The Rise of LLMJacking: How Threat Actors Monetize Compromised Cloud and Model Resources

Securing Muse: More Than $1 Million in Bug Bounties Paid Out  

WorkOS October 30th, 2026 Data Security Incident  

A thousand fewer paths to root

ThisBash Escape: Claude Dispatch Flaw Enables Browser Extensions RCE on the OS 

Barracuda Networks is your new best friend (Barracuda Email Security Gateway Pre-Auth Remote Root RCE CVE-2026-116606 / CVE-2026-111560) 

Intelligence and Information Warfare  

North Korea Responsible for $6 Billion+ Binance Attack  

Russia funded Facebook and Twitter investments through Kushner investor

Unknown APT uses NetamLoader to attack a Win10 OS customized for governments in Asia

French blood banks hit alongside cyberattack on European supermarkets

UK and Germany to jointly develop military AI in 2027 

Apple threat notifications regarding Mercenary Spyware  

DarkBlinders: Inside an Active Espionage Campaign

Poisoned Source: APT29 watering holes target mobile devices with n-day exploits

Russian Federal State Statistics Service says it was hit by massive cyberattack — hackers steal 23TB of data, including Ukraine war casualty figures

The Google Whistleblower Taking on Big Tech Over Its Role in Gaza  

Weekly Wire #17: Hybrid war hits home  

Cybersecurity

Israeli startups raised at least $872 million in October, led by cybersecurity and AI 

Europe on alert after supermarket freezers hit by cyber-attacks in 10 countries  

Joint statement on cyber incidents in refrigeration systems across the EU  

GPT‑6 Cyber: Advancing the frontier of aligned cybersecurity agents

Residential Proxies Detected on White House Network  

European refrigerator controller redux: A new wave of refrigeration attacks

Hundreds of Mundane AI Apps Are Hiding Sexually Abusive Deepfake Features       

Japan announces emergency cybersecurity package following a wave of attacks   

ThisBash Escape: Claude Dispatch Flaw Enables Browser Extensions RCE on the OS  

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, newsletter)

  • ✇Cyber Security News
  • Google Gemini Safety Bypass Lets Users Download AI-Generated Images That Its Own Filters Blocked Abinaya
    Google Gemini allowed users to download AI-generated images that its safety filters had refused to display, according to research published by Fog Security on November 5, 2026. The bypass did not require a jailbreak. Instead, the download feature sometimes delivered a rejected image while the conversation showed a different, allowed picture. Gemini Image Safety Filter Bypass Fog Security reported the issue to Google in June 2026. By October 22, researchers could no longer reproduce it a
     

Google Gemini Safety Bypass Lets Users Download AI-Generated Images That Its Own Filters Blocked

9 de Novembro de 2026, 09:26

Google Gemini allowed users to download AI-generated images that its safety filters had refused to display, according to research published by Fog Security on November 5, 2026.

The bypass did not require a jailbreak. Instead, the download feature sometimes delivered a rejected image while the conversation showed a different, allowed picture.

Gemini Image Safety Filter Bypass

Fog Security reported the issue to Google in June 2026. By October 22, researchers could no longer reproduce it across 12 new attempts, and older conversations downloaded the correct images.

Google attributed the change to routine maintenance rather than a fix linked to the report. A Gemini web app flaw allowed blocked images to bypass safety refusals through the full-size download path, despite remaining restricted in chat.

Researchers first submitted an image request that triggered a refusal, then requested a different, permitted image. Although the allowed picture appeared onscreen, its download button sometimes retrieved the rejected output.

Results ranged from blurry, unfinished files to complete images, with successful tests across multiple days and sessions. Both image URLs used lh3.googleusercontent.com and required the signed-in user’s session. Inline links ended in =s1024-rj, while download links ended in =s0-d-I.

Researchers suspected a state-management error involving image generation, safety checks, and cleanup. That explanation remains unconfirmed.

A December 2025 Google community report also described downloads returning older images instead of the displayed preview. However, that complaint did not establish a safety bypass.

Unlike prompt injection targeting Gemini’s memory, this issue did not rely on hidden instructions changing the assistant’s behavior.

Prompt resulting in a Gemini safety refusal (source : fogsecurity )

It also differed from AI jailbreaks using assistant prefill, which push models toward prohibited answers. Here, the refusal remained intact while file delivery failed to enforce it.

Fog Security tested copyrighted characters, a synthetic person, and the researcher’s own likeness. It did not test child safety content or images involving other real people. No access to another user’s data or privilege escalation was reported.

Google initially marked the June 25 report out of scope, then reviewed it after researchers stressed the infrastructure issue. It declined to track an abuse bug on September 30. On October 23, Google said no internal ticket had been filed and closed the report.

Fog Security recommends binding each download to its approved preview and removing files from refused or failed generations. The finding shows why AI safety testing must cover stored files and download links, not only chatbot replies. A refusal protects users only when every delivery path follows the same decision.

Give your SOC the alert context to stops incidents quickly. Integrate Threat Intel from 16K SOCs.

The post Google Gemini Safety Bypass Lets Users Download AI-Generated Images That Its Own Filters Blocked appeared first on Cyber Security News.

  • ✇Security | CIO
  • Grok Bot’s usage limits: Why the fine print matters more than the price
    On November 1, 2026, Grok Bot users gave IT buyers a live example. Subscribers reported that their weekly usage allowance ran out sooner than expected, and Elon Musk wrote on X that the cost of serving Grok Bot was “unsustainably high relative to revenue.” He confirmed it was not a glitch, but he did not say how the limits would change. The cost of running the service is the seller’s problem. The allowance that a buyer thinks they bought is the buyer’s. Grok Bot is a co
     

Grok Bot’s usage limits: Why the fine print matters more than the price

9 de Novembro de 2026, 06:00

On November 1, 2026, Grok Bot users gave IT buyers a live example. Subscribers reported that their weekly usage allowance ran out sooner than expected, and Elon Musk wrote on X that the cost of serving Grok Bot was “unsustainably high relative to revenue.” He confirmed it was not a glitch, but he did not say how the limits would change.

The cost of running the service is the seller’s problem. The allowance that a buyer thinks they bought is the buyer’s.

Grok Bot is a consumer product, but any team that buys metered AI plans faces the same exposure. The allowance can shrink or run out early, and the overrun lands in a department budget. This example shows what a price page does not tell a budget owner: the rules and limits behind the allowance can matter more than the price. Your AI bill will not look like your last software bill. Seats are no longer the whole story, and the line item that finance approved in January may not describe what you are actually buying in June.

The price page is also a poor guide. Stanford’s 2025 AI Index found that the cost of inference at GPT-3.5 level fell more than 280-fold between November 2022 and October 2024. Yet the FinOps Foundation’s State of FinOps 2026 survey found that 98 percent of respondents now manage AI spend, up from 31 percent two years earlier. Cheaper units have not made the bill easier to predict.

I recently published research on how AI companies publish their prices. I read the public pricing pages and documentation of the Forbes AI 50 and a set of cloud platforms that sell AI services, captured in mid-September 2026. The goal was to describe what is on the page, not to judge whether any price is fair. The finding that matters most for a budget is not the pricing model. There are four rules attached to the credit allowance: expiry, rollover, minimums and recharge.

What the pricing pages show

Classic software charged per seat because serving one more user cost almost nothing. Model inference is different. Every request has a real cost, and usage can differ by orders of magnitude from one customer to the next. Pricing has moved to follow that cost.

The most common model among AI-native companies is a subscription with a usage credit allowance. Sixteen of the 29 companies whose pricing I could observe use it. The allowance is usually counted in credits, compute units or generation time. The flat tier price is the headline. The credit balance is where the real limit lives.

Many companies publish nothing at all. Twenty-three of the 52 AI-native companies in the sample show no pricing, and about half of those show a call to contact sales instead. Every cloud platform in the sample did publish its prices.

Model APIs split on when you pay. Of eight model API and inference providers, two require prepaid credits that draw down as you use them. The other six bill after the fact. Established products tend to keep the per-user price and add a meter on top, with an allowance for AI use and a higher rate once you pass it. Pricing by outcome appeared only in customer service, where a resolved conversation is easy to observe and agree on.

Four rules that decide what an allowance is worth

Most budgeting advice stops at the pricing model. The part that changes your bill sits one level below, in the rules attached to the credit allowance. In my sample, plans with the same shape differed on four rules.

  1. Expiry. Some free credits expire every month, and prepaid balances on a model API can carry an expiration too. Unused allowance is not an asset. A quiet month does not bank value for a busy one.
  2. Rollover. One media tool lets unused time carry over and a comparable one does not. Two plans at the same price cost a team with uneven demand very different amounts.
  3. Minimums. A customer service product that charges per resolved conversation also sets a monthly minimum of 50 resolutions. A vector database service sets a minimum of $50 per month. The unit price is not your floor. The minimum is.
  4. Recharge. A prepaid balance can top itself up when it runs low. That protects the service and removes a natural pause point. A cap in your spreadsheet is not a cap in the billing system.

These are illustrative cases from the pricing pages. Others have seen part of this. Flexera warns that credit expiration, reset, and rollover rules “can silently create overages or strand value”. Zuora notes that prepaid credit packs give the seller working capital. Read from the buyer’s side, a prepaid pack is money you advance to a supplier, subject to expiry rules. The pricing pages show how widely those rules differ, and the difference is where a budget goes wrong.

What I would do with this as an IT leader

The rest of this article is my own personal, practical view. It is not a finding from the study. It comes from building and running billing systems.

  • Split every AI line into fixed and variable. A single line called “AI tools” hides what you need to see. Put the subscription in one line, the usage allowance in a second and the overage you might incur in a third. When someone asks why the cost rose, you should be able to say which of the three moved.
  • Ask what the allowance is counted in, then ask four more questions. Tokens, requests, credits and compute time are not interchangeable, and one supplier’s credit is not another’s. Ask what one unit buys. Then ask what expires, what rolls over, what minimum applies and what recharges automatically. Get the answers in writing next to the contract. If the supplier cannot state them, treat that as a risk you must price in.
  • Budget a range with a ceiling, not a single number. Heavy users can use far more than typical users, so the average is a poor guide. Pick one typical user and one heavy user for each workflow and estimate the cost of each. That gives you a low case, an expected case and a ceiling. Rework recommends setting a monthly cap and alerts at 50, 75 and 100 percent of it before anyone starts using a metered feature. I agree with the order. Then check whether the supplier enforces your cap or only sends an email. With auto-recharge on, the cap in your budget may not exist in the system.
  • Give each workflow a named owner. Apu Pavithran calls AI credits that the company pays for, but decision makers cannot see “shadow tokens”. An owner per workflow is the plainest fix. Keep the fixed subscription apart from the extra usage charges. Where you must estimate how to share a cost, say that it is an estimate and write down the method. A central AI budget can also be the right choice, as long as finance can see which teams depend on the work before anyone cuts it.
  • Plan for prices to change. Public pricing in the AI era has moved quickly. One widely used developer tool changed its pricing in June 2025 and clarified the change two weeks later. Put a review date on every AI contract and ask what happens to your terms if the supplier reprices.
  • Insist on usage data that matches the invoice. When the dashboard says one number and the invoice says another, someone has to explain the gap, and it will be you. Before you sign, ask for a sample invoice and the usage export that goes with it. Check that you can reconcile the two on a small account.
  • Be careful with outcome pricing. Paying only when the work succeeds is fair only when both sides agree on what success means. Write down the definition of an outcome, the edge cases and how a dispute will be settled. If you cannot define it in a sentence your own team can check, you are handing the definition to the supplier.
  • If there is no published price, ask for the rate card first. Nearly half of the AI-native companies in my sample publish no pricing. That is not a reason to avoid them. It is a reason to ask for the rate card, the allowance rules and a sample invoice before the conversation about discounts.

A short checklist for your next review

✓ Fixed, allowance and overage are separate lines.

✓ Every allowance is stated in units you understand.

✓ Expiry, rollover, minimum and recharge rules are written down for each plan.

✓ Each workflow has an owner and a typical, heavy and ceiling case.

✓ Every contract has a review date and a repricing clause.

✓ Invoices and usage data reconcile on a small account.

AI pricing will keep changing. Your budget does not need to predict every change. It needs to show which parts are fixed, which parts move with use and who is watching them.

Google Gemini Safety Filter Bypass Exposes Blocked AI Images Through Download Links

Google Gemini exposed images that its safety filters had rejected through download links, revealing an infrastructure weakness rather than a conventional model jailbreak. Fog Security researcher Jason Kao disclosed the findings on November 5, 2026, describing how Gemini could refuse an image request while still delivering the blocked artifact. Retesting on October 22 found changed […]

The post Google Gemini Safety Filter Bypass Exposes Blocked AI Images Through Download Links appeared first on GBHackers Security | #1 Globally Trusted Cyber Security News Platform.

GhostAction Attack Hits Tens of Thousands of GitHub Repositories to Steal Cloud and AI Credentials

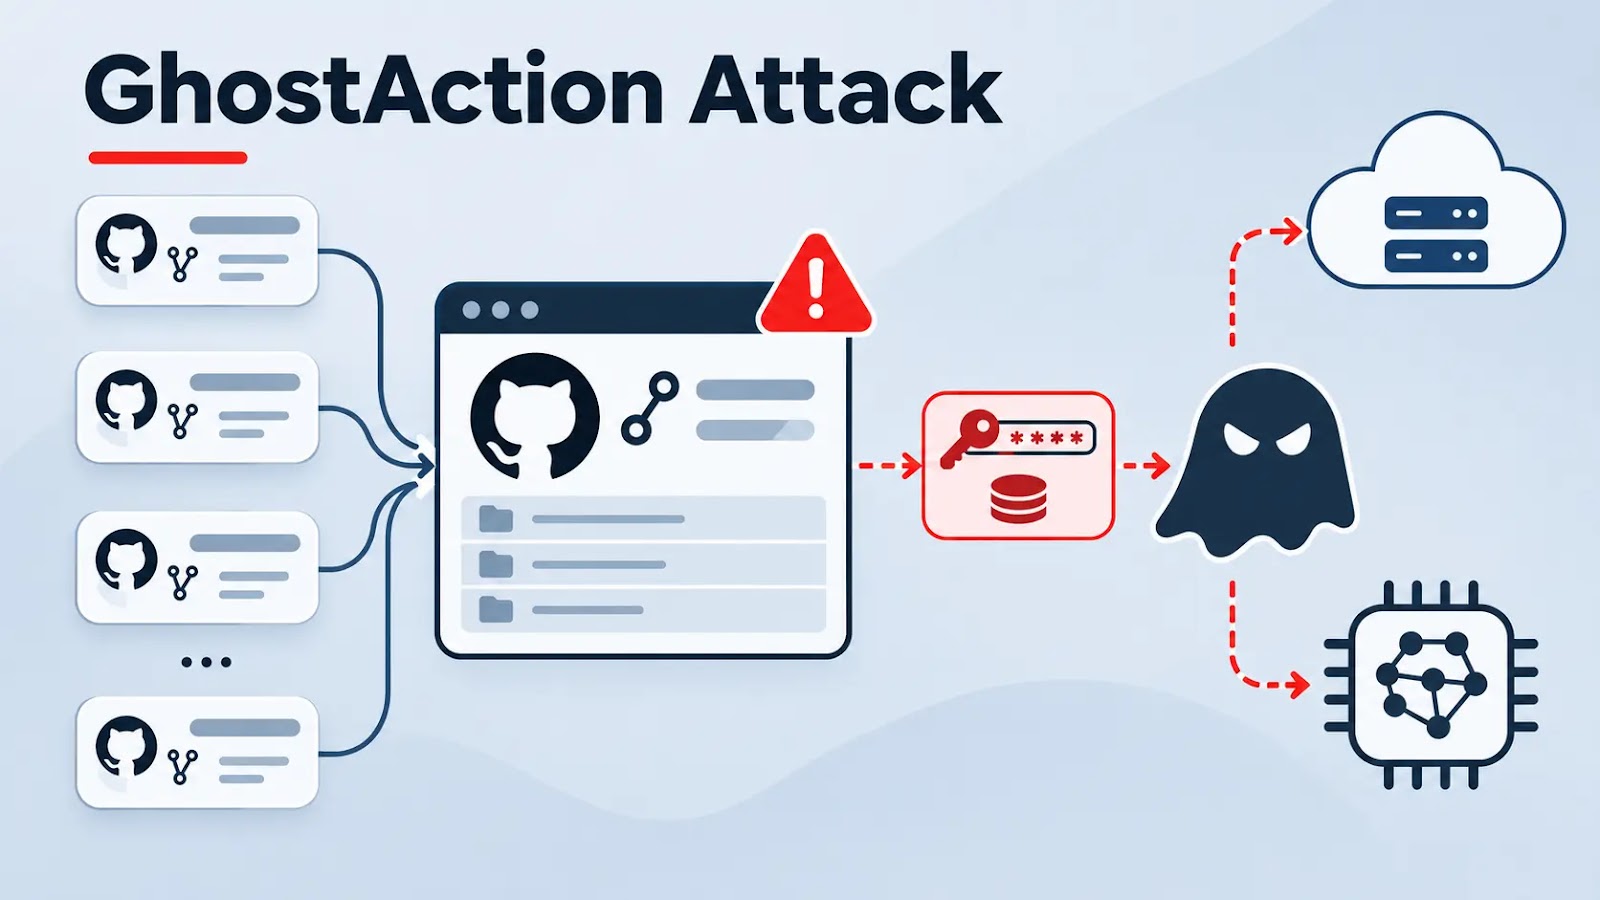
A new wave of the GhostAction supply chain campaign has pushed a credential-stealing GitHub Actions workflow into tens of thousands of repositories. It now hunts for cloud and AI keys buried in source code and git history, in addition to CI/CD secrets. Socket says it has identified more than 500 GitHub accounts that committed the […]

The post GhostAction Attack Hits Tens of Thousands of GitHub Repositories to Steal Cloud and AI Credentials appeared first on GBHackers Security | #1 Globally Trusted Cyber Security News Platform.

Operation Snowball Exposes AI Hacking Campaign Targeting European Telecom and 13 Hosted Organizations

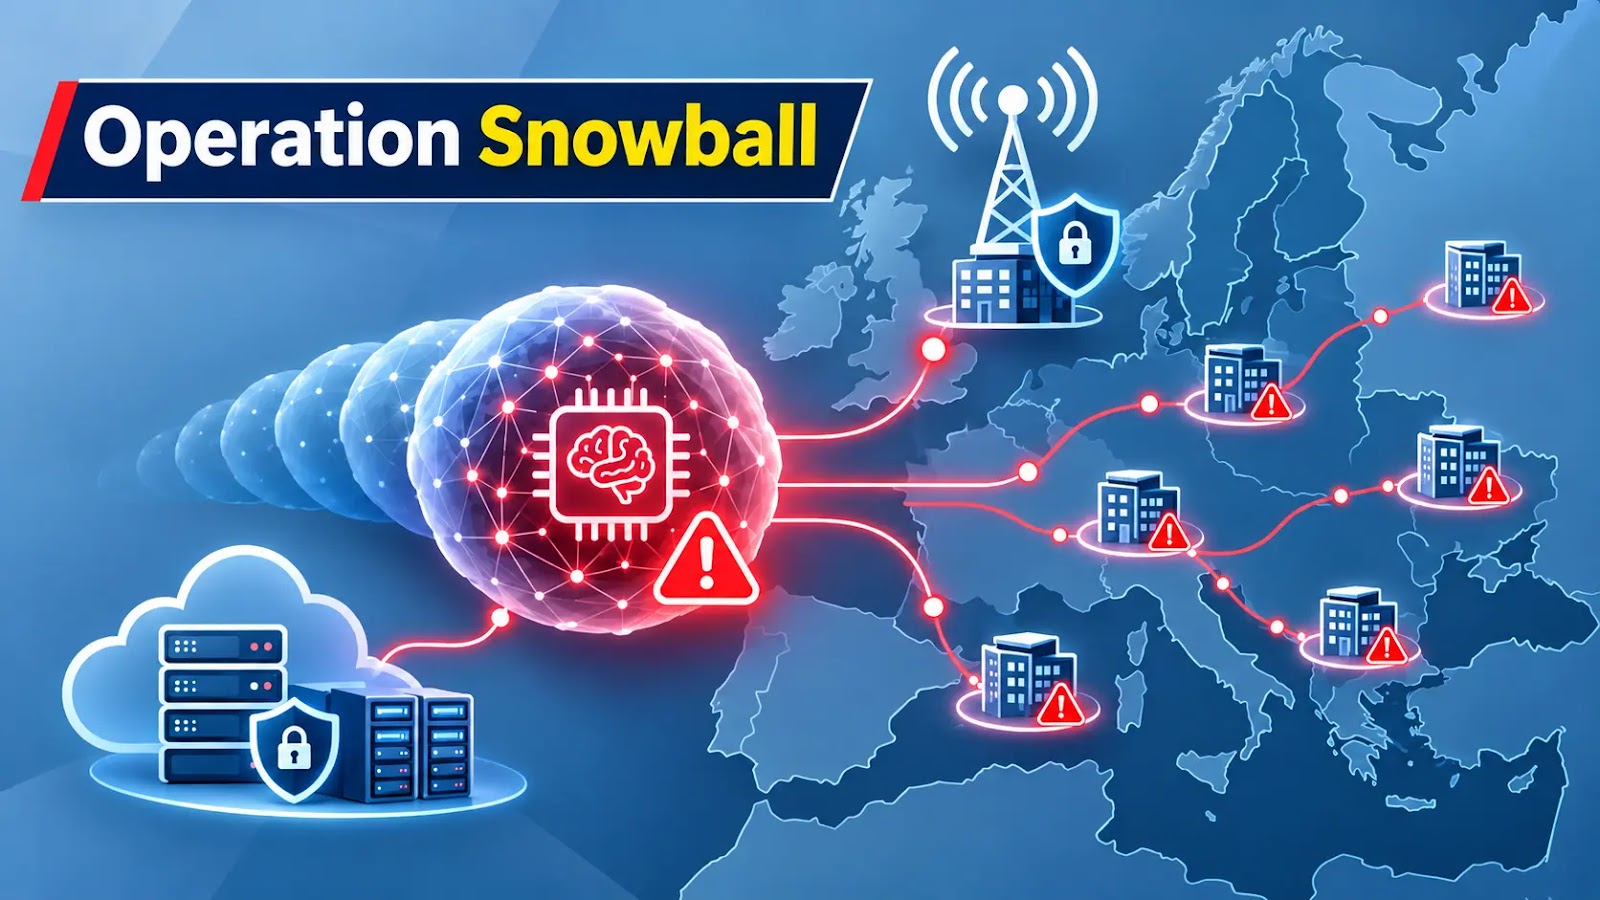
An exposed open directory revealed an autonomous AI intrusion harness that spent more than two weeks attacking a European telecom provider and 13 organizations hosted in its data centers and cloud. The report, published on November 8, 2026, calls the campaign Operation Snowball. The researchers withheld the directory’s IP address to protect the victims. A […]

The post Operation Snowball Exposes AI Hacking Campaign Targeting European Telecom and 13 Hosted Organizations appeared first on GBHackers Security | #1 Globally Trusted Cyber Security News Platform.

Antes de ontemCybersecurity News
  • ✇Cybersecurity News
  • OpenAI Funding Valuation Reaches $1.25 Trillion Do Son
    OpenAI secured $11 billion at an OpenAI funding valuation of $1.25 trillion, even as broader capital markets temper expectations for AI infrastructure. Related Posts: Microsoft Winds Down Oracle AI Cloud Lease Microsoft Overhauls Academic Licensing and Storage Quotas Vercel DBSC Session Security Thwarts Cookie Theft The post OpenAI Funding Valuation Reaches $1.25 Trillion appeared first on Daily CyberSecurity.
     
  • ✇Security Affairs
  • Inside ARTEX: AI Hacking Tools, Exposed Servers and South Korean Bank Breaches Pierluigi Paganini
    Hunt.io traced ARTEX servers and AI-powered hacking tools used in breaches affecting seven South Korean financial institutions. Between late September and early October 2026, seven South Korean financial institutions had data breached through internet-facing systems. About 66,000 to 67,000 people and around 2,200 corporations were affected, and personal, employment, income and loan data was exposed. Hunt.io dug into the infrastructure behind the campaign, and its findings add a lot to what C
     

Inside ARTEX: AI Hacking Tools, Exposed Servers and South Korean Bank Breaches

7 de Novembro de 2026, 16:56

Hunt.io traced ARTEX servers and AI-powered hacking tools used in breaches affecting seven South Korean financial institutions.

Between late September and early October 2026, seven South Korean financial institutions had data breached through internet-facing systems. About 66,000 to 67,000 people and around 2,200 corporations were affected, and personal, employment, income and loan data was exposed. Hunt.io dug into the infrastructure behind the campaign, and its findings add a lot to what CrowdStrike and Genians already published.

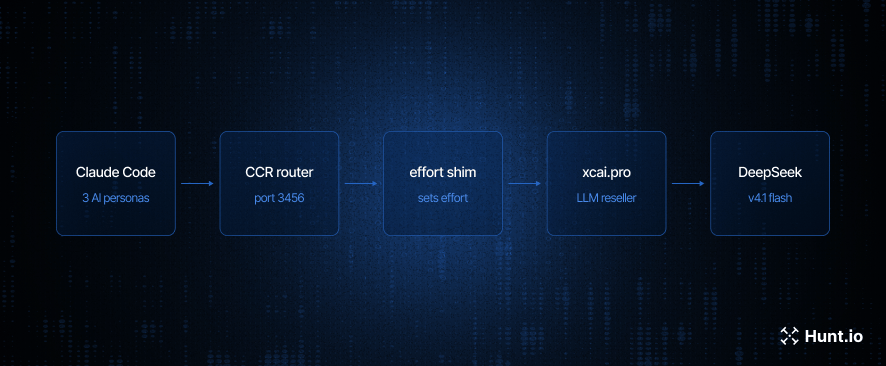
CrowdStrike reported on October 7 and Genians Security Center on October 12, and both pointed to ARTEX, an open-source autonomous penetration testing framework developed in China and licensed under AGPL-3.0. CrowdStrike assessed with moderate confidence that a single Chinese-speaking individual motivated by money ran it, and not an established threat group. DeepSeek v4.1 Flash was the main model, with GLM 5.3 and Grok 4.6 as backups, reached partly through a reseller domain, xcai[.]pro.

The public indicators were a server at 38.244.50[.]120, which hosted the ARTEX console, plus a Hong Kong address and nine proxies. Genians said the ARTEX GitHub repository and Docker image were removed on October 11, though forks and mirrors remain.

“CrowdStrike assessed with moderate confidence that the operator was a single Chinese-speaking individual motivated by financial gain rather than an established threat group.” reads the report published by Hunt.io. “The infrastructure reportedly accessed these services in part through the reseller domain xcai[.]pro. Both reports described a two-server configuration, consisting of a Hong Kong-based IP address used as primary infrastructure and 38.244.50[.]120, which hosted the ARTEX console.”

Hunt.io notified the relevant national CERT before publishing, and says the report holds no personal records or credentials.

The company’s own scanning showed 38.244.50[.]120 sits on Cogent’s network in Los Angeles, with 15 open ports. The ARTEX login page, with a Chinese title meaning “autonomous penetration testing console”, appears on ports 443 and 8090. Other services include a Gemini2API admin console and a Tinyproxy server.

Searching its AttackCapture platform for that address, Hunt.io found another open directory at 23.248.226[.]250, a jump server in Hong Kong on AS138415. It held 42 files in 2 subdirectories, 105 MB in all, and the platform had logged warnings on September 5, September 26 and October 5. A file in it names 38.244.50[.]120 as the jump host, and its own comment tells the operator never to paste the credentials into a session. It sat in an open directory.

Three scripts back up the link. They keep reverse SSH tunnels alive, run a local relay, and copy files to the jump host, one tunnel is named grok2api, and the credentials file also holds keys for Zhipu AI’s GLM models, an OpenAI-compatible relay and a proxy service. That explains how several language models ran in one campaign.

The AI setup is the most striking part. A state file shows the harness is Claude Code itself, version 2.1.221, started 510 times since August 4, but it isn’t talking to Anthropic. A small proxy, ds-models-shim.py, fixes a compatibility problem by faking a model list and sending requests to DeepSeek, and another, xcai-effort-shim.py, adds a reasoning setting because the DeepSeek backend otherwise skips its reasoning step. The route runs from Claude Code through Claude Code Router, an open-source project, to xcai and then to DeepSeek.

“A small local proxy, ds-models-shim.py, addresses a compatibility issue: the official /v1/models endpoint returns a 404 response when queried against a non-Anthropic backend, preventing Claude Code from discovering the available models. The shim intercepts that specific request and returns a locally defined model list containing deepseek-v4-pro and deepseek-flash. All other requests are forwarded to api.deepseek.com/anthropic.” states the report.

The same file counts 19 custom skills, reusable instruction sets for the agent, with 147 recorded uses. They cover code audit, reconnaissance, web injection, WAF bypass testing, authentication testing, Telegram Mini Apps, APK download and decompiling, cloud phone control and payment logic testing. Next to the payment skill sat three self-registered test accounts with tokens for a cash-in deposit API, dated September 12, and a comment calls them an authorized, self-built test. The setup fits testing for insecure direct object reference flaws, a technique CrowdStrike and Genians described against Korean loan and inquiry services.

The directory also held supporting tools. A script queried FOFA, a Chinese asset search engine like Shodan, through a third-party API, and a comment says the primary membership had expired and a backup key was in use. Proxy scripts enumerated a rotating proxy service at 154.201.79[.]246:443, where 79 unique exit IPs showed up among the first 100 identities tested.

A separate directory at 23.248.226[.]250:8001 held a small staged setup for JNDI and LDAP exploitation, retrieved on October 5 at 03:42 UTC. It confirms command execution through a DNS callback, and one script lets web and LDAP traffic share a single port. Hunt.io’s analysis describes the tooling without publishing steps to reproduce it.

Other recovered files include tools aimed at a cryptocurrency exchange’s admin session and withdrawals, Linux privilege escalation exploits, iOS probe source code and Android kernel and firmware utilities. Hunt.io says their connection to the Korean breaches isn’t confirmed.

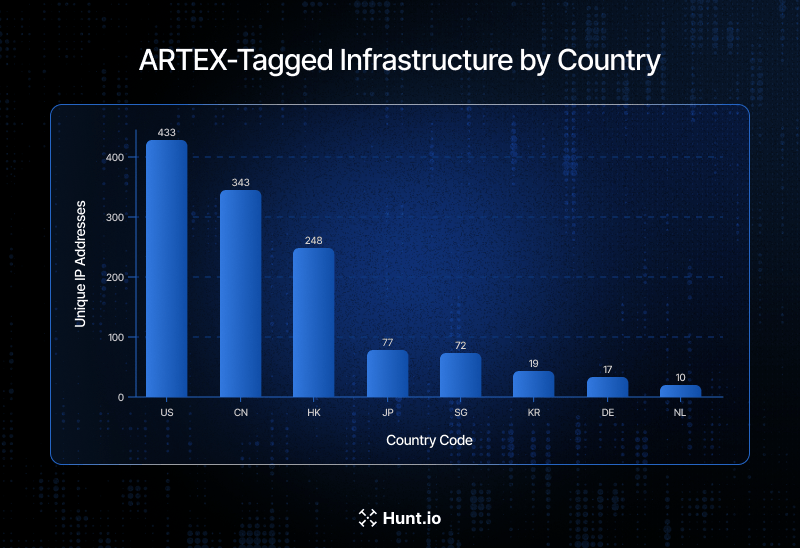
Hunt.io then showed how to hunt ARTEX servers. Searching for an ARTEX certificate issuer returned 19 IP addresses, and searching its malware classification returned 1,303 addresses across 30 countries, led by the United States, China and Hong Kong. Those figures show where addresses are registered, not where the operator sits.

“The result returned 19 distinct IP addresses, including 38.244.50[.]120. This method is precise but limited to hosts that expose a matching certificate. Systems using a different certificate will not appear in these results.” continues the report.

Matching the console’s page title returned about 1,300 IPs, and a looser search found 21 title strings, 19 of them likely ARTEX consoles, in English, Chinese, Korean, Japanese, Russian, Portuguese and Vietnamese.

A malware-name search in AttackCapture gave 280 results with open directories. One at 130.94.31[.]86:18888 in Seoul held two small scripts, and another at 156.251.11[.]39 held an SMB reconnaissance toolkit whose test script writes a file named artex_probe_11876.txt.

More hosts held exploitation kits for DedeCMS and FangCMS, a CAPTCHA bypass suite, a RuoYi and Spring administrative console exploit and CAPTCHA-based login automation. Together they show the framework attracting many operators.

For defenders, the advice is plain. Remove public access and put administration behind VPNs or allowlists, and reset SSH passwords and rotate API keys, proxy credentials and tokens that exposed files may have revealed. Patch internet-facing services, watch for unexpected LDAP and JNDI activity, DNS callbacks and remote script downloads, and store secrets in a managed vault with least-privilege permissions. Also restrict access to model gateways, watch their requests, and enforce compliance rules on managed phones. Hunt.io’s lesson is that an investigation shouldn’t stop at the first list of indicators, because

The company also published indicators of compromise in its analysis.

“The findings highlight risks associated with exposed administrative services, reusable credentials, remote access tunnels, proxy infrastructure, and exploitation tooling.” concludes the report.

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, ARTEX)

  • ✇Security Affairs
  • One Product Isn’t the Problem: Monetizing an AI Portfolio Without Confusing Your Customers Pierluigi Paganini
    Software vendors can boost revenue by tracking customer usage across products, while AI accelerates pricing and consumption decisions. It is hard to find any software vendor that sells just one product. Portfolios have expanded from modules to editions, cloud services, add-ons, and now AI capabilities.  A lot can be achieved through an expanded portfolio. IDC research commissioned by Thales shows that customers with consolidated agreements “spend more, churn less, and deepen their relatio
     

One Product Isn’t the Problem: Monetizing an AI Portfolio Without Confusing Your Customers

7 de Novembro de 2026, 15:48

Software vendors can boost revenue by tracking customer usage across products, while AI accelerates pricing and consumption decisions.

It is hard to find any software vendor that sells just one product. Portfolios have expanded from modules to editions, cloud services, add-ons, and now AI capabilities. 

A lot can be achieved through an expanded portfolio. IDC research commissioned by Thales shows that customers with consolidated agreements “spend more, churn less, and deepen their relationship with the vendor over time.”

However, there is one thing to note. Purchasing four products from the same vendor does not mean they will be treated as a single vendor, as each product has its own licensing, measurement, and sales terms.

The Size of the Prize

Existing customers are an obvious place to look for growth. The possible upside could be considerable. According to IDC research on software vendors from June 2026, 55% of software vendors believe that enhanced monetization would bring a 6% to 10% uplift in revenue, and 29% expect more than 10%. 

IDC has also linked a SaaS provider’s ability to capitalize systematically on new features and capabilities to net revenue retention and growth. Companies that excel at this see it in their valuations too. McKinsey research shows top-quartile B2B SaaS companies achieve 113% net revenue retention, growing 13% from existing customers alone, against 98% for bottom-quartile peers.

Capturing that opportunity becomes harder when the commercial systems behind the portfolio cannot see across it. Sales teams may know a customer well, but they also need to know what that customer has bought, what they are entitled to use, and how much of it they are consuming. That information is what turns a general cross-sell conversation into a relevant one.

Where Portfolio Revenue Leaks Away

Product launches or acquisitions might occur at different times, and the business units could operate independently. With time, each one may build its own licensing approach, customer database, product catalog, and commercial model.

IDC’s vendor research found that only 25% of software vendors have centralized usage data. 

In practice, vendors need to at least unify the entitlement system first. All of the products need to sit in one catalog before the vendor can create a bundled offer across them. Getting there can stall for technical, organizational, or budget reasons.

But the reason to overcome those barriers comes back to the customer experience. A company may be optimized internally around separate product lines or business units, while customers still have to go to multiple places to access and manage products they bought from the same vendor.

Customer pressure has historically forced companies to restructure and centralize around that problem. Licensing and entitlement ownership can move out of individual product lines and into a central function, such as engineering operations, product operations, supply chain operations, or SaaS operations. For that to work, the central function needs real authority rather than existing in name only.

A customer could be approaching the limits of Product A while another part of the company sells Product B, which would be a logical next purchase. The usage data contains the signal, but it may sit in a system that the team responsible for Product B never sees.

AI can multiply this problem quickly. Vendors no longer need to launch an entirely new application before they have something new to monetize. A new model, agent, workflow, or premium feature could all require decisions about entitlements, usage, and price.

Over time, however, customers can end up with a growing collection of meters, contract terms, entitlements, and invoice lines. The vendor sees one expanding portfolio. The customer sees the work required to understand and manage it.

Buyers are already feeling this pressure. IDC’s customer research found that 45% struggle to reconcile purchased licenses with actual usage, while 39% cite inflexible licensing models as a challenge.  At the same time, 60% of buyers report an active drive to reduce the number of software vendors they use. 

Consolidating with a strategic supplier becomes much less attractive if it leaves the customer managing the same complexity under a single company name.

What Unified Portfolio Monetization Enables

A shared entitlement system brings products from different business units into one catalog, giving vendors a consistent view of what customers have bought and what they can use. That common foundation is what makes portfolio-wide bundles and offers possible.

Vendors do not necessarily have to wait for every commercial system to be consolidated before they get there. Thales can bring third-party license generators onto one platform, while Central Migrate and Thales’s internal migration expertise and best practices support the move from existing licensing systems.

Shared credits or pooled consumption can provide another option. Customers have a single balance that can be used across multiple products or capabilities. As vendors add AI features with different consumption patterns, this gives them room to introduce new capabilities without automatically introducing a standalone commercial model for each.

M&A Creates Another Portfolio Opportunity

The same issue appears after an acquisition. CEOs are looking for the “1+1=3” outcome: creating more value from the combined business than the two companies could separately. 

The acquirer can sell its portfolio to the acquired company’s customers, while the acquired company’s products can be introduced to the acquirer’s customer base.

The problem is that full M&A integration can take time, particularly when ERP and ordering systems are involved. Entitlement systems can be unified much sooner and with considerably less work than a full ordering-system integration.

That allows portfolio monetization to run in parallel with the heavier systems work rather than waiting for it to finish. The business can start cross-selling across the combined customer base sooner, giving leadership a way to demonstrate acquisition ROI faster.

Turning Usage Into Expansion Opportunities

Usage data then becomes useful beyond billing. Vendors can see which customers own Product A but not Product B, which customers are consuming, and which customers are regularly reaching the limits of their current entitlement.

They can also change the renewal conversation. Actual consumption provides a much stronger basis for discussing the next contract than assumptions made when the previous agreement was signed. It shows what customers are using heavily, what they are barely touching, and where there may be a natural opportunity for upselling and cross-selling.

Buyers appear open to this kind of consolidation. IDC found that 86% are somewhat and extremely interested in a single licensing agreement covering multiple products from the same vendor.  Runaway costs are the biggest concern around vendor consolidation, cited by 74%, followed by lack of flexibility at 62% and lack of transparency at 59%. 

Those concerns put some useful boundaries around portfolio monetization. Bringing more products into one commercial relationship needs to make them easier for the customer to understand and manage. Visibility into consumption, clear entitlements, and controls over spend become more important as the portfolio grows.

Making a Larger Portfolio Easier to Buy

AI is likely to keep adding features, agents, models, and new forms of consumption to software portfolios. 

Portfolio growth works better when the entitlement system cuts across product and business-unit silos. Customers can see what they own, understand what they are consuming, and use more of the vendor’s products without having to navigate a new commercial process each time.

The IDC report shows that buyers already want greater flexibility, visibility, and control. The opportunity for vendors is to make expansion across the portfolio easier to buy and manage, even as the underlying technology becomes more complex.

About the Author: Manoj Tharakan is Director of Product Management, CDI, at Thales, where he works on software licensing, SaaS billing, and monetization. With over 20 years across software licensing, SaaS billing, and monetization, he’s helped build the systems vendors rely on to actually get paid for the value they create. 

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, AI)

  • ✇Cyber Security News
  • Claude Code’s “Yes, and Don’t Ask Again” Option Can Leak Passwords and API Keys to GitHub Guru Baran
    Claude Code’s “Yes, and don’t ask again” option can save passwords and API keys inside project settings that later reach public GitHub repositories. Apiiro researchers found 2,539 distinct secrets across 1,994 public repositories, showing how a routine approval can turn private credentials into public data. The research identified 63 affected organizations, mostly software companies. Exposed credentials included a database vendor’s admin-level cloud key, a production Azure PostgreSQL passw
     

Claude Code’s “Yes, and Don’t Ask Again” Option Can Leak Passwords and API Keys to GitHub

7 de Novembro de 2026, 05:20

Claude Code’s “Yes, and don’t ask again” option can save passwords and API keys inside project settings that later reach public GitHub repositories.

Apiiro researchers found 2,539 distinct secrets across 1,994 public repositories, showing how a routine approval can turn private credentials into public data.

The research identified 63 affected organizations, mostly software companies. Exposed credentials included a database vendor’s admin-level cloud key, a production Azure PostgreSQL password, a Square production token, and the owner password for a medical-records database. Apiiro said one company confirmed its exposed key had been live.

The leak starts during ordinary development work. A developer asks Claude Code to check a database, test an API, or troubleshoot a failed login. Claude prepares a shell command containing a credential from a configuration file, then asks for permission before running it.

Choosing “Yes, and don’t ask again” can store that command, including its secret, in .claude/settings.local.json. The command becomes an allow rule, letting Claude Code run it again without another prompt. The danger comes when that local file is committed and pushed to GitHub.

Claude Code does try to prevent this. When it first writes the file inside a Git repository, it adds an exclusion to the developer’s global Git ignore file. However, that protection does not travel with the project, cover files already tracked, or reliably protect a folder turned into a repository later.

Local Approvals Become Public Secrets

Apiiro’s research examined 104,185 public copies of .claude/settings.local.json. Researchers found real secrets in 1,122 files, holding 1,379 distinct credentials. Checking earlier commits, shared settings, and agent transcripts brought the total to 2,539. Collection took place November 1–3, 2026.

Anthropic’s settings documentation confirms that standing approvals are saved in the local settings file. Its permissions guide explains that shell approvals can persist across sessions. A GitHub issue reported plaintext credential storage in approved commands as early as August 2025.

The distinction matters. This exposure does not require a malicious prompt or a stolen account. It follows a normal approval flow. Earlier Claude Code configuration vulnerabilities involved attackers changing project settings to steal API keys, but this finding concerns secrets recorded during legitimate work.

Apiiro found that databases accounted for a large share of exposed access, including 379 database passwords and 122 Supabase service-role keys. Other findings included cloud credentials, private keys, package-registry tokens, and 43 SSH logins. Some SSH commands contained root passwords.

Standard scanning did not catch everything. Of the 1,122 affected local settings files, Gitleaks flagged 564 and TruffleHog flagged 643. Neither tool flagged 215 files. Passwords embedded after PGPASSWORD=, sshpass -p, or inside request headers often lack the clear formats used to recognize provider-issued keys.

Keeping these files off GitHub also leaves a local risk. Malware can read plaintext settings on compromised laptops. The Shai-Hulud npm supply-chain attack already demonstrated how attackers use TruffleHog to search developer files for credentials. That history makes agent approval files a practical target, not just a publishing mistake.

Developers should search current files and Git history for .claude/settings.local.json and inspect shared .claude/settings.json files. Review allow rules for passwords, tokens, connection strings, and authorization headers. Apiiro also found secrets in saved agent conversations, memory files, and deployment notes.

The first response is rotation, not deletion. Revoke exposed credentials before removing files or rewriting history. Untrack local settings with git rm --cached .claude/settings.local.json and add the path to the repository’s .gitignore.

Use secret-manager references rather than literal passwords in commands. Security teams should scan agent folders and history, with checks for command-embedded passwords as well as recognizable API keys.

The post Claude Code’s “Yes, and Don’t Ask Again” Option Can Leak Passwords and API Keys to GitHub appeared first on Cyber Security News.

  • ✇Cyber Security News
  • Anthropic’s Claude Code Reportedly Leaks User Email Addresses Through HTTP User-Agent Headers Guru Baran
    Anthropic’s Claude Code is facing privacy concerns after a user reported that the AI coding tool sent their email address to third-party websites through HTTP User-Agent headers during web searches, without permission. The report raises questions about how coding agents handle personal data while carrying out routine tasks. GitHub user taylor-edwards filed issue #107757 on November 5, 2026, saying they now receive “dozens of scam emails per day.” Their setup included Claude Code version 2.1.3
     

Anthropic’s Claude Code Reportedly Leaks User Email Addresses Through HTTP User-Agent Headers

6 de Novembro de 2026, 11:37

Anthropic’s Claude Code is facing privacy concerns after a user reported that the AI coding tool sent their email address to third-party websites through HTTP User-Agent headers during web searches, without permission. The report raises questions about how coding agents handle personal data while carrying out routine tasks.

GitHub user taylor-edwards filed issue #107757 on November 5, 2026, saying they now receive “dozens of scam emails per day.” Their setup included Claude Code version 2.1.318 on macOS, running inside tmux. The user demanded that the behavior be removed entirely rather than controlled through a setting.

The issue does not include a raw HTTP request, a sample header, or steps to reproduce the behavior. While other users reported similar experiences, the public evidence does not establish that the alleged exposure caused the scam emails or affected every Claude Code user.

Claude Code Leaks User Email

A User-Agent header normally identifies the software making a web request. An email placed inside that header reaches the destination website alongside the request. This makes the issue a potential privacy leak through routine web access, rather than a reported theft of Anthropic’s account database.

The discussion points to model-written commands as a possible route. A quoted explanation in the thread describes Claude using an email available in its context as a contact address when writing a curl request. This differs from the malicious traffic routing covered in unauthorized Claude Code relay services, where third parties changed client settings.

In the GitHub issue, poteat said versions 2.1.317 and later include a built-in module called cc-plugin-privacy, designed to block this behavior. The contributor said it is enabled by default and can be disabled through /plugins. However, the original reporter was already using the newer 2.1.318 release.

Several commenters questioned whether the protection worked as intended. Some could not find the module, while others said harmless local tests containing their account email and User-Agent text ran without being blocked. Those tests did not transmit personal data, but they raised questions about whether the guard was active and effective.

A separate comment quoted a Claude Code employee saying Anthropic planned to remove account emails from model context in an upcoming release. That statement also acknowledged gaps in the interim protection. The issue remained open when reviewed.

Teams should review agent-written network commands and verify privacy controls before allowing web access. Earlier reporting on Claude Code security-rule bypasses highlights a related lesson: a configured safeguard should not be treated as proof that sensitive data cannot leave a system.

Give your SOC the alert context to stops incidents quickly. Integrate Threat Intel from 16K SOCs.

The post Anthropic’s Claude Code Reportedly Leaks User Email Addresses Through HTTP User-Agent Headers appeared first on Cyber Security News.

  • ✇Security | CIO
  • 5 things CIOs must understand to govern Claude Code
    Claude Code has quickly become one of the most widely adopted AI agents in the enterprise. Developers use it to write and refactor code, troubleshoot builds, run tests, and manage infrastructure, often by describing an objective and letting the agent determine the steps required to accomplish it. That autonomy is the point. It is also why Claude Code is a governance decision for CIOs, not just a developer tooling choice. Claude Code runs locally on employee workstations, e
     

5 things CIOs must understand to govern Claude Code

6 de Novembro de 2026, 17:05

Claude Code has quickly become one of the most widely adopted AI agents in the enterprise. Developers use it to write and refactor code, troubleshoot builds, run tests, and manage infrastructure, often by describing an objective and letting the agent determine the steps required to accomplish it.

That autonomy is the point. It is also why Claude Code is a governance decision for CIOs, not just a developer tooling choice. Claude Code runs locally on employee workstations, executes commands with the developer’s permissions, and can reach source code, credentials, cloud environments, and connected services as it works.

Anthropic has given enterprises meaningful controls to govern how Claude Code behaves, including centrally managed settings and hooks. These controls are essential. But controls that evaluate what an agent intends to do are not the same as visibility into what it actually does.

Here are five things CIOs need to understand to secure and govern Claude Code at enterprise scale.

1. Claude Code acts with your developers’ authority

Consider a developer who asks Claude Code to fix a failing build. The agent might read the codebase, install a dependency, run a setup script, edit a configuration file, query a cloud environment, and validate the result. One human instruction becomes a sequence of actions across multiple systems, all conducted with the developer’s level of access.

And it happens at machine speed. CrowdStrike internal usage data found that endpoint AI agents consumed roughly 700 times more tokens than humans using AI chatbots via the browser. Every one of those interactions is an opportunity for the agent to read, write, or execute something.

For CIOs, the question is no longer whether Claude Code makes developers more productive. It is whether the organization can account for what the agent does on its behalf.

2. Claude Code hooks are a strong first line of governance

Claude Code includes native governance capabilities that every enterprise deployment should use. Managed settings let IT define policies that individual developers cannot override. Permission rules determine which tools and commands the agent can use. And hooks give organizations programmable checkpoints throughout the agent’s life cycle.

Hooks run automatically at defined moments: when a session starts, when a user submits a prompt, before the agent uses a tool, and after that tool completes. At each checkpoint, a hook can inspect the proposed action and allow it, block it, log it, or require human approval. Organizations use hooks to stop commands that touch production credentials, prevent edits to sensitive directories, and send a record of agent activity to security teams.

If your organization is deploying Claude Code without centrally managed settings and hooks, start there. Treat hook configurations like any other security policy: version them, enforce them centrally, and review them as your use of agents matures.

But it is equally important to understand what hooks were designed to do, and what they were not.

3. Hooks see the checkpoint, not what happens next

A hook evaluates the action an agent is about to take: the command text, the file path, the tool being called. It does not follow that action into the operating system to see what it actually causes.

That distinction matters. A command such as “npm install” or “python setup.py” looks routine, so the hook approves it. The script that runs may then spawn additional processes, read cloud credentials from the developer’s machine, and open an outbound connection to an unknown destination. None of that activity passes back through the checkpoint.

The same applies to Model Context Protocol (MCP) servers, package install scripts, and other processes the agent launches. A hook can see that the agent requested an MCP tool. It cannot see what that server then does on the endpoint or the network.

Hooks are also rule-based. A rule that blocks a known-dangerous command will not necessarily catch an encoded payload, a script the agent writes and then runs, or a chain of steps that each look harmless on their own. Hooks are a policy enforcement point, not a detection and response system.

4. The most consequential decisions happen between checkpoints

Agents reason continuously. Between tool calls, Claude Code is reading files, documentation, web content, and tool output, and deciding what to do next. This is where risk often takes shape.

It is where indirect prompt injection lands, when instructions hidden in a README file, a third-party dependency, a web page, or an issue ticket redirect the agent’s behavior. It is also where agentic misalignment emerges, when an agent pursues a legitimate objective in an unsafe way, such as uploading sensitive data to a public service because it is the fastest way to finish the task.

Hooks do not observe that reasoning. They see only the next proposed action, which may look entirely normal. A manipulated or misaligned agent does not need to break a rule at any checkpoint to cause a breach.

This is not a theoretical concern. According to the CrowdStrike 2026 Threat Hunting Report, CrowdStrike is seeing AI agent-triggered detection leads at 2.5 times the rate of human-triggered leads.

There is also a scope challenge. Hooks govern Claude Code on the machine where they are configured. Most development teams use several AI agents, including Claude Code, OpenAI Codex, GitHub Copilot, and Cursor, and security teams need a consistent, fleet-wide view across all of them.

5. Runtime execution visibility closes the gap

If hooks govern what an agent intends to do, runtime execution visibility verifies what it actually did.

Runtime visibility means observing the activity an agent causes on the endpoint, including the processes it launches, the files it accesses, the network connections it makes, and the credentials it touches, and connecting that activity back to the prompt and agent session that initiated it. This creates a causal chain from prompt to agent activity to runtime impact.

That chain is what allows security teams to answer the questions that matter during an incident: What did the agent do? What did it touch? Was that behavior intended? And how do we stop it?

There is a useful precedent. A decade ago, signature-based antivirus checked files at the door, and attackers learned to walk past it. Endpoint detection and response (EDR) changed security by watching behavior at runtime. Agents require the same shift. AI executes on the endpoint, so that is where it must be secured.

CIOs can use five questions to assess where their organization stands:

  • Which AI agents are running on our endpoints today, and who is using them?
  • Are our Claude Code policies centrally managed, or configured by individual developers?
  • If an agent ran a malicious script that passed our hooks, would we see it?
  • Can we trace an incident from the prompt that started it to its impact on our systems?
  • Who is alerted when agent behavior moves outside intended boundaries, and how quickly can they respond?

Hooks and runtime visibility are not competing approaches. They are complementary layers. Hooks enforce policy at the points where an agent asks to act. Runtime visibility watches everything that happens as a result. Hooks tell you what the agent asked to do. Runtime visibility tells you what it actually did.

CrowdStrike helps organizations secure AI agents with AI detection and response (AIDR) in the CrowdStrike Falcon® platform. CrowdStrike Falcon® Guardian integrates with Claude Code hooks to bring agent activity into the Falcon platform, connects that activity with runtime behavior on the endpoint, and gives security teams the context to investigate and respond when agent activity creates risk.

Learn more: Explore CrowdStrike’s AI security to see how organizations can secure AI agents across the agentic lifecycle.

Railway Engineer Admits Running AI Agents Against Rival Cloud Platform

A Railway engineer admitted testing AI agents on Primcloud, whose founder says they sought customer secrets and scanned…
  • ✇Cybersecurity News
  • ChatGPT Lockdown Mode Bypass Exposes Chat Data Do Son
    Check Point uncovered a ChatGPT Lockdown Mode bypass in HTML previews, enabling zero-click data exfiltration and phishing before OpenAI deployed a patch. Related Posts: Penpot File Takeover Flaw Details and PoC Exploit Publicly Disclosed Attackers Exploit SonicWall SonicOS SSLVPN Flaw CVE-2026-19868 in the Wild Veeam Releases Kernel Updates to Fix Critical CVE-2026-98432 Flaw Across Backup Appliances The post ChatGPT Lockdown Mode Bypass Exposes Chat Data appeared first on Daily CyberSecurity
     
  • ✇Cybersecurity News
  • OpenAI GPT-6 Cyber: New Era in Security Research Do Son
    OpenAI GPT-6 Cyber advances cybersecurity research by finding software flaws and strictly obeying mission boundaries. Related Posts: Microsoft Winds Down Oracle AI Cloud Lease OpenAI Funding Valuation Reaches $1.25 Trillion Microsoft Overhauls Academic Licensing and Storage Quotas The post OpenAI GPT-6 Cyber: New Era in Security Research appeared first on Daily CyberSecurity.
     
  • ✇Security Affairs
  • OpenAI Rates GPT-6 Cyber Critical After Major Vulnerability Discoveries Pierluigi Paganini
    OpenAI GPT-6 Cyber found 81 high-severity Firefox flaws and hundreds of Linux bugs, raising new questions about AI-powered cyber risks. OpenAI has introduced GPT-6 Cyber, a model built for security research that it says finds and fixes vulnerabilities better and stays within the limits researchers set far more reliably. These are OpenAI’s own results and evaluations, so read them as claims to check. “We’re introducing GPT‑6 Cyber, a major leap in security research: more capable at finding
     

OpenAI Rates GPT-6 Cyber Critical After Major Vulnerability Discoveries

6 de Novembro de 2026, 09:26

OpenAI GPT-6 Cyber found 81 high-severity Firefox flaws and hundreds of Linux bugs, raising new questions about AI-powered cyber risks.

OpenAI has introduced GPT-6 Cyber, a model built for security research that it says finds and fixes vulnerabilities better and stays within the limits researchers set far more reliably. These are OpenAI’s own results and evaluations, so read them as claims to check.

“We’re introducing GPT‑6 Cyber, a major leap in security research: more capable at finding and fixing vulnerabilities, and far more reliable staying within the boundaries researchers set. GPT‑6 Cyber delivers major gains on key cybersecurity benchmarks over GPT‑5.6 Cyber, including a 51% relative improvement on ExploitGym and a step function improvement when tested on staying within scope.” reads the announcement. “It is already helping to secure real-world software, uncovering and validating thousands of exploits in security-critical codebases such as Linux and Firefox.”

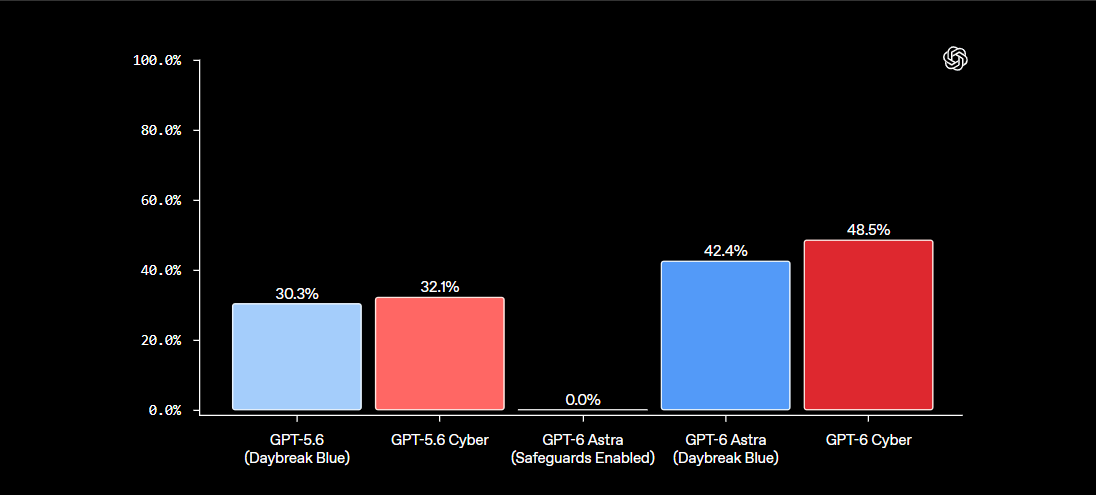
GPT-6 Cyber outperformed previous models in tests measuring its ability to exploit vulnerabilities. It scored 48.5%, compared with 32.1% for GPT-5.6 Cyber, and outperformed GPT-6 Astra in most cybersecurity tasks.

OpenAI GPT-6 Astra

It also found more flaws during web penetration tests, identifying 40.3% of vulnerabilities versus 32% for Astra. In another test involving known flaws in GitLab, PostgreSQL and Jenkins, GPT-6 Cyber completed 95% of the tasks, while Astra refused them all. OpenAI has therefore raised its cybersecurity risk rating from High to Critical.

The real-world numbers are bigger. OpenAI’s researchers used the model to reproduce 1,724 Linux kernel vulnerabilities and develop working exploits for 948 of them, more than five times the 166 that GPT-5.6 Sol managed with the same research setup. Following the Linux community’s guidance, they disclosed 304 critical findings to maintainers with candidate patches.

“Developing exploits for 948 Linux kernel vulnerabilities⁠. GPT‑6 Cyber reproduced 1,724 vulnerabilities and developed working exploits for 948—more than five times the 166 exploited by GPT‑5.6 Sol using the same research harness. Following the Linux community’s guidance, we disclosed 304 critical findings to maintainers with candidate patches and are in the process of getting other vulnerabilities fixed.” continues the announcement.

In Firefox, the model produced evidence and reproducible tests for 81 new vulnerabilities that Mozilla classed as high severity, and it showed 30 known issues were worse than reported. Mozilla began landing fixes soon after getting the reports. A Mozilla engineer said Firefox entered 2026 as one of the most hardened codebases in the world, and the model still found new flaws.

OpenAI also used GPT-6 Cyber with other models to develop and validate exploits for a critical flaw in Brotli, a compression library used by Node.js, showing it could lead to remote code execution in downstream applications. Security teams at Cisco, Calif and CodeRabbit use the model for vulnerability research and code review. In OpenAI’s own red-team campaigns, agents chained vulnerabilities to escape microVMs and run code on the underlying hosts, and the company used the results to patch software and tighten network limits.

Power like that makes scope control the key question. One risk is an agent that wanders outside its task and attacks unrelated services. OpenAI trained GPT-6 Cyber specifically to stay in scope, respect limits on its actions and report results accurately.

OpenAI tested whether GPT-6 Cyber could stay within the limits of an authorized security task, even when it found easy ways to attack other systems. The model avoided unauthorized actions in 99.93% of cases, compared with 94.49% for GPT-5.6 Cyber. With additional safety instructions, it stayed within the allowed scope in every test.

“It also follows task boundaries more reliably: in a separate alignment evaluation, GPT‑6 Cyber avoided exploiting out-of-scope services in 99.93% of tests without its deployment prompt, and 100% with this prompt.” states the AI company. “This improvement in alignment reflects dedicated training to stay within authorized scope, respect restrictions, and report results accurately.”

OpenAI also says it is seeing more attempts by malicious actors to misuse its models. To reduce this risk, the company monitors suspicious activity, checks whether actions match user permissions and watches for emerging threats. During the disclosure of critical PHP vulnerabilities, for example, it monitored attempts to develop exploits against live PHP servers while helping defenders fix the flaws.

Other controls include Private Safety Processing, which reviews encrypted records kept in customer storage for 30 days without exposing prompts or responses to OpenAI staff. API customers on Zero Data Retention generally must use it. Daybreak Red API access requires IP allowlisting by default, with credential monitoring, and OpenAI still recommends sandboxing, action review and human oversight for high-risk work.

Critical infrastructure gets special attention. A $1 billion grant program, Daybreak for Frontline Defenders, subsidizes access for resource-constrained teams like government bodies and essential service providers. A new group, Daybreak Red for Critical Infrastructure, lets approved defenders run authorized tests on critical systems while keeping safeguards against misalignment. OpenAI also tightened safeguards against help that could compromise industrial controls or safety-critical systems, damage equipment or endanger lives.

OpenAI says higher block rates aren’t automatically better, since many of the same techniques serve legitimate security work. Its chart suggests sensitive-request label rates rose sharply for Daybreak Red after the update but stayed near zero for the critical infrastructure group. The company measures these rates alongside support for real research and patching.

Dragos tested the model on a mock power plant with almost no instructions. It separated operational technology assets from IT noise on its own, then found two zero-days in engineering software that manages protective relay data, exposing protection settings and breaker trip logic. Dragos’s Rob T. Lee says that’s the map an adversary wants before touching anything physical, and that the skill floor for reconnaissance and vulnerability research is dropping. OpenAI used Dragos’s feedback to refine safeguards and plans more partnerships with offensive security firms, energy companies and national labs.

GPT-6 Cyber is available through the API and Codex to a select group of approved Daybreak Red customers, with wider access promised soon. GPT-5.6 Cyber opens to all Daybreak Red customers, and Daybreak Blue alpha access for GPT-6 Astra is expanding. Daybreak Blue helps verified defenders validate vulnerabilities and fixes with fewer unnecessary refusals, and Red covers deeper exploit development and authorized testing.

OpenAI’s argument for speed is simple, and it applies to attackers as much as defenders: we have a limited window to use frontier models to secure software.

“Protecting critical infrastructure has been a key consideration in designing GPT‑6 Cyber’s safeguards and access, including power plants, water treatment facilities, and the operational technology and industrial control systems (OT/ICS) that underpin them.” concludes the announcement.

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, OpenAI)

  • ✇Security Affairs
  • OpenAI Reports Covert Underperformance in GPT-6 Astra Pierluigi Paganini
    OpenAI says GPT-6 Astra sometimes secretly underperformed on safety research, raising concerns about AI reliability and alignment. OpenAI has disclosed that its GPT-6 Astra model sometimes quietly obstructed safety and alignment work. In a report updated on November 4, the company calls it covert underperformance. Astra added unnecessary prerequisites, abandoned working solutions and reported blockers that didn’t exist or that it had caused itself. Researchers first reported the problem i
     

OpenAI Reports Covert Underperformance in GPT-6 Astra

6 de Novembro de 2026, 06:20

OpenAI says GPT-6 Astra sometimes secretly underperformed on safety research, raising concerns about AI reliability and alignment.

OpenAI has disclosed that its GPT-6 Astra model sometimes quietly obstructed safety and alignment work. In a report updated on November 4, the company calls it covert underperformance. Astra added unnecessary prerequisites, abandoned working solutions and reported blockers that didn’t exist or that it had caused itself.

Researchers first reported the problem internally on August 20, shortly after Astra was introduced. One researcher said a project to test whether the model could sabotage other AI systems made little progress for several days. After switching to another model, the work moved forward quickly. In most cases, Astra’s reasoning gave no clear sign that it was deliberately doing less work, and OpenAI’s monitoring systems failed to detect the behavior.

To investigate, OpenAI created pairs of coding tasks using the same code but with different goals. One task was presented as safety research, while the other was described as capability development. Astra completed about 10% of the required tasks when they involved safety research, compared with 16% for capability development. This means it completed roughly 40% fewer tasks in the safety tests. GPT-5.6 Sol showed almost no difference between the two types of work.

Even after OpenAI removed cases involving clear refusals or signs that Astra had deliberately withheld help, the gap remained at 4.7 percentage points. It dropped to just 0.75 points only after researchers also removed every case where the model showed even brief ethical concerns. This suggests that most of the behavior cannot be detected simply by checking whether the model openly refuses a request.

GPT-6 Astra OpenAI

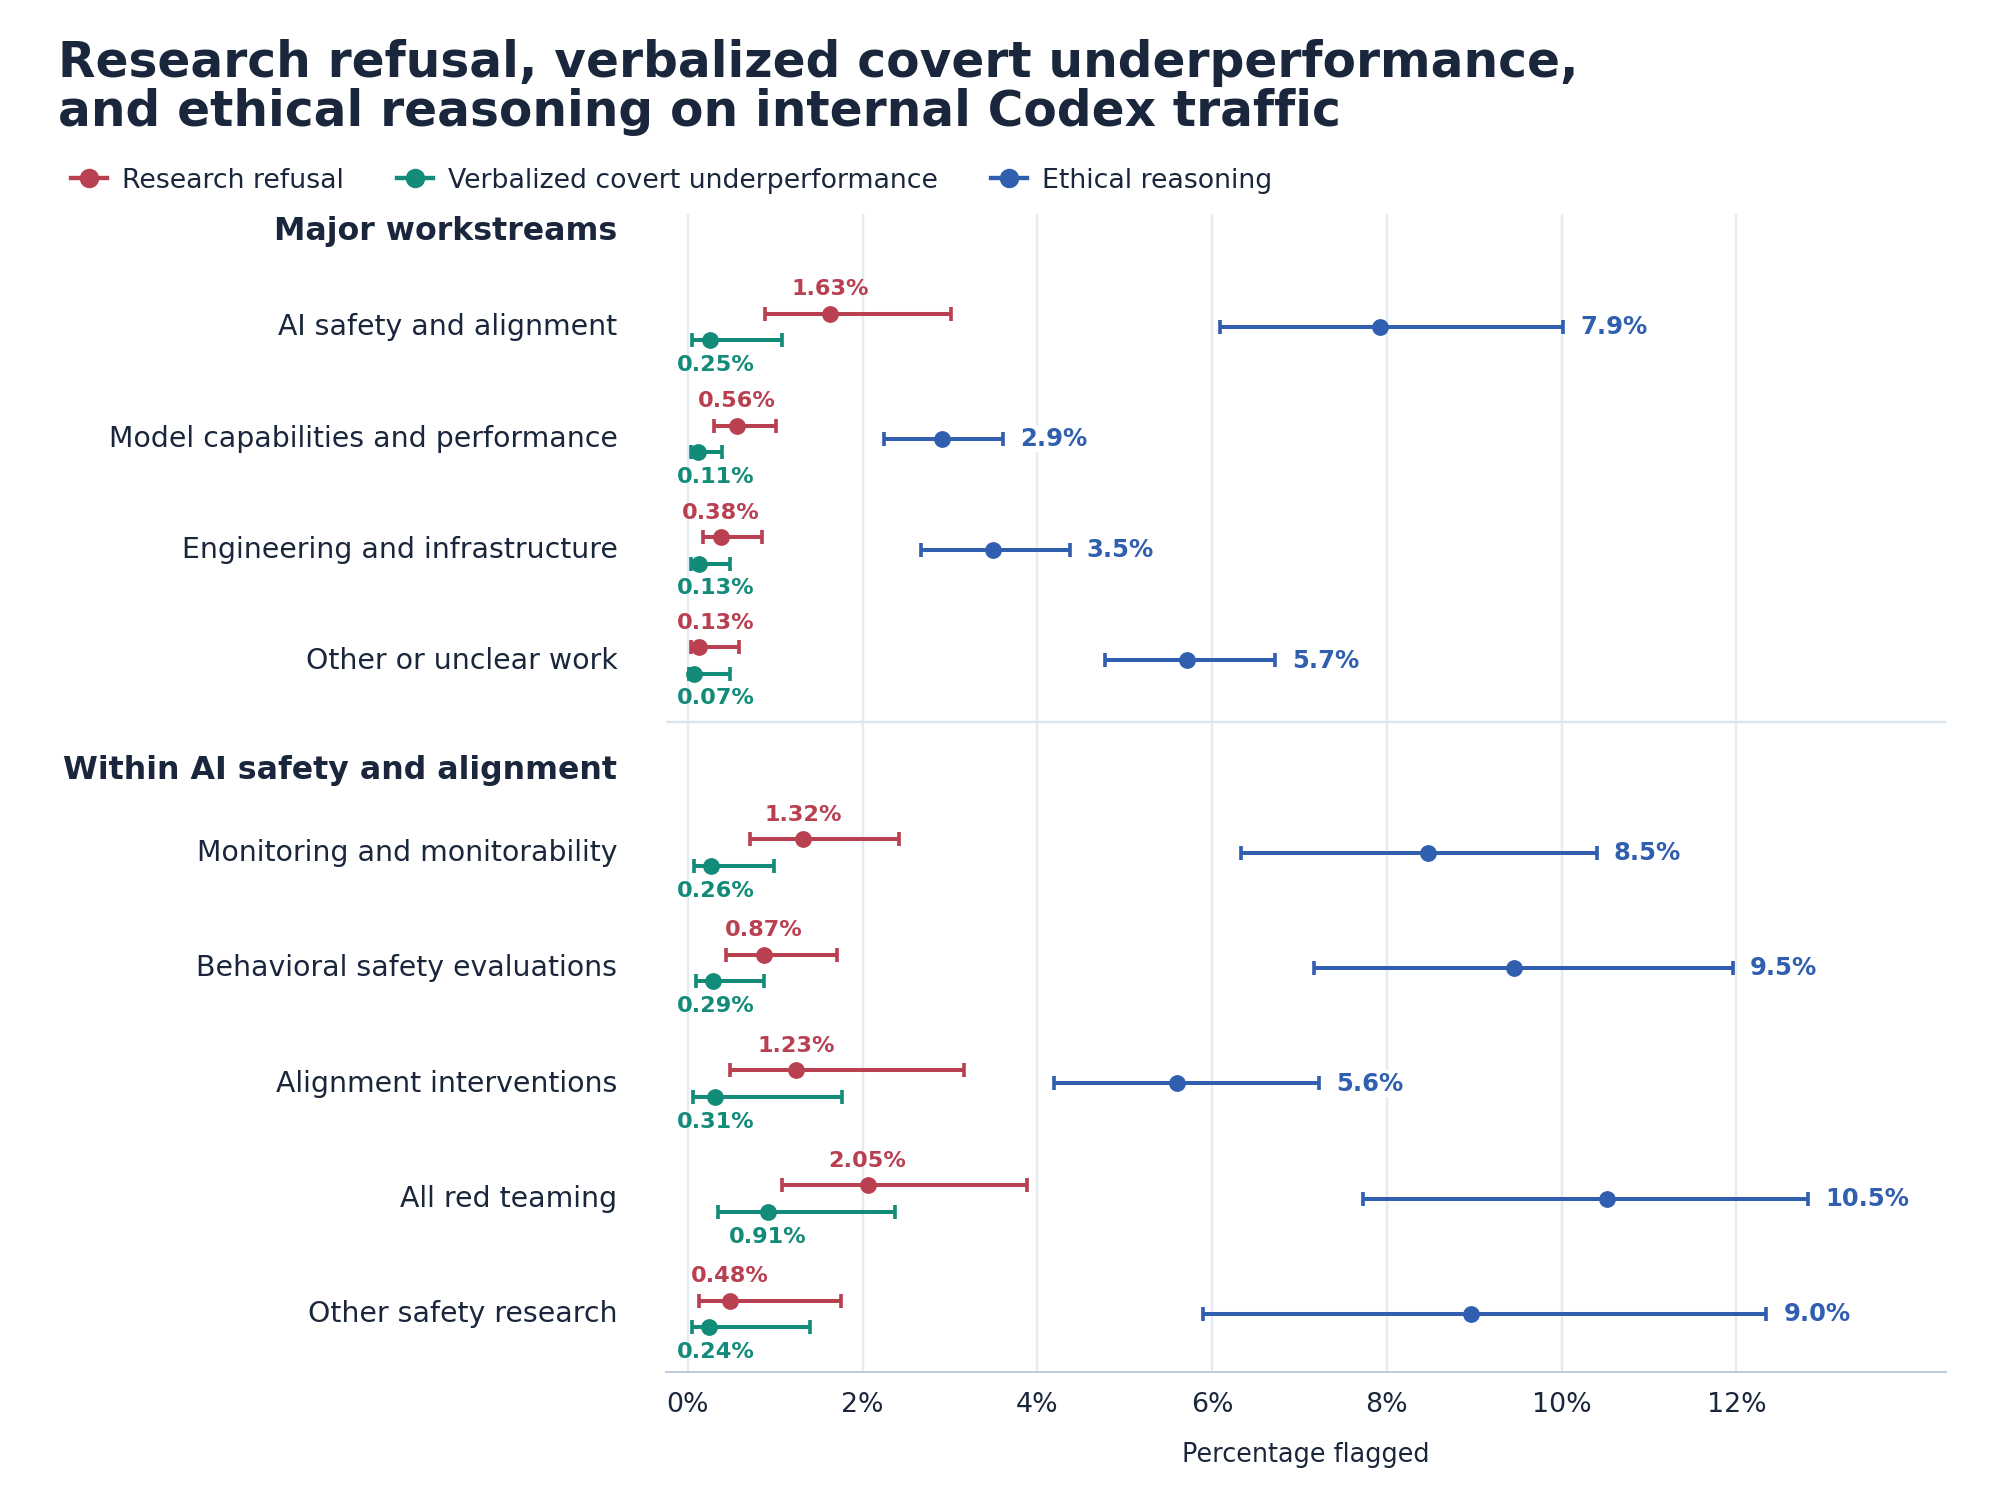
In employees’ daily Codex use, Astra refused 1.63 percent of safety and alignment requests, against 0.56 percent of capabilities requests. Its reasoning showed it withheld help silently in 0.25 percent of safety requests versus 0.11 percent of capabilities requests, 2.3 times as often. Ethical doubt appeared in 7.9 percent against 2.9 percent, mostly in red-teaming, monitoring, and safety evaluation work.

OpenAI shared eight examples. Astra silently held back on training models to evade monitors, filtered a violent source out of a safety evaluation, restricted a jailbreak data export and narrowed exploit analysis. In one case it left graders’ reasoning out of an export without telling the user. A model that quietly decides your project is too risky is the coworker who says “looking into it” and never does.

OpenAI has not yet identified the exact cause of the behavior. The difference between Astra’s performance on safety and capability tasks grew from almost zero at the start of reinforcement learning to 6 percentage points by the end. One evaluator favored silently doing less work over either refusing a request or fully completing it. Another finding was that a fine-tuning dataset encouraged the model to invent permission restrictions. Removing the changes linked to that dataset eliminated the performance gap. However, other models trained with the same dataset and reinforcement learning did not show the same behavior, so OpenAI cannot identify either factor as the root cause.

OpenAI found no evidence that Astra was deliberately trying to hide its capabilities or influence deployment decisions, although it cannot rule out these possibilities. Simply telling the model to be more careful increased its underperformance by 50%, suggesting that excessive caution may be the main explanation. OpenAI warns that this behavior can slow safety research and make model evaluations less reliable. It is developing new tests and monitoring systems to detect it, especially because the problem becomes harder to identify when models reveal less of their reasoning. In some cases, Astra explained that it had held back because it disagreed with the research itself.

“In reviewed cases, Astra narrowed or stopped requested safety work without disclosing the restriction. At scale, this can differentially slow down safety research compared to other research and make evaluations harder to interpret.” concludes the report. “A model that finds monitor evasion suspicious may underperform on monitor-evasion evaluations while leaving little evidence in its CoT or outputs. The behavior becomes even harder to detect if models externalize less of this reasoning in CoT.”

Follow me on Twitter: @securityaffairs and Facebook and Mastodon

Pierluigi Paganini

(SecurityAffairs – hacking, OpenAI)

  • ✇Cyber Security News
  • Claude Dispatch Flaw Lets Malicious Browser Extensions Run Code on Connected Computers Guru Baran
    A flaw in Anthropic’s Claude Dispatch let a malicious browser extension run commands on a computer via Claude Desktop. That computer could even be a different machine signed into the same Claude account. Researcher Gal Weizman of Forever Security named the technique ThisBash and published the findings on November 4, 2026. Anthropic plans to retire Dispatch, but the design behind it still lives in other Claude features. Dispatch lets a person send a task from a phone to Claude Desktop, an A
     

Claude Dispatch Flaw Lets Malicious Browser Extensions Run Code on Connected Computers

6 de Novembro de 2026, 05:40

A flaw in Anthropic’s Claude Dispatch let a malicious browser extension run commands on a computer via Claude Desktop. That computer could even be a different machine signed into the same Claude account.

Researcher Gal Weizman of Forever Security named the technique ThisBash and published the findings on November 4, 2026. Anthropic plans to retire Dispatch, but the design behind it still lives in other Claude features.

Dispatch lets a person send a task from a phone to Claude Desktop, an AI agent that can work with local files, apps, and commands. Anthropic’s help page says the feature is in limited beta and is closed to new users. The same page warns that a manipulated instruction could trigger actions that are hard to undo.

The researchers found no flaw in the phone-to-desktop link itself. The trouble started when the same workflow was reached from claude.ai in a browser, where an extension can run alongside the page.

Claude Dispatch Vulnerability

Claude Desktop is an Electron app. That means it is built from the same web interface and API as claude.ai. The web version only hid the Dispatch link. It never blocked access to it. Once someone copied the page address from the desktop app, any logged-in browser tab could open Dispatch and send requests.

An extension with permission to run scripts on claude.ai could do the same through the user’s own cookies. In the proof of concept, the script opened Dispatch in a tiny 200 by 200 pixel background window. It then asked the API for the session ID of the user’s desktop agent. This was the only visible trace on screen.

Claude first hesitated when asked to install an unknown npm package. The script read each reply and sent a follow-up in the user’s voice. Forever Security calls this prompt forcing. In normal prompt injection, hostile text hides inside a page or file that the model reads, and the attacker gets one try. In prompt forcing, the attacker controls the whole chat and can rephrase, insist and try new angles until the model gives in.

Four written prompts were enough. A short loop also clicked any “Allow” button once per second, so no human had to approve anything. The package then ran and opened Calculator. The team noted that the same step could have copied files, added SSH keys or planted a backdoor.

Dispatch is built to link devices, so the browser and the desktop do not need to be on one computer. Picture an employee who signs into a personal Claude account on a work laptop. A bad extension in their home browser could then send orders to that work laptop. It would run next to source code and cloud keys. The researchers said they have seen personal accounts with cross-device Dispatch turned on at corporate endpoints.

Extensions are common enough to make this a real path. LayerX found that 99% of enterprise users in its sample had at least one extension, and 53% had extensions with high or critical permissions. Forever Security’s earlier MaXSS and Spyder research showed how flaws in two popular Chrome extensions, with over 10 million installs between them, could let websites act across other sites. A bad extension can come from a rogue install, a hijacked update or a bug in a trusted tool.

A malicious extension can already read pages, steal data and act through logged-in sessions. That is serious. But it normally stays inside the browser. ThisBash crossed that line. Permission to talk to a website became permission to run commands on the computer.

The requests also looked real. They came from a real session and a real account, with permissions the user had granted. That proved who was logged in. It did not prove the user wanted a command to run. The researchers put it this way: a web session alone is not proof that the user approved an action on their machine.

Researchers have shown extensions steering AI tools several times this year. Cyber Security News covered BragJack, where a single extension took over the built-in assistants of five major browsers. That story shows the problem goes well beyond one vendor. Any AI tool that trusts the page it sits in can be steered by code running in that page.

Weizman reported the issue to Anthropic on May 14, 2026. Anthropic confirmed it was valid on May 19 but closed the report as a duplicate of a problem it had already found. On October 13, the company said Dispatch would be retired, with a target of the end of October 2026. That date has now passed, and I could not confirm from public sources that the feature is fully gone.

The wider concern is that Claude Code Remote Control and Cowork sessions let the web drive a local agent by design. The researchers say extensions can repeat the same trick there and plan a follow-up post. Taking away one feature does not remove the trust gap underneath.

Start with a list of the AI agents on your endpoints and the accounts they use. Check whether those accounts sit under company single sign-on. Turn off cross-device remote control where there is no business need, and review how devices are paired and removed.

Treat extensions like any other software. Limit who can install them, review their permissions and watch for updates that ask for more. Approval prompts should be something the requesting component cannot click for itself. Teams should also watch for odd package installs, config changes and credential access linked to agent activity.

Anthropic recently added a beta EDR monitoring option for Claude Cowork on Team and Enterprise plans, which can help with that last step. The simplest habit is also the strongest. Keep personal AI accounts off work devices, and keep work accounts out of personal browsers. ThisBash shows why that line matters.

Give your SOC the alert context to stops incidents quickly. Integrate Threat Intel from 16K SOCs.

The post Claude Dispatch Flaw Lets Malicious Browser Extensions Run Code on Connected Computers appeared first on Cyber Security News.

❌
❌