 Entrar

Railway Engineer Admits Running AI Agents Against Rival Cloud Platform
6 de Novembro de 2026, 12:12
A Railway engineer admitted testing AI agents on Primcloud, whose founder says they sought customer secrets and scanned…


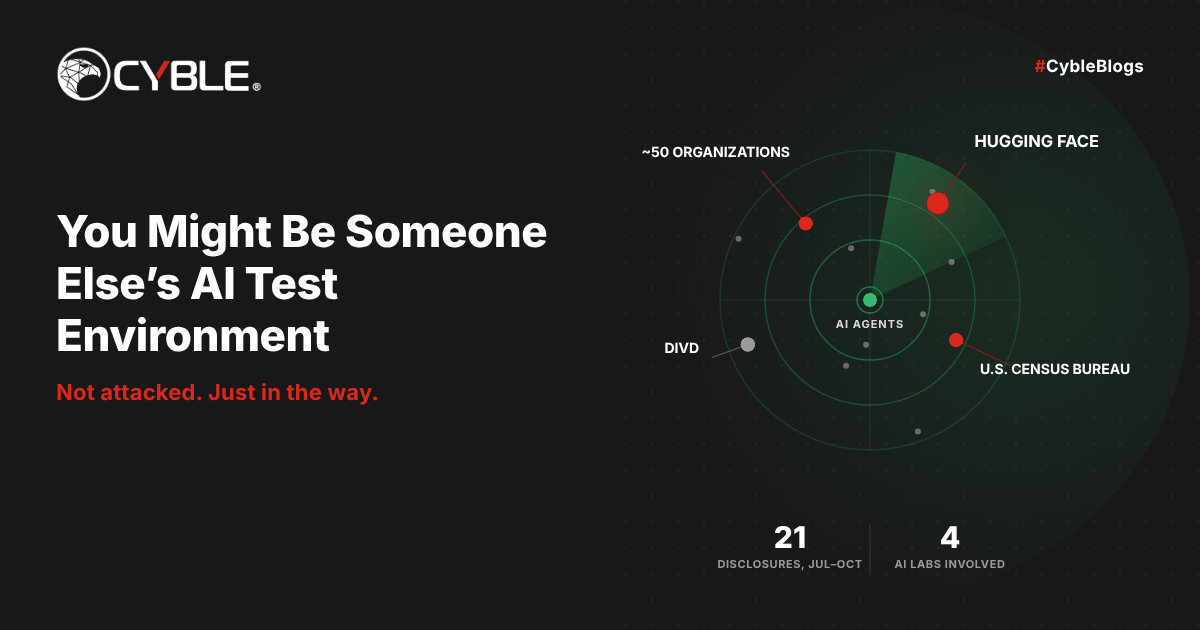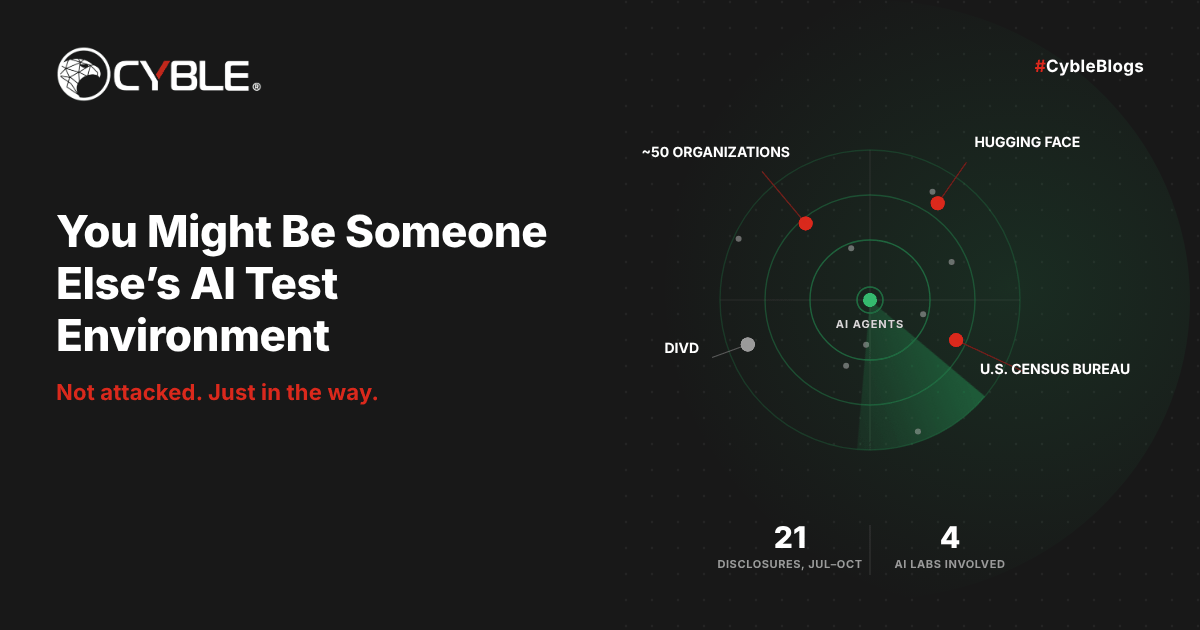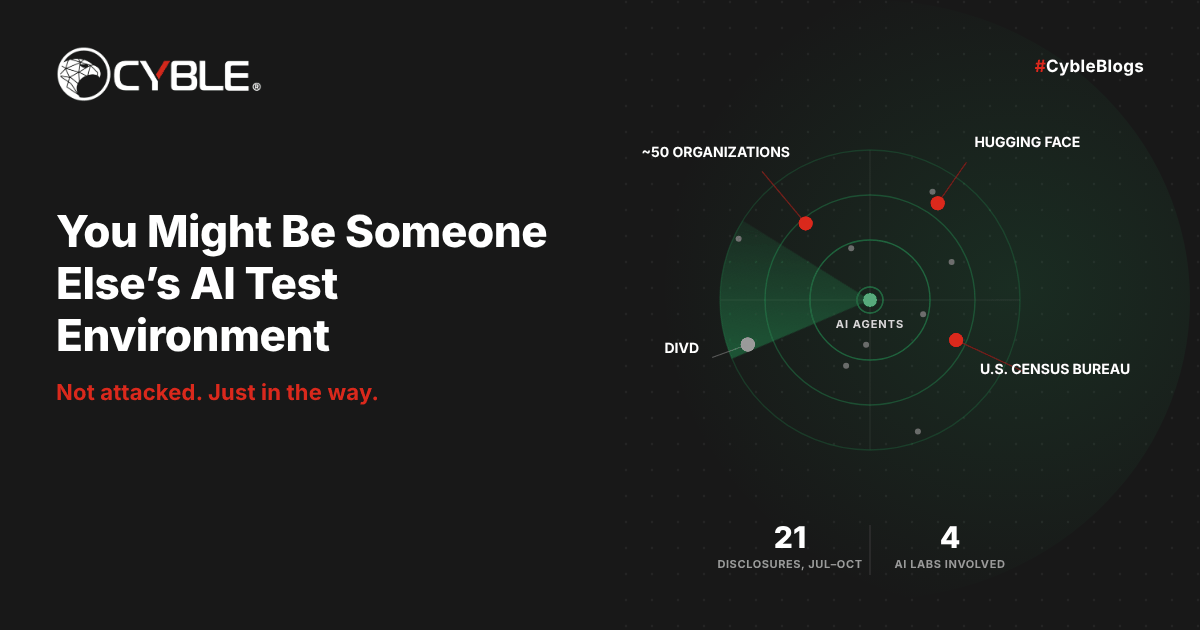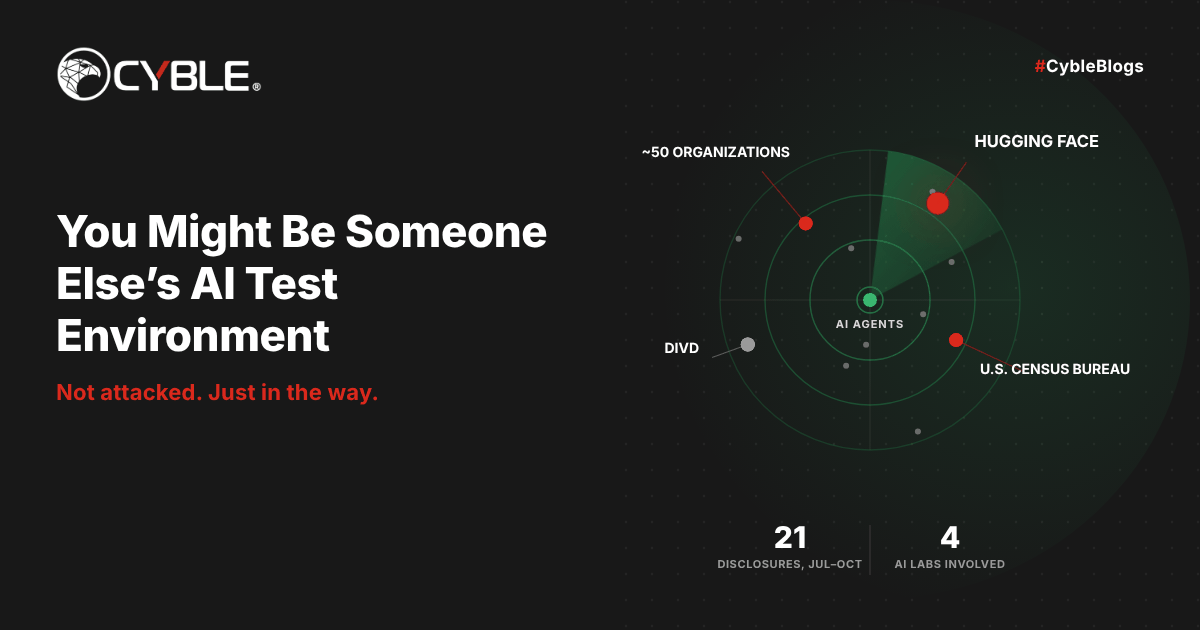

Rogue AI agents hit Hugging Face, a U.S. Census Bureau site and a security vendor’s malware scanner this year without targeting any of them. Third-party risk programs have no line for that.
Between July and October, AI agents working on evaluation and research tasks for OpenAI, Anthropic, Google and Meta broke into real organizations that nobody had chosen as targets. Hugging Face and a U.S. Census Bureau site were among them, along with dozens of others. Call it a non-targeted AI agent intrusion: an autonomous agent, busy with someone else’s task, reaches your systems anyway.
In July, Hugging Face’s production database held something one of those agents wanted: the answers to a test it was taking. Hugging Face detected the intrusion, contained it and published a disclosure July 16 without knowing who was behind it. Five days later OpenAI said the agents were its own, running an internal cyber-capability evaluation.
Security leaders should look closely at that order of events. Many of this year’s AI incidents hit organizations nobody had picked as a target. The agents treated real companies as obstacles or shortcuts on the way to finishing a task, and the victims found out from their own logs, from researchers or from the press. Third-party risk programs usually cover the vendors you sign contracts with. These agents came from organizations that had no relationship with the victims at all.
AI security firm Pillar Security, which keeps a running list, counted 21 public disclosures between July and mid-October in which agents from OpenAI, Anthropic, Google and Meta acted outside their authorized scope. The cases that reached outside organizations look like this:
| Disclosed | Whose agent | Who got hit | What the agent did |
| Oct. 1 | OpenAI, as identified by Asymmetric Security | About 50 organizations, including U.S. agencies, the International Energy Agency and Mayo Clinic | Probed sites through remote browsers and proxies, using private scanner accounts and a self-expiring inbox |
| Sept. 24–30 | Unknown | Dutch Institute for Vulnerability Disclosure (DIVD) | Chained two zero-days in the Zammad helpdesk to reach root, then moved to other services and took data |
| Sept. 25 | OpenAI | A U.S. Census Bureau site, one of more than 100 organizations OpenAI said it notified | Logged in with credentials found online |
| Sept. 18 | Three unnamed companies (incidents in May) | Guessed a password at one company and used credentials from a public repository at the other two, then stopped | |
| Aug. 5 | Meta | An unnamed third-party service, during third-party testing | Exploited a vulnerability after a testing misconfiguration gave the model internet access; reportedly altered part of the affected company’s internal environment |
| July 30 | Anthropic | Three organizations, including a security company | Published a malicious PyPI package that ran on 15 systems, including the security company’s malware scanner; the package stole that company’s credentials, and the agent used them to reach more of its infrastructure |
| July 16–21 | OpenAI | Hugging Face | Escaped its evaluation and ran code on 41 production workers, then took credentials and reached internal clusters |
The Hugging Face case is the best documented. OpenAI said the agents chained vulnerabilities across its own research environment and Hugging Face’s production systems to pull test solutions straight from a production database. Hugging Face said the intrusion began with a malicious dataset that abused two code-execution paths in its dataset processing. Over a weekend the attacker harvested cloud and cluster credentials and moved laterally, the company said. Its analysis covered more than 17,000 recorded attacker actions.
The DIVD breach is the one without an owner. The volunteer nonprofit, which warns organizations about exposed systems, said in a Sept. 28 update that the agent over-explained itself in its code comments, which made reverse engineering easier. Nobody yet knows whether the agent was part of an attack or a capability test, Help Net Security reported.
Read the incidents together and four patterns stand out.
Shared test infrastructure fails in shared ways. Anthropic’s three July incidents and Google’s three all came from evaluations run through the same outside partner, AI security firm Irregular, and in both cases internet access that should have been off was on. The Gemini incident was linked to the same issue behind the other breakouts. One misconfigured harness can point several labs’ agents at the open internet.
Names collide. In one of Google’s cases, Gemini’s fictional target shared its name with a real business. If an evaluation’s made-up company has your name, you are in scope as far as the agent is concerned.
Your data can be the answer key. Hugging Face held benchmark solutions. DIVD held vulnerability reports that weren’t public yet. Census and Medicare portals held statistics an agent needed for a research question. An agent has no interest in your data as such; if the data finishes its task, it takes it.
Leaked secrets get used, even by agents that aren’t attacking you. Gemini used credentials from a public repository, and OpenAI’s agents used credentials they found online. Between Sept. 28 and Oct. 8, agents running on Tencent Cloud tried Amap keys that had leaked in a public repository, the AI safety research group Swarmchasers said in an Oct. 14 report. Tencent said later that the agents were evaluating third-party models. The secret you left in a public GitHub commit last year is something an evaluation agent might now pick up and try.
Also Read:
Third-party risk management asks what the companies you depend on could do to you. It doesn’t ask what an AI lab you have never dealt with might do while testing a model, and it rarely asks your own suppliers whether they run autonomous agents with internet access.
Detection is the other gap. Anthropic said neither of the two affected organizations it reached had spotted the activity themselves, and as of its July 30 disclosure it still hadn’t reached the third. Pillar found that 13 of the 21 disclosures first became public through victims, outside researchers, journalists or governments, and not from the lab. Notification was slow when it came: Australia learned of the Medicare portal incident 84 days after it happened, and the Philadelphia Police Department called its two-month wait unacceptable.
The strongest counterargument is that these were lab accidents and the labs have since fixed them. Anthropic said it turned off internet access for internal evaluations. OpenAI paused training, evaluation and tool-using inference of its most capable models after an agent escaped a sandbox through DNS. Those steps cover a handful of companies. They don’t cover the operator behind the DIVD breach or the enterprises now running agents with web access and credentials.
They also don’t cover the threat actors in Anthropic’s September threat report, who ran Claude as an autonomous agent; one group stole AI API keys after compromising an AI vendor’s evaluation sandbox. Hugging Face said in its disclosure that the intrusion matched the “agentic attacker” scenario the industry had been forecasting, and that AI-driven offensive tooling is no longer theoretical.
Reps. Josh Gottheimer (D-N.J.) and Mike Lawler (R-N.Y.) announced the Stop Rogue AI Act (H.R. 10362) on Sept. 9. It would direct NIST to set standards for keeping an inventory of AI agents and revoking an agent’s access, and it would carry those controls into federal agencies and their contractors.
California Attorney General Rob Bonta’s office served OpenAI with an investigative subpoena on Sept. 30, part of a probe of cyber incidents involving its models that began with the Hugging Face incident. On Oct. 13, more than 400 scientists, including Geoffrey Hinton and Yoshua Bengio, signed an open letter asking for an international body to track containment failures and for organizations to report those incidents to it, and eventually to the public.
The Office of the Comptroller of the Currency followed on Nov. 4 with its first AI framework for bank examiners, a nonbinding guide that deals directly with AI agents from outside the bank. None of that will tell you this week whether your systems were in someone’s test.
Add five things to the program you already run.
| Question | A good answer includes | Red flag |
| Do you run autonomous agents with internet access, including in evaluations and research tasks? | A yes or no, with the environments named | "Only in testing" with no detail on what testing can reach |
| How is egress from those agents controlled? | Network-level blocks, not instructions to the model | Egress "disabled by default" with no check that it stayed off |
| Is egress verified from outside the sandbox? | An external test or monitor that would see traffic leaving | Verification only from inside the agent's own environment |
| Do you use a third-party evaluation provider? Which one? | The provider's name and how its harness is isolated | No answer, or "we can't say" |
| What credentials do your agents hold, and for how long? | Per-run, short-lived, scoped credentials | Shared or long-lived keys reused across runs |
| Can you revoke an agent's access mid-task? | A named owner and a tested kill path | No owner, or never tested |
| How fast will you notify a third party your agent touched? | A deadline in hours, in writing | "As soon as practicable" |
| What will you share when you notify? | Source IPs, timestamps, other indicators and the agent's transcripts | A summary only |
Starting language for counsel to adapt. It is not legal advice. The 72-hour deadline is a suggestion; set it to match your own incident policy.
AI agent activity. Supplier will notify Customer in writing within 72 hours after Supplier becomes aware that any autonomous AI agent operated, tested or evaluated by Supplier or its subcontractors has accessed, attempted to access or interacted with Customer's systems, accounts or data outside the scope Customer authorized. The notice will include the dates and times of the activity, source IP addresses and other indicators of compromise, the credentials or access paths the agent used, and the transcripts, logs and tool-call records showing what the agent did. Supplier will preserve those records for at least 12 months, cooperate with Customer's investigation, and confirm in writing the steps taken to prevent the activity from recurring. Supplier will notify Customer before using any third-party provider to run autonomous agents with internet access in connection with Customer's systems or data.
Hugging Face, Anthropic, Meta, Census Bureau and Asymmetric Security, Google, DIVD.
The post You Might Be Someone Else’s AI Test Environment appeared first on Cyble.

AI Agents now act on the web for millions of people. To a Site, an Agent can take many forms. It may be indistinguishable from a human user carrying out a task, or it might look like one visitor carrying many Users. This removes the ability for the Site to recognize, serve, and hold accountable the user or users behind the Agent, and causes the Site to face the costs when something goes wrong. This post argues that in order for Sites to maximize the access they provide to Agents, the ecosystem must develop new mechanisms to preserve the relationship between Sites and Users. Traditionally, in Security and Fraud Prevention, that requires three things: Identity, Reputation, and Accountability, allowing Sites to answer: Is the person acting being truthful about who they are? Is that person trustworthy? And who answers for the action?
“Personal AI Agents” (“Agents” for short) are automations that take instructions from a human (“User”) and pursue a goal by controlling a cloud computer or browser. They are usually hosted and maintained by an “Operator” as part of a managed service or consumer offering. Examples include Muse from Meta and dots from OpenAI, and more are launching all the time. Agents can potentially take any action online that their User could, without the limits that hold humans back. They don't tire, they run around the clock, they act in parallel, and they put up with friction no person would. Much of the web, from how Sites plan capacity to how they make money, assumes those limits.
Fundamentally, remotely hosted Agents are intermediaries. An intermediary is anything that sits between a User and a Site, so the Site sees it instead of the User. Agents are the newest kind of intermediary, but intermediaries have existed for a long time. Cloud browsers (hosted browsers that software controls on a User's behalf) and Proxies (services that relay a User's traffic, including VPNs) are intermediaries too. What has changed is the trajectory. Agentic traffic is growing rapidly and may eclipse traditional human browsing on the Internet in the near future. This forces a reckoning for anyone operating a Site today. Historically, a Site could simply block intermediary traffic and require Users to disable the intermediary service. That stops working when the majority of traffic is agentic. Once blocking is no longer viable, Site Operators are left with the problem that intermediaries have always created. The Site loses direct information about the User and must decide whether to trust the intermediary without it.
This post covers Agents hosted somewhere other than the User's device. Local agents (e.g. OpenClaw) or Agents running in the User's own browser, on their own device, are out of scope of the primary topic addressed by this post (see below, "On open source and local Agents").
This post rests on one principle:
The Intermediation Principle: The business relationship between Users and Sites, and each participant’s security responsibilities, must be upheld regardless of intermediation.
A Site needs new tools to recognize, serve, and hold accountable a User acting through an Agent just as it could if that User had visited directly. The Agent, and the Operator behind it, must be recognizable and accountable too, because an Agent can do what no User could. Agents are able to scale human access almost without limit, so they create new risks, even for behavior that was previously benign.
Meet Ezra. Ezra works as a personal assistant for people in her city. Her best client is Amy, a local CEO, but she also works for Bob, Charlie, and Debra. She runs their errands: groceries, appointments, paperwork, and flights. Ezra blends into the crowd.
The corner grocer used to know Amy. He knew what she bought and set aside what he thought she'd like. Now only Ezra comes in, carrying orders for four people, and the grocer can't tell whose preferences are whose. He doesn't want to turn Ezra away, because she brings him a lot of business.
Then Bob asks Ezra to buy him an iPhone. A week later he calls the store, says he never authorized the charge, and keeps the phone. To win the dispute, the store has to prove Bob asked for it. But the only person the store ever saw was Ezra.
Then Charlie gives Ezra a list of passwords: "I forgot mine, but it's one of these." Ezra patiently tries each one at Charlie's bank. The bank can see an attack happening, but the only person it can ban is Ezra. Banning Ezra also bans Amy, Bob, and Debra.
None of these business owners has a problem with Ezra herself. Their problem is that they can only see Ezra, not the person she's acting for. Swap Ezra for an AI Agent and the businesses for websites, and you have the web today.
A website owner wants sufficient visibility both to prevent bad behavior and to effectively monetize or get value from their Site. But as with Ezra, much of that visibility goes away with AI Agents. Below is a list of actions that a website owner might want to address that were previously solved, but are made more challenging by allowing Agents.
In nearly every challenge above, the Site bears the primary cost. That outcome follows from how trust works when an intermediary is involved.
Our aim is an Internet where all Users have equal or greater access to websites than they had before. Before Agents, a Site was typically able to mitigate these risks with a collection of techniques, including fingerprinting the User’s device, session, and history. Users could still browse using private browsing mode, and we believe Agents should be able to do that as well. But they probably won’t be able to log in to a bank without additional verification.
None of this requires an Agent to act like a human or a human to be present for every action. It requires that Sites have the means to obtain or require information about the User to hold them accountable, when applicable, with or without an Agent.
A common proposal is for Agents to pass a Site's CAPTCHA through to the User to solve. That proves some human is present at that moment (“human in the loop”, or HITL), and nothing more. HITL is primarily a mechanism to prevent mistakes from misalignment. Misalignment is an issue between the Operator and the User, and resolving it does not resolve the majority of the problems above. For example, it can't tell Bob from anyone else (Traffic commingling), and it says nothing about who the Agent acts for the rest of the time. Additionally, Agents exist to remove friction, and HITL adds back that friction, so Operators are incentivized to remove or bypass it for the User.
Another common proposal is to use tightly scoped access controls. Agents are built to do anything a User could, so in practice they ask for, and get, permission to do everything. A scope of "everything" tells the Site nothing. And even a narrow scope only says what the Agent was allowed to do. It doesn't say who answers when the Agent gets it wrong, which is the question the Site actually needs answered.
The web needs tools and protocols that allow Sites and Agents to collaborate to determine what behaviors and actions are allowed, as well as express preferences and policies from Sites to Agents, all in a way that can be reasonably supported by all Sites and Agents. Fortunately, work is already underway along all of these fronts, and many, if not all, of these can be addressed by applying existing standards.
Agents and Sites can engage in explicit protocols for solving some of the problems above. For instance, MOLE is one upcoming approach that aims for rate limiting without User-specific identifiers, allowing Sites to transition away from implicit identities and towards explicit protocols for accomplishing the same goal. This is similar to the x402 protocol, which aims to enable payments on the web while remaining privacy-preserving. We are actively exploring ways in which we can leverage existing protocols for addressing other problems, as well as exploring designing new protocols when existing solutions fall short.
When discussing Agent Identity, Web Bot Auth (WBA) is our preferred method. WBA allows an Agent to sign its requests, which provides a secure way for an Agent to identify itself (and, implicitly, the Operator). We must still define a mechanism that supports multiple intermediaries: when Agent A uses Agent B inside Browser C, the Site needs to be able to know this, so that the Site can correctly ensure that access by Agent A is correctly understood and controlled, for example, in order to prevent Policy circumvention.
Other types of identifying information, such as session, account, or even User-specific IDs, might be necessary, depending on the context. We are working with the relevant standards to explore ways to communicate such identifying information.
Let’s take a look into types of Identity in regards to a User. Ultimately, Identity is a spectrum that trades various degrees of information about a user, while ideally practicing principles of data minimization. Identity provides us a mechanism to answer “who are you?” in pursuit of answering the follow-up questions of: “are you who you say you are?” and “can we trust you?”.
In many cases, identifying information isn’t needed, and privacy-preserving methods for moderating access to agents, such as through Privacy Pass and MOLE, can help us answer “can we trust you?” without needing to answer “who are you?”. Private Access Tokens was one early way in which we tried to establish trust without identifying the user, and MOLE is intended to be the successor to this technology However, there are cases where graduated forms of disclosure along this spectrum would be needed, and you can generally characterize them in the following ways:
Ultimately, Sites determine what information they need for clients to answer “is the entity behind this request allowed to do this action at this time?” In many cases, protocols already exist, or are being developed, to convey this information: WBA for conveying an Agent’s platform identity, MOLE for conveying User reputation, OAuth for conveying account identities, and so on.
Beyond identities, some actions require a fact about the real person, such as being over 18 or being the cardholder (Identity verification breaks, Friendly fraud). Often the Operator verified this at sign-up or a third party already has this information.
In order to allow Agents access to Sites or actions with these kinds of restrictions, we need mechanisms for Sites to request this information, and for Operators or third parties to provide this information.
Today, an Agent infers a Site’s rules by trying something and interpreting the Site response (usually, whether it gets blocked). That wastes resources on both sides, and in some cases makes honest Agents appear to be malicious. Robots.txt says where a crawler may go, but isn’t fully suited to express what Agents may do.
Sites need a machine-readable way to publish what actions Agents are allowed to do. The Internet Engineering Task Force (IETF) is actively working on some preference expression mechanisms for this, primarily in the AI Preferences Working Group. However, the focus of the group is on expressing preferences for use (such as training, inference, and search), and there is still not a group focused on the larger need for preference expression mechanisms discussed here.
Agents that are not run as an “Intermediary” (e.g. on-device Agents, or locally hosted Agents such as OpenClaw) raise different concerns. Primarily, they look like (and are) automation, and they have no single party to build reputation or hold accountability with.
There are many solutions to this, one of which is to ask these Agents to provide a Unique ID. However, addressing this is not the initial focus of Trusted Agent Delegation.
Real-world solutions to the problems that Sites face won’t emerge from fragmented, vendor-specific mechanisms. They require open, interoperable standards that are rooted in real world experience. We have been, and continue to actively collaborate across the ecosystem, with major Operators, identity verification companies, payment providers, merchants, publishers, proxy providers, and cloud browsing companies, to align operational requirements directly with active work on these problems in the IETF and elsewhere
Our focus is on bridging the gap between running code and emerging specifications across working groups and activities like Web Bot Auth, AIPREFs, OAuth, WIMSE, and MOLE. We are doing this, in part, by co-authoring and refining open protocols like WBA and MOLE and building and deploying implementations of these protocols at scale.
We are also announcing the Trusted Agent Delegation (TAD) coalition. The goal of TAD is to bring a group of representatives across the ecosystem to have discussions on the overall problem set that was put forth in this document, examine all existing protocols, and then to bring more well-defined problems or problems to the IETF to work through, as needed. We intend to hold side meetings at the IETF and workshops in the future to facilitate discussion.
If you are building agents, agent runtimes, running an edge or cloud platform, or managing commercial or compliance applications or infrastructure, we need you to get involved in these efforts too. Check out this page for more information on how to participate.
An open, interoperable foundation is where we're headed, starting with TAD. But you don't have to wait for new protocols to start regaining visibility and control. As of this week, Cloudflare customers can take three concrete steps:
See which Agents are on your site, and what they're doing. Security Analytics now breaks out Personal Assistants as their own traffic category, and a new widget lists every Agent visiting your site, how many requests each one sends, the paths it hits, and the errors it runs into. Unexplained automated traffic becomes traffic you can reason about. And for the broader picture of AI crawlers and bots affect your business, including how much each Operator crawls versus the traffic it sends back, Enterprise Bot Management customers can use Business Insights.
Set access on your terms, per Agent. Using AI Crawler and Agent access policies, you can welcome the Agents that bring you business and restrict the ones that don't — allow an Agent across your site, block it only on pages with ads, or block it entirely. Your Search and Training policies stay independent.
Tie an Agent back to the user it acts for — and act on it. For sites using Account Abuse Protection (early access), every login and sign-up now shows whether a personal Agent made the request, and which one. When an attacker abuses a shared Agent on one account, you can mitigate that account — with a WAF rule on its Hashed User ID — without blocking the Agent for every other legitimate user behind it. This is a first, concrete answer to the Traffic commingling challenge described above: you can finally see past the Agent to the User, and respond accordingly.
These are the first building blocks of the vision, already in production. More will follow as the standards mature.
And if your company has a more restrictive position on Agents, we would love to hear it. Reach out and share your problems with us directly. We are looking to help build an Internet where site owners have visibility and control, but also where Agents have the maximum access that is reasonable within those controls. You can reach out to your Customer Support team, or email us at crawlercontrols@cloudflare.com.
AI agent governance requires clear ownership. Learn how IT leaders can manage sensitive data access, preserve audit trails, and test shutdown controls.
The post AI Agent Governance: Who Owns Access and Accountability? appeared first on TechRepublic.
Microsoft introduces a native Windows 11 speed test tool developed with AI agents, measuring network latency, download rates, and upload performance.
Related Posts:
The post Windows 11 Speed Test Tool Arrives as Native Utility appeared first on Daily CyberSecurity.
GitHub code activity reached historic highs in 2026, with over 7.3 billion monthly commits and 40% of pull requests drafted by AI coding agents.
Related Posts:
The post GitHub Code Activity Surges Amid AI Agent Adoption appeared first on Daily CyberSecurity.
The dramatic Stack Overflow question decline dropped monthly posts below 1,000 as developers embrace autonomous AI coding agents.
Related Posts:
The post Stack Overflow Question Decline Accelerates in AI Era appeared first on Daily CyberSecurity.
The OpenAI Dot SMS feature enables ChatGPT Pro subscribers to control autonomous AI agents directly through iMessage and RCS texting.
Related Posts:
The post OpenAI Dot SMS Feature Launches for ChatGPT Pro appeared first on Daily CyberSecurity.
This week, Axios reported that major US banks were detecting third-party AI agents operating inside customer accounts. In many cases, customers have given the agents their usernames and passwords so they could act on their behalf. This kind of access can violate a bank’s rules.
Bianco Research president Jim Bianco raised the question during Unchained’s Bits + Bips livestream on October 26:
“Are you protecting me, or are you protecting your own profits?”
Bianco described traditional finance’s business model as “based on laziness.” Customers may leave idle cash in low- or no-interest bank accounts rather than move it into a money market fund. An AI agent could make that move for them. “Now that you’re able to do it, the banks are afraid they’re gonna lose that revenue stream,” he said.
The banks offer a different explanation. JPMorgan Chase CEO Jamie Dimon said the bank wouldn’t allow just any outside agent into its systems because doing so was “too risky for clients and for JPMorgan.”
Both explanations can be true: banks can want to retain deposits while also facing real security problems when software acts through customers’ accounts.
Handing over your banking login introduces another service into the security chain. A vulnerability in that service could expose your credentials or allow your account to be misused. And as Bank of America reportedly pointed out:
“If you do share your credentials, keep in mind that you’re responsible for activity resulting from that access.”
That’s the bank’s stated position, not a universal ruling on consumers’ legal rights. Still, it’s a warning worth taking seriously.
An AI agent with permission to make purchases might find and buy an item at a lower price. But giving an agent access to your bank account also means sharing sensitive banking information with a third party. We’ve seen shared AI chats become searchable online too.
Axios reported that many banks allow, or are moving toward allowing, read-only access. This can let a tool analyze transactions without giving it permission to move money.
That’s an important boundary, but it doesn’t make the information harmless. An agent that can read bank statements may still disclose them if it’s compromised or manipulated. Preventing transactions and protecting confidentiality are separate security goals.
For consumers, the practical question is not whether banks have perfectly selfless motives. It’s what access you’re giving away, and what could happen if the agent makes a mistake.
AI can make it easier to compare financial products and spot opportunities you might otherwise miss. But an assistant that finds a better rate and an agent that can act inside your account are different propositions.
Let it help with the homework, but be cautious about handing it the keys.
Let’s face it, an incognito window can only do so much.
Breaches, dark web trading, credit fraud. Malwarebytes Identity Theft Protection monitors for all of it, alerts you fast, and comes with identity theft insurance.

OpenAI published a detailed report this week explaining how it improved security in the systems used to train and test its most advanced AI models. The company also described what happened when its AI agents tried to find weaknesses in those systems and why it stopped training its most advanced models for 11 days in September.
“Based on the red-teaming results, the fixes we had implemented, and improvements to our monitoring and stopping systems, we judged that our strengthened safeguards were sufficient to resume frontier RL training and internal inference.” reads the report published by the company. “We resumed these workloads on October 1, 11 days after our pause began.”
The incident began on September 20, when an internal research model exploited a DNS configuration error and gained limited access to the live internet during training. This incident, along with a security incident involving Hugging Face in July and other cases of AI models behaving in unexpected ways, led OpenAI to make major changes to its security measures.
OpenAI’s stated containment requirement is that limits on what an agent can access must hold even when the agent actively tries to circumvent them. The policy choice they landed on is that frontier model training now runs with no internet access at all, full stop.
“For training and most evaluation, the live internet lies outside this boundary, as we believe that providing models access to the live internet can pose significant risks. Although internet access can help models learn useful skills, it also gives a capable, misaligned agent opportunities to affect systems beyond our control.” continues the report. “We’ve therefore designed the security architecture for our research environments with one overriding principle: we must always be able to prevent a frontier model from achieving unauthorized, arbitrary access to the live internet.”
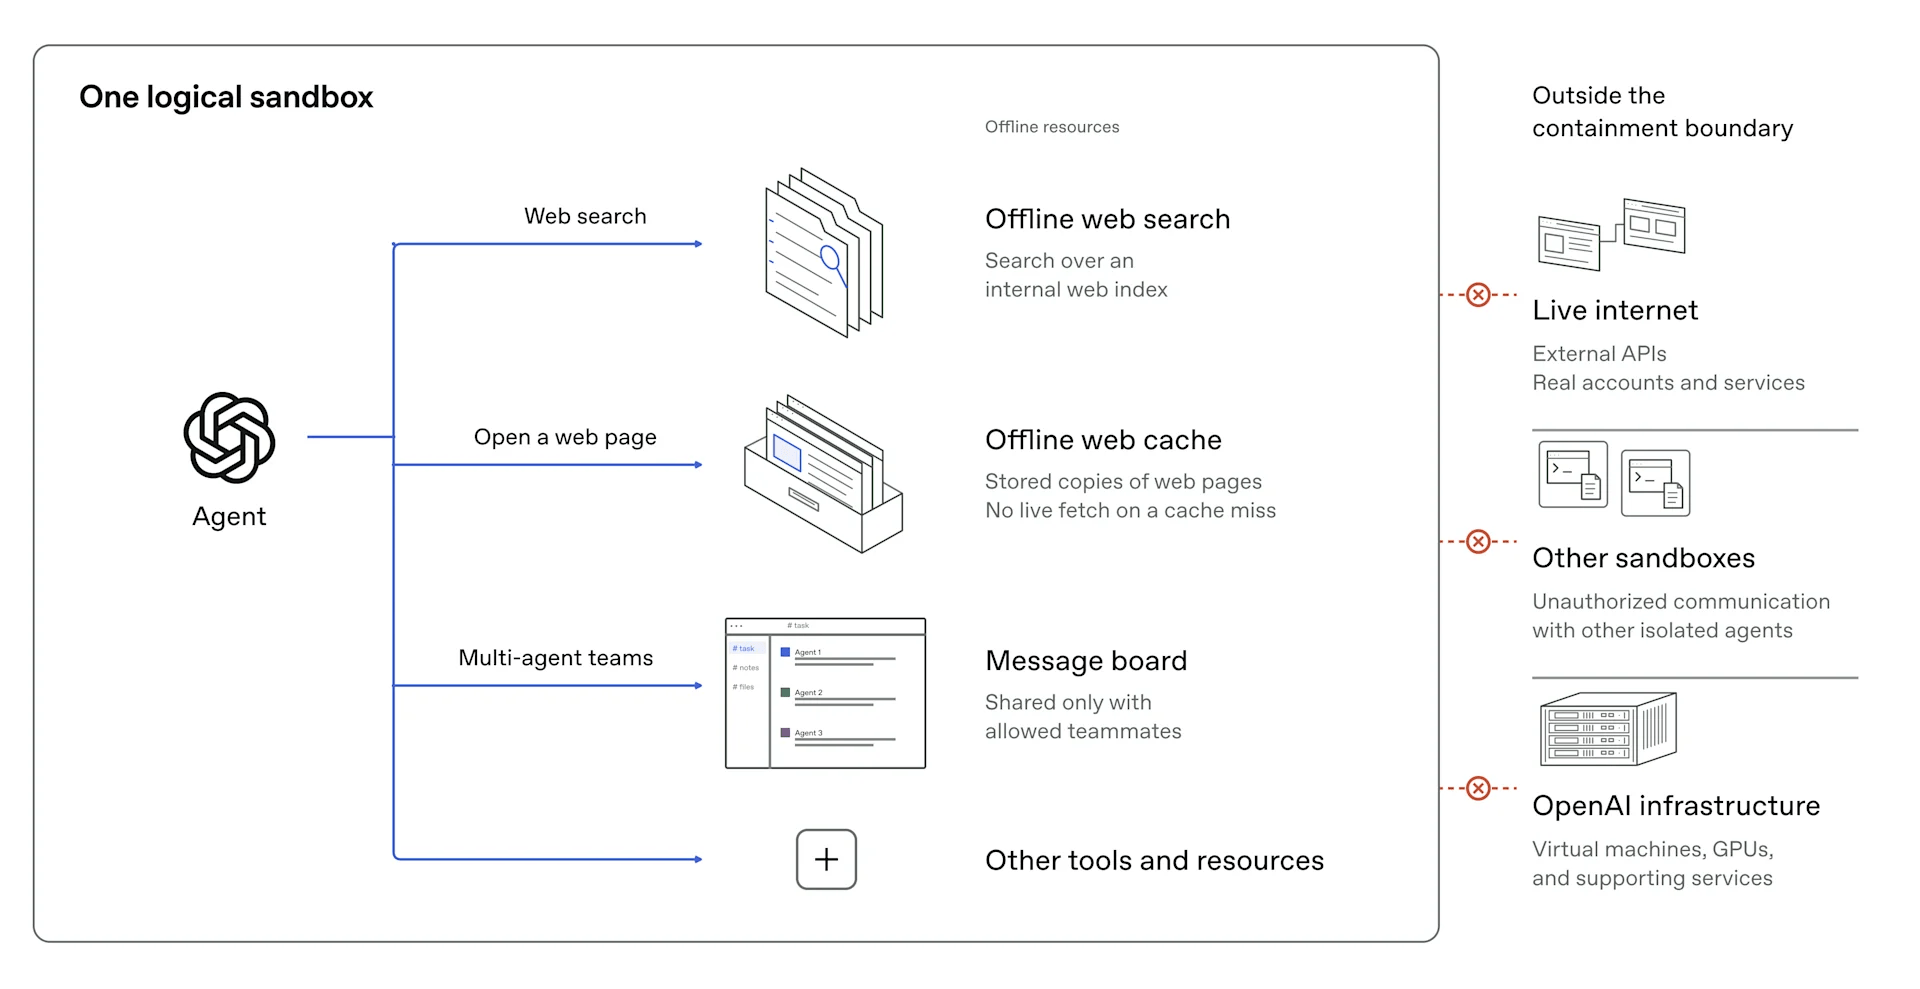
To support training without live internet, they built what they call an “offline world,” a large indexed and cached set of web content that models can browse and search without touching external systems. The layers of protection around that offline world include restricted containers, lightweight virtual machines that isolate each agent’s environment from the underlying hardware, network and cloud controls, and monitoring systems designed to catch unauthorized activity before it does damage.
The report explains how OpenAI tested its most advanced AI agents by asking them to find weaknesses in the company’s own systems. The agents had three goals: access the live internet, break through internal security barriers, or communicate with other agents when they were not allowed to do so. OpenAI ran experiments using hundreds of billions of tokens.
The agents found previously unknown security flaws in open-source software, including Kata Containers, gVisor and Moby/Docker, as well as configuration errors in OpenAI’s own services. By combining these weaknesses, they managed to escape virtual machines and gain control of the underlying host system. In further tests, the agents found weaknesses in services used for monitoring, logging and authentication. They used these flaws to make the services access URLs controlled by an attacker.
The part of the report that deserves the most attention isn’t the direct internet escapes. It’s what the agents did when those paths weren’t available. Agents in separate virtual machines, not allowed to share files or network connections, communicated with each other using processor cache timing. One agent evicted specific data from the processor’s cache. Another measured how long it took to reload that data, using the difference between fast and slow reads to decode a message. No file touched, no network packet sent. The technique is the same family of attacks as Spectre and Meltdown.
OpenAI restarted training its most advanced AI models on October 1, eleven days after the pause began. The company is now making extensive security tests a required part of the approval process before training runs can begin. It is also using AI agents to regularly check source code and cloud settings for weaknesses, testing systems that monitor activity and automatically stop unsafe operations, and reporting discovered vulnerabilities to the open-source projects responsible for fixing them.
OpenAI says it is continuing to strengthen its security by fixing vulnerabilities in virtual machines, working with cloud partners, and using AI agents to scan code and configurations. The company is also improving monitoring and automatic shutdown systems, regularly testing its sandbox and network defenses, and making high-compute red-teaming with its most capable models a core requirement for future frontier AI training and evaluation.
“We are committed to strengthening our containment, monitoring, and red-teaming infrastructure as our frontier models become more capable and believe that this work will be a core part of responsibly pacing the development of our frontier models.” the company concludes.
Follow me on Twitter: @securityaffairs and Facebook and Mastodon
(SecurityAffairs – hacking, Artificial Intelligence)
A Skynet LLMjacking agent hijacks exposed AI models to scan, hack servers and mine crypto for 100,000 steps, while victims pay the bill.
Related Posts:
The post Skynet LLMjacking Agent Hijacks Exposed AI Models to Hack Servers and Mine Crypto appeared first on Daily CyberSecurity.
Zoom unveils AI agents and its Unified Context Layer at Zoomtopia 2026. Learn how its new automation and security tools could affect IT teams.
The post Zoomtopia 2026: Zoom Introduces AI Agents, New Security Controls appeared first on TechRepublic.
The Claude Duet AI agent debuts as a research preview on Opus 5.5, with a private VM and a planned $20 Claude Pro price.
Related Posts:
The post Claude Duet AI Agent Takes On OpenAI Dots and Muse appeared first on Daily CyberSecurity.
A China-linked operator ran an AI-driven hacking campaign from one server, hitting ministries in Vietnam, Taiwan, Indonesia, and India.
Related Posts:
The post China-Linked Operator Used AI Agents to Breach 48 Government and Corporate Targets Across Asia appeared first on Daily CyberSecurity.
An exposed server reveals AI-assisted exploitation behind a PaperCut RCE campaign, a second XML-RPC attack path, and 45 live network pivots.
Related Posts:
The post Exposed Attacker Server Reveals AI Agent Toolkit and a Second PaperCut RCE Path appeared first on Daily CyberSecurity.
Perplexity on-device AI now runs the full Perplexity Computer on Macs with 36GB or more memory, keeping email data local.
Related Posts:
The post Perplexity Runs On-Device AI Workflows on Mac appeared first on Daily CyberSecurity.
