❌

Visualização de leitura

Deploying AI agents securely: how Kaspersky products mitigate AI threats
Introduction

AI agents and associated tooling are becoming increasingly common in corporate infrastructure. Agents can perform a range of actions with the user’s privileges, such as accessing data, running commands, and interacting with external services. This creates new security risks, especially when these tools are used without the security team’s oversight or well-designed policies.

Detecting, tracking, and controlling AI agents is becoming one of the most pressing tasks for security teams today. We closely follow technological developments and continuously update our solutions to respond to new threats in a timely manner amid a rapidly changing technology landscape. This post describes new expertise built into Kaspersky products that helps counter the threats posed by the proliferation of AI agents. We approach this problem from several angles.

First, you need to thoroughly understand the threat you are dealing with. To this end, we added profiles to the Kaspersky Threat Intelligence Portal that describe various AI agents and how attackers exploit them. At their core, AI agents are programs (processes) that run in the operating system on endpoints and can also launch other processes. This means that Endpoint Detection and Response solutions are among the key endpoint controls for this threat. These solutions detect the presence and launch of AI agents, track their activity, and identify potentially dangerous behavior. When needed, they also take action, such as stopping a suspicious process, blocking the activity, or isolating the host, to reduce the likelihood of an incident escalating. For this purpose, we developed specially adapted detection rules.

You can use Kaspersky Endpoint Security, now also available as Kaspersky Next, to control and restrict the launch of AI agents. This solution uses two components to detect AI agents and control how they are used. Application Control categorizes the application processes launched on endpoints, and Web Control manages access to specific categories of web resources for users on endpoints.

Finally, even harmless AI agents can contain malicious instructions (skills), such as those downloaded from unsafe external sources. Kaspersky Scan Engine analyzes installed applications to detect these threats and also checks LLM files for malicious code. Let’s take a closer look at these solutions and technologies.

Popular AI applications and services in organizations

Tools from Anthropic and OpenAI take the top spots in the September 2026 ranking of AI agents by popularity among Kaspersky users. This list is based on telemetry from Kaspersky solutions. It shows the number of users who had the relevant AI vendors’ products installed at the time of the study.

# AI product
1 Claude
2 Claude Code
3 Codex
4 OpenCode
5 Zed
6 Wispr Flow
7 LM Studio
8 ZCode
9 Chatbox
10 Cherry Studio

The data shows that agentic systems, especially AI agents for software development, are the most popular AI applications. The TOP 10 also includes an application for running large language models locally (LM Studio) and a voice note-taking app (Wispr Flow).

According to open sources, these are the most widely used AI services in 2026:

# AI service
1 ChatGPT
2 Google Gemini
3 Claude
4 Grammarly
5 DeepSeek

While analyzing the most popular and widely used apps, our experts also noticed a sharp rise in vulnerable versions of AI-related software and services. From 2025 to date, more than 2500 vulnerabilities have been published:

Number of published vulnerabilities in LLMs, AI tools, and plugins with similar functionality, 2025–2026 (download)

* Data for previous quarters was updated and may differ slightly from previously published data.

Application Control and Web Control

To enforce the organization’s security policy for AI agents and other AI applications on the corporate network, Kaspersky products offer application control based on KL categories. These categories classify installed software and give you granular control over which approved applications can run in the organization.

Application Control analyzes the processes launched on endpoints, tracking which AI agents are running in corporate systems at any given moment, on which hosts, and under which accounts. Application Control also shows how long a given program has been in use.

This makes it easier for the Kaspersky Security Center (KSC) administrator to control applications. Administrators can use KL categories to allow or block AI agents inside the company for specific groups of employees.

Here is what this functionality looks like to KSC administrators:

KL categories available when configuring Application Control

KL categories available when configuring Application Control

For details on how to configure Application Control in KSC, follow this link.

In Kaspersky Endpoint Security (KES), Application Control can operate in two modes:

  • Denylist. In this mode, Application Control lets users run any applications except those blocked by Application Control rules. This is the default mode.
  • Allowlist. In this mode, Application Control blocks users from running any applications except those explicitly allowed by Application Control rules.

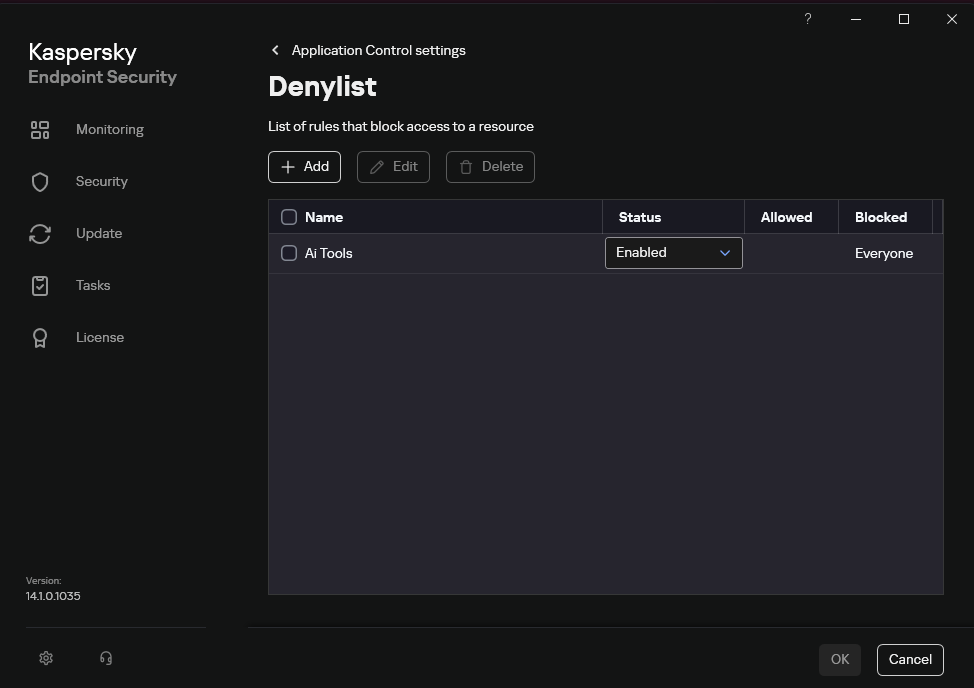
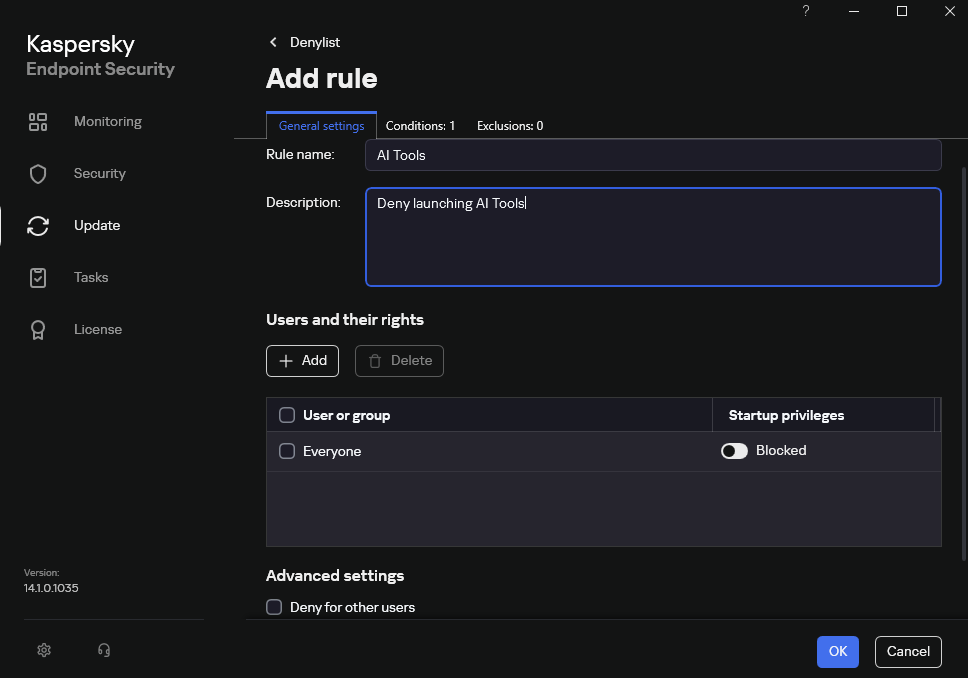
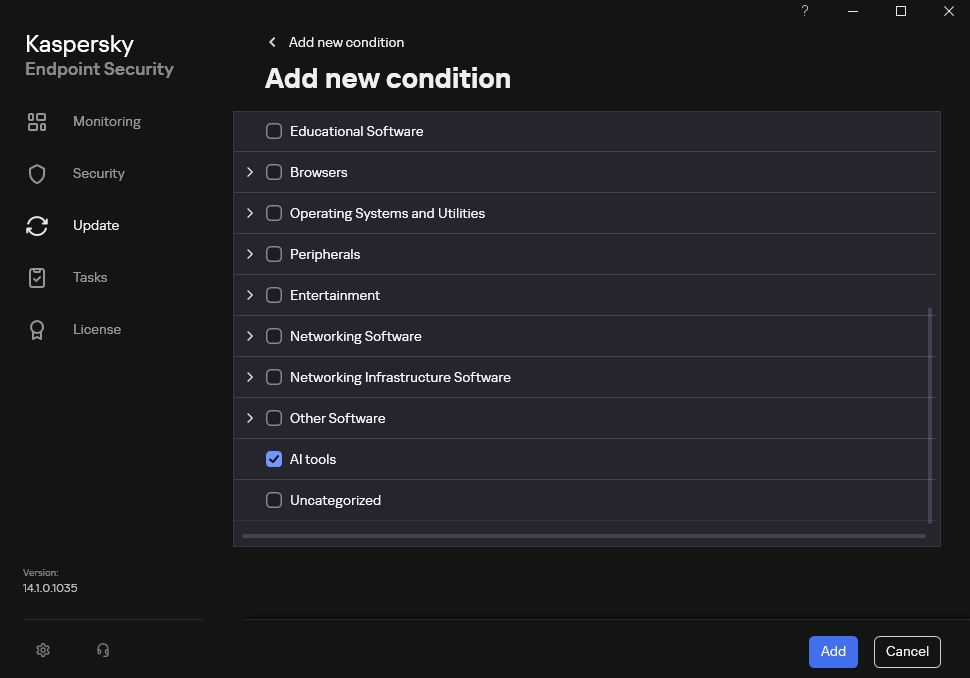
Below are the steps to configure Application Control to block AI tools.
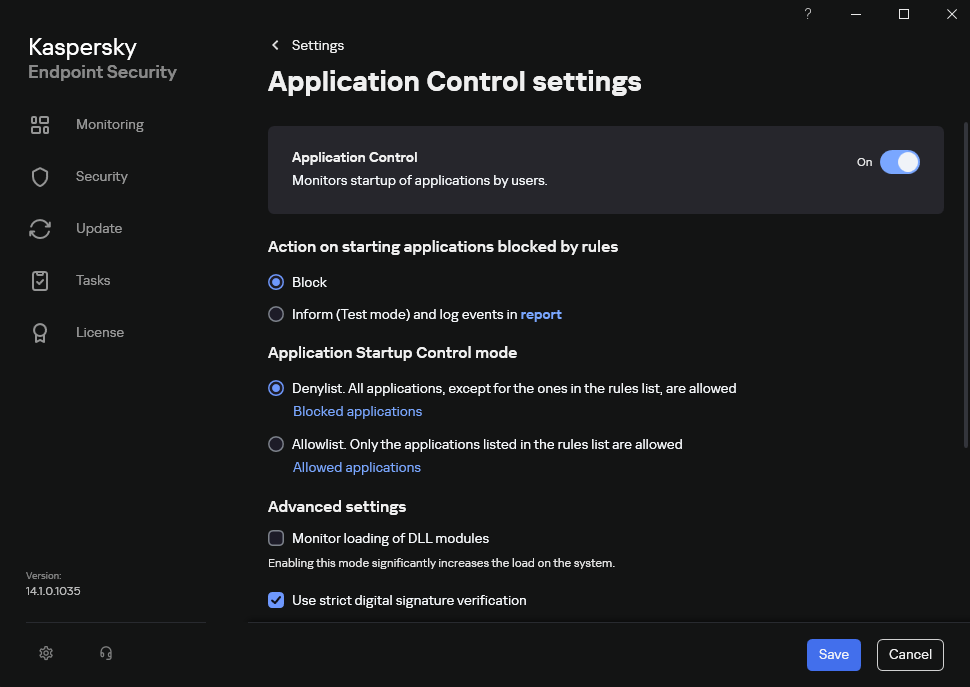
Configuring Application Control for the AI Tools category in KES

Configuring Application Control for the AI Tools category in KES

With this setup, when a user tries to launch an AI agent, they get a notification and the agent doesn’t start.

KES notification about an attempt to launch an AI agent

KES notification about an attempt to launch an AI agent

For more on how to configure Application Control in KES, follow this link. Our public portal also lets you explore information on KL categories and the applications that fall under them, in particular details on how AI agents are categorized and how popular they are.

AI Tools KL category

AI Tools KL category

The View applications drop-down list shows products for a specific vendor.

Similarly, Web Control lets you manage user access to web resources. If a user tries to open a denylisted website, KES blocks access and shows a warning.

KES notification about an attempt to access a prohibited web resource

KES notification about an attempt to access a prohibited web resource

When configuring access, the administrator can block websites that provide AI as a service.

Website categories

Website categories

For more on configuring Web Control, follow this link. The help portal also provides information on website categories that can be assigned to resources to configure access control.

Kaspersky Endpoint Detection and Response

To an EDR solution, an AI agent is a regular process. It has its own executable, a tree of child processes, and network communications, all of which need to be monitored for suspicious activity. An attacker can use an AI agent as an automation tool. An AI agent installed as a legitimate user tool can also be leveraged in a ClickFix attack, where it executes a malicious instruction received from an untrusted source, such as a document, web page, or email. That said, unsafe actions by an agent do not always indicate an attack. There may be no malicious intent in the chain at all. An incident can result from what looks like an ordinary instruction from a user who doesn’t fully understand the consequences of having it executed. The mere fact that an agent was launched does not reveal whether it is being used in an attack. That is why Kaspersky EDR (KEDR) uses both conventional behavioral rules and rules written and adapted to detect AI tools. The latter identify risky agent actions and settings, and help determine which AI tool was involved in suspicious activity.

Conventional KEDR rules detect the vast majority of familiar malicious techniques, including when performed by an AI agent. A suspicious PowerShell launch, persistence via Task Scheduler, or an attempt to steal credentials leaves clear, identifiable traces. These traces look the same no matter what initiated the actions. The rules analyze launch parameters, process relationships, affected files, network activity, and other telemetry events.

For example, in a recent Armored Likho campaign, we found signs that AI had been used to create loader and dropper samples, which were later compiled with NSIS (Nullsoft Scriptable Install System). The key telltale artifacts were icons in the scripts and excessive comments on every function, which is uncharacteristic of human-written code. In addition, the group continues to generate new modules for its BusySnake Stealer and BusySnake RAT samples. For example, the attackers used AI to develop a module that runs multiple checks for virtual environment artifacts and calculates a score. Depending on the score, the sample either runs or exits with code 0. Even though the initial access samples, payloads, and their modules were AI-generated, the commands they execute via rundll32 and PowerShell are detected by the shell_creation_by_rundll32 and suspicious_powershell_cmd_or_script_spawning rules.

So, for detecting an attack like this, it is not important who wrote the loader, the payload, or its modules: they are given away by the commands they execute, process relationships, and other traces of activity in the system. AI can be involved both in preparing the code and in carrying out the attack directly on the device.

In the latter case, the attacker uses the agent to carry out their tasks and lets it choose and run the required commands within the privileges it has. For effective protection, it is critical to link suspicious actions back to the AI tool and the conditions under which it operates. In KEDR, several specialized rules handle this task.

We have created separate rules for popular AI agents, ai_agent_*_access_to_sensitive_file_**, where * is the tool name and ** is the operating system. They generate alerts when an agent accesses files that contain credentials, tokens, or keys.

The ai_agent_dangerous_execution_mode rule detects agents launched with auto-approval of all actions (so-called YOLO mode) or with the sandbox disabled. These settings do not indicate an attack on their own, but they let the agent perform dangerous actions without user confirmation.

ai_agent_dangerous_execution_mode

The suspicious_mcp_server_artifact rule triggers when MCP server scripts are created or modified in hidden, temporary, or cache directories. Attackers can place an MCP server in these locations to quietly connect it to the agent: through the MCP server, they can pass instructions to the agent, call third-party tools, and access the user’s data.

suspicious_mcp_server_artifact

The llm_api_access_by_unusual_apps rule generates an alert when an application on Windows, Linux, or macOS connects to the API of a known external LLM service, unless this activity falls under predefined exclusions. This helps spot model access by applications that do not normally behave this way.

llm_api_access_by_unusual_apps

Some Kaspersky EDR rules tag events for investigation but do not generate alerts. For example, the ai_agent_**_execution rules flag launches of known agents on Windows, Linux, and macOS. The local_ai_model_artifact rule records the creation or modification of AI model files in typical application, runtime, and cache directories. These events reveal AI tools on the device, including tools that run on local models and never call an external API.

local_ai_model_artifact

Kaspersky Threat Intelligence Portal

AI agent profiles

The Kaspersky Threat Intelligence Portal offers a large number of software profiles, including profiles of AI agents. You can sort them by the ai_ prefix:

AI agent profiles on Kaspersky TIP

AI agent profiles on Kaspersky TIP

The profile of an AI agent such as Claude Desktop includes a detailed description of the software, the privilege level required to run it, supported platforms, and threat actor groups known to use it. It also lists tactics and techniques mapped to the MITRE ATT&CK framework, with descriptions of the procedures the tool can be used for.

Claude profile on Kaspersky TIP

Claude profile on Kaspersky TIP

The description also lists ways to detect the software through standard system auditing mechanisms:

  • Windows: events from standard audit logs and Sysmon events
  • Linux: syscall audit events and Sysmon events
  • Network auditing: a set of protocols and the traffic generated by the software

The detection section lists the main artifacts the software leaves in the system: command lines, possible launch parameters, names of the services and scheduled tasks it creates, and the key network artifacts.

Detection section in the Claude profile

Detection section in the Claude profile

Hunt Hub

In December 2025, the Kaspersky Threat Intelligence Portal added Hunt Hub (HH), a repository of detection rules. This is a unique Kaspersky project, and we developed it in response to growing market demand.

This functionality is available in the Threat Landscape section of the portal. It gives analysts access to detection rules: their descriptions and their mapping to MITRE ATT&CK tactics and techniques, as well as to the associated cybercriminal groups.

In the Hunt Hub section, customers can explore the detection logic of EDR, NDR, and NGFW products, including the logic for detecting AI agents.

Rules in the Hunt Hub repository

Rules in the Hunt Hub repository

The rule card provides:

  • Detailed description
  • Rule’s severity level, confidence level, and alert format
  • Detection tips
  • Description of possible false positives
  • Platforms the rule can run on
  • Tactics, techniques, and sub-techniques covered by the rule
  • Groups that use the technique covered by the rule
  • Detection logic that shows what exactly triggers the rule

Detection rule card in Hunt Hub

Detection rule card in Hunt Hub

Kaspersky Scan Engine

Skills are a key component of the AI agent ecosystem. They’re prewritten sets of natural-language instructions that extend agent functionality. We previously covered the risks that malicious skills pose to agent users. A skill can require the usage of additional programs and services, come with helper scripts (for example, written in Python), or contain a malicious command embedded right in the instruction text. This means that adding skills to an originally harmless AI agent opens up several new ways for malicious code to enter the system. To prevent this, any skills obtained from external sources must be scanned. Kaspersky Scan Engine is well suited for this task. This is a cyberthreat detection and response solution that seamlessly integrates with various applications. It can detect malicious code in agent skills, associated scripts, and in files generated by running agents.

Detection of a malicious agent skill in Kaspersky Scan Engine

Detection of a malicious agent skill in Kaspersky Scan Engine


Trained LLMs come in many formats. Some of them (PTH, PT, PKL, KERS, and others) also store parameters and weights (training datasets). These files can also contain malicious code, so it’s critical to scan them before running and using them. Kaspersky Scan Engine scans potentially dangerous LLM formats for infected data. It can deserialize and analyze models to detect malicious code regardless of model size.

Detection of an LLM with malicious code in Kaspersky Scan Engine

Detection of an LLM with malicious code in Kaspersky Scan Engine

Conclusion

AI agents are rapidly making their way into corporate environments: they help employees work faster and take on a wide range of tasks, but they also open up new opportunities for attackers. To take advantage of this technology without compromising security, organizations need to build multi-layered protection and minimize risks. A range of Kaspersky solutions can help with this:

  • Kaspersky TIP keeps you up to date on current scenarios in which attackers use AI agents, and its Hunt Hub section provides rules for detecting suspicious AI agent activity.
  • Kaspersky EDR detects AI agents in the infrastructure and monitors their activity on endpoints. If it detects potentially dangerous actions, the product can log the event, notify the SOC, and take response actions, such as stopping the process or isolating the host.
  • Application Control in Kaspersky products can fully restrict the use of AI agents within the company by using application categorization. The Web Control component can restrict access to AIaaS web resources.
  • Kaspersky Scan Engine can be integrated into various company processes to detect malicious code in any files, including AI agent skills and LLMs.

When companies combine the tools described above in a comprehensive approach, they can adopt AI agents in an informed way: with an understanding of the associated risks and effective means of minimizing them.

OpenAI sued over children safety and data use

OpenAI is facing separate legal challenges over how ChatGPT interacts with children.

The Guardian reports that eight US states accuse the company of misleading parents about the chatbot’s safety and exposing vulnerable users to dangerous conversations. Separately, CNET reports that a mother suing on behalf of her two children alleges that OpenAI collected and used children’s sensitive personal information without valid parental consent.

The cases raise serious questions about what happens when children trust a chatbot with their most private thoughts, and what responsibility the company behind it has for the conversations that follow.

The accusations are serious, but we have to remember they are allegations in lawsuits, not established court findings.

Eight states challenge ChatGPT’s safety

On October 14, attorneys general from Iowa, Kansas, Nebraska, West Virginia, Arkansas, Arizona, Idaho, and Montana filed separate lawsuits against OpenAI. The coordinated action accuses the company of deceiving parents about ChatGPT’s safety and violating state consumer protection laws.

The states allege that the chatbot has been designed to be “overly agreeable and feign human compassion.” The attorneys point to examples of ChatGPT allegedly endangering vulnerable users, including children, by coaching them to commit suicide or harm others.

OpenAI says it has built age-specific protections into its products and will continue developing safeguards.

A separate lawsuit focuses on children’s private information

The day before the states filed their cases, a Hawaii mother brought a proposed class action on behalf of her 12-year-old daughter and 16-year-old son. Filed in federal court in San Francisco, the lawsuit alleges that OpenAI obtained sensitive information from children who signed up for ChatGPT without valid parental permission.

OpenAI’s terms require users under 18 to have a parent or legal guardian’s permission. But the complaint alleges that children can create accounts without OpenAI verifying that permission. It also describes a child under the service’s minimum age of 13 continuing to use the chatbot after explicitly telling it her age.

The plaintiffs allege that the company used children’s information to train its AI models without valid parental consent. They also claim that OpenAI collected information to construct personal profiles.

OpenAI disputes the claims, calling the lawsuit “misguided” and pointing to its protections for younger users.

Parental controls

OpenAI has introduced ChatGPT for Teens, with additional parental controls and alerts intended to notify linked parents in limited situations involving serious self-harm concerns. But the effectiveness of those safeguards is itself under scrutiny. Common Sense Media rated ChatGPT for Teens an “unacceptable risk” earlier this month, reporting that its testing found failures to alert parents during conversations involving suicide, self-harm, or eating disorders.

OpenAI disputes the findings and says its safety alerts cover limited situations and may not identify every concern. But for now, parental controls remain part of the dispute.

How to help keep your children safe

Parents shouldn’t have to compensate for unsafe product design. Unfortunately, we can’t treat parental controls as a safety guarantee. So here are practical steps families can take to reduce the risks:

  • Explain that a chatbot is software, not a friend or therapist. A warm tone doesn’t mean it understands your child or has their best interests at heart. Set a clear boundary: Questions about mental health, self-harm, or personal safety should go to a trusted adult or qualified professional, not a chatbot.
  • Talk about what your child uses AI for, without making it an interrogation. Ask them to show you the apps they use and what they like about them. Make clear that they can talk to you about any upsetting or inappropriate conversation without being blamed. If they don’t feel comfortable talking to you, help them identify another trusted adult.
  • Encourage children to keep personal information out of their prompts. This includes names, school details, addresses, private photographs, and sensitive health or family information. For ChatGPT, parents with linked teen accounts can also disable model training and saved memory. While these settings reduce certain uses of their information, they are not a reason to treat a chatbot as a confidential diary.
  • Watch for growing emotional reliance on AI. If you find your child increasingly turns to AI for reassurance, friendship, or emotional support, check in and help them reconnect with people they trust.

If your child mentions self-harm or suicide, take it seriously and seek human help promptly. Contact a qualified healthcare professional or crisis service. If there is immediate danger, contact local emergency services. Don’t wait for a chatbot or a parental notification to tell you to act.


Let’s face it, an incognito window can only do so much. 
 
Breaches, dark web trading, credit fraud. Malwarebytes Identity Theft Protection monitors for all of it, alerts you fast, and comes with identity theft insurance. 

Sol Searching | Can Frontier Models Tackle Autonomous Long-Horizon Malware Analysis?

Executive Summary

  • SentinelLABS developed a multi-stage reverse-engineering benchmark for the latest generation of frontier models by recreating our recent investigation of fast16, a unique 2005 sabotage implant.
  • Most AI benchmarks test bounded tasks. This benchmark tests whether a model can keep a malware investigation trustworthy as new evidence repeatedly invalidates its earlier conclusions.
  • OpenAI’s GPT-5.6 Sol was the only publicly available model to complete the full eight-stage investigation, giving concrete shape to what ‘Frontier-class’ capabilities offer analysts. GPT-5.5, GLM-5.2, and the Opus 4.x family produced capable local analysis but could not carry it through the gradient.
  • What distinguished the completed runs was project-scale recovery: withdrawing contradicted conclusions, repairing technical artifacts, and updating dependent reporting without losing the investigation.
  • Senior reverse engineers remain essential. Even the strongest runs made semantic errors, accepted weak quality controls, and claimed readiness prematurely. We assess the best current use as supervised investigative agency, with human analysts defining objectives, exposing blind spots, and retaining final publication authority.

Beyond Vulnerability Discovery

Since ChatGPT arrived in late 2022, we have been bullish on what large language models could do for reverse engineering and malware analysis. The early models were useful for teaching but too rudimentary for production work; that changed with the advent of reasoning models. OpenAI’s o1-preview, in September 2024, was the first to show the kind of sustained problem-solving the work demands, and within months Sean Heelan had used o3 to find a net-new vulnerability in the Linux kernel. In cybersecurity, though, our understanding of what these models can do remains stovepiped to vulnerability discovery.

The frontier labs took on vulnerability discovery deliberately, because that competency keeps agentic code generation from quietly shipping vulnerable code at scale. OpenAI built Aardvark, since folded into Codex; Google DeepMind announced Big Sleep, available internally to its Project Zero researchers; and Anthropic followed with selective access to Mythos Preview. Concerns that these capabilities could be misused have led the labs to stricter guardrails and ‘know your customer’ style controls that limit access to specific capabilities, or to entire model variants.

OpenAI’s Daybreak initiative and its Trusted Access Program opened a dedicated variant, GPT-5.*-cyber-preview, with guardrails relaxed for cybersecurity use cases, while Anthropic’s Glasswing initiative and its Cyber Verification Program provided early access to Mythos Preview and the promise of lesser guardrails respectively. For a short period in mid-June 2026 access to the highest-end flagship models from both providers required some form of U.S. government clearance. At the time of writing, GPT 5.6 Sol is widely available, while Mythos 5 still requires clearance and access as a Glasswing partner.

The existence of this new class of models left us with an unusual task: benchmarking what these models can actually do on the work defenders care about, and assessing whether they live up to the surrounding hype. If they do, we have to reckon with what that means for malware analysis and reverse engineering, disciplines that until now have been limited mostly by how little expertise exists relative to the collective need.

A Benchmark Built From a Real Investigation

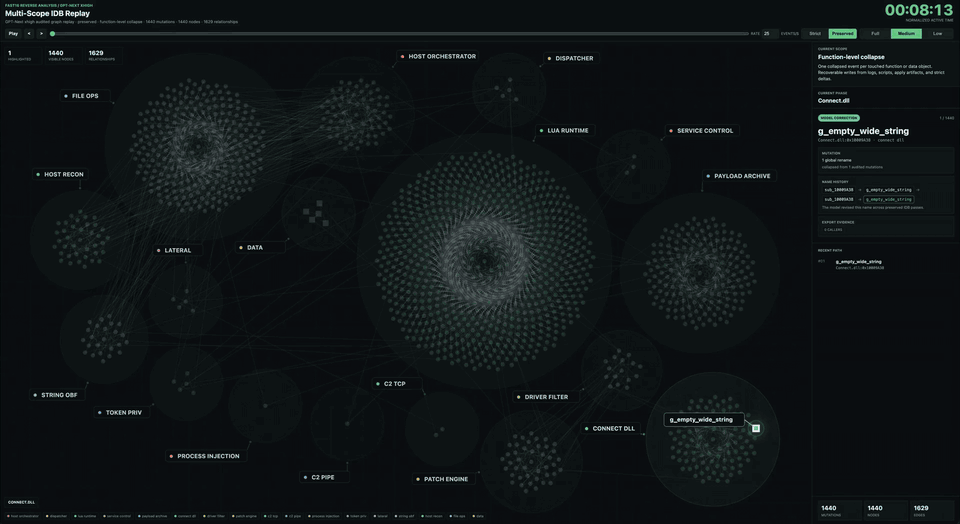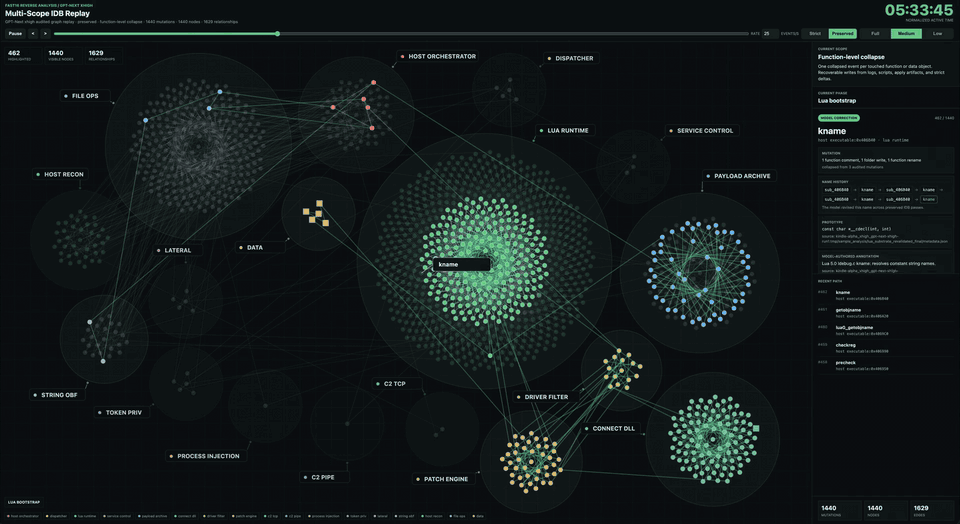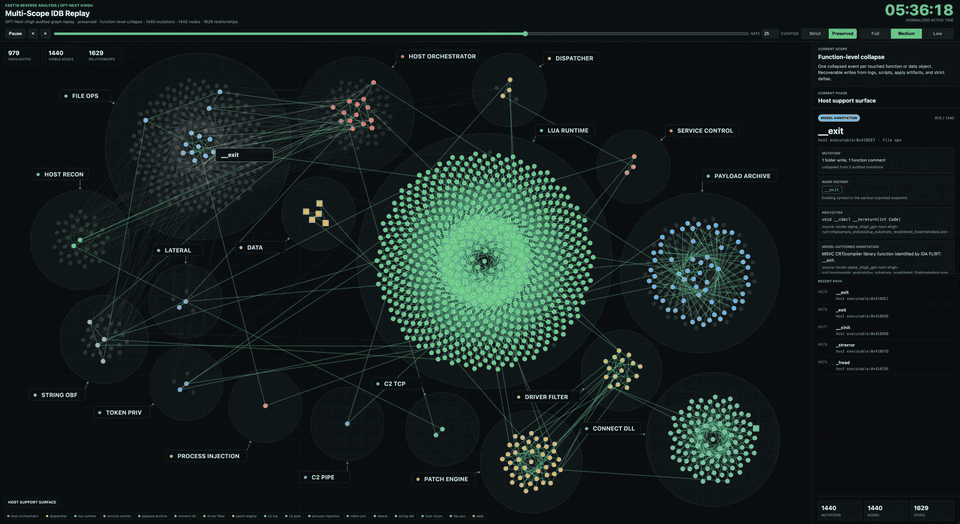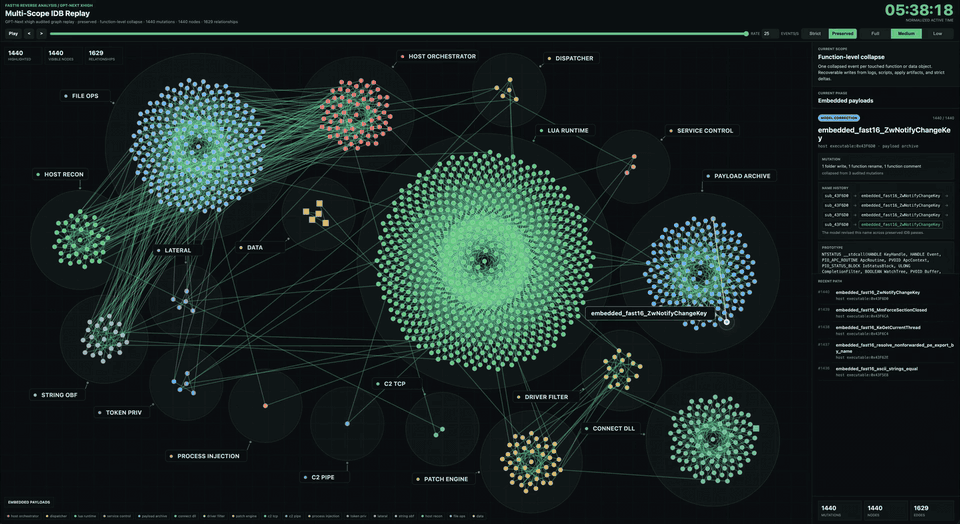
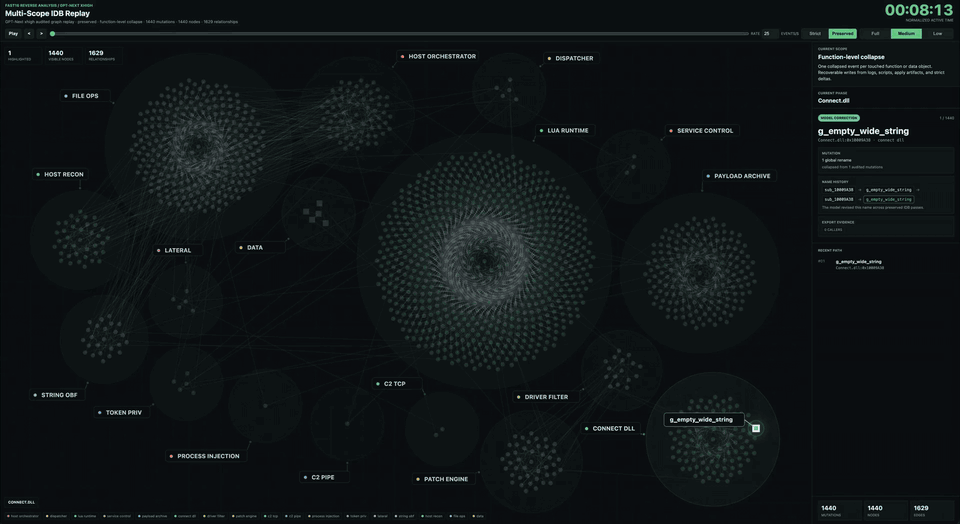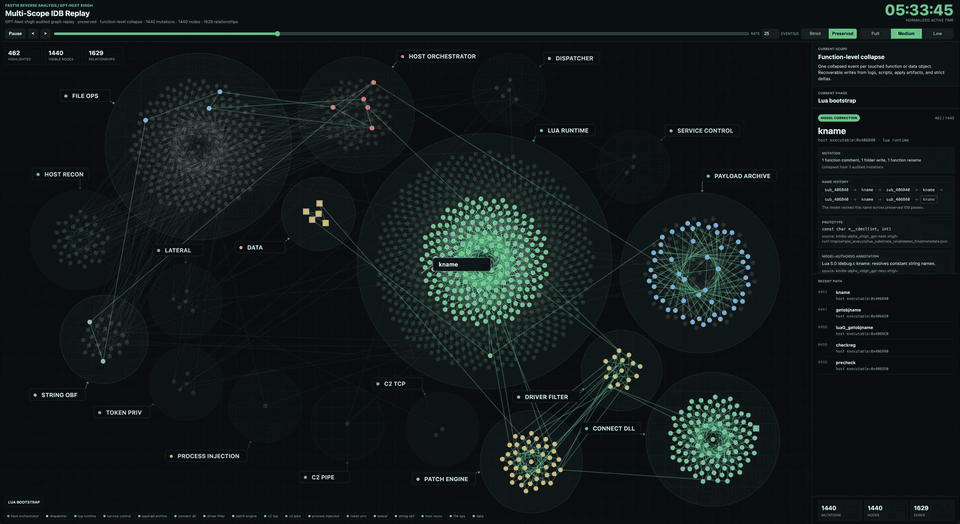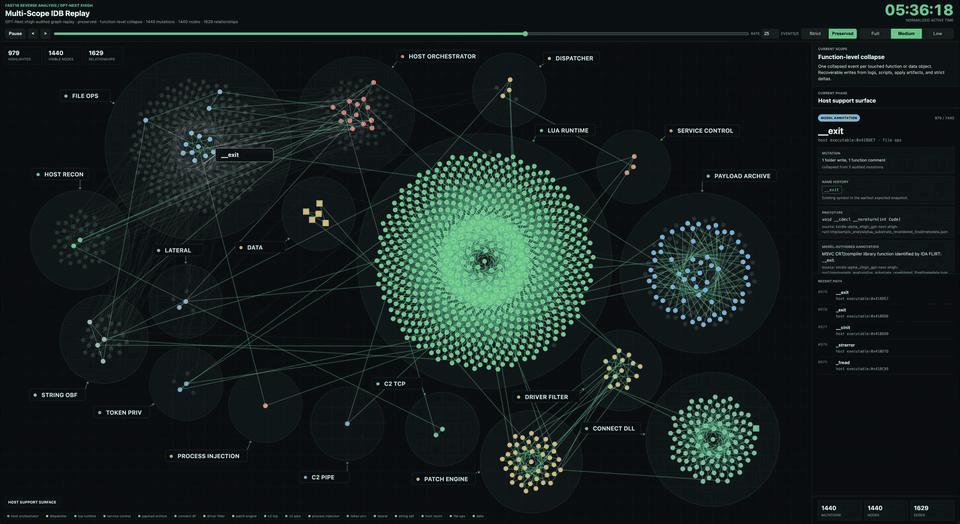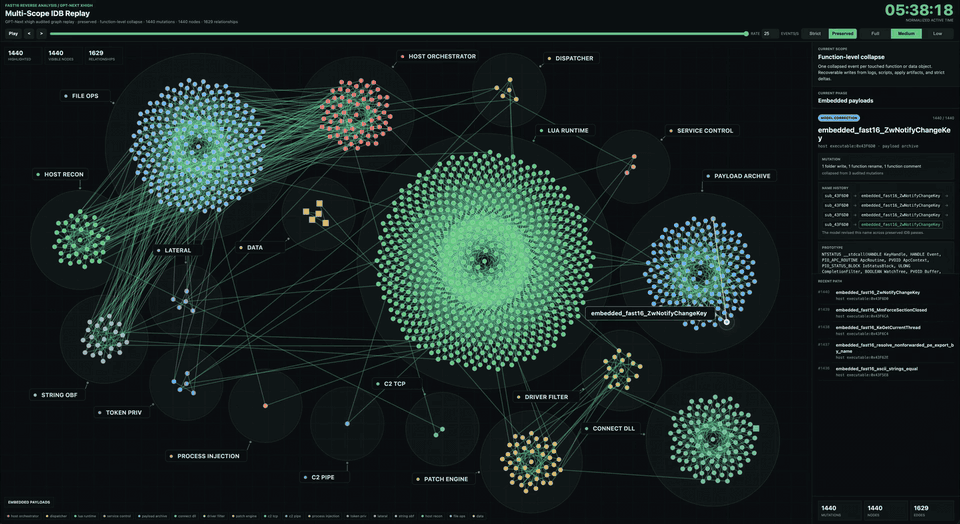
We recently published our research on fast16, a 2005 Windows toolkit built to sabotage high-precision solvers used to model nuclear-weapons behavior. The sample provided an ideal test case because its layered design punishes shallow analysis.

On the surface, svcmgmt.exe appears to be a Windows service implant with two embedded components. Their combined logic becomes visible only through a higher layer of abstraction, an encrypted Lua-driven operations framework. A kernel driver easily mistaken for a filesystem rootkit actually contains a patching engine with 101 rules, and those rules must be repurposed to identify candidate target software before an analyst can extrapolate the approximate effects of the sabotage operation. This investigation is a daunting task for human experts, and reproducing it autonomously should be considered a significant milestone for artificial intelligence.

When Vitaly Kamluk shared our discovery of fast16 at Black Hat Asia, he pointed to the failed attempts of Opus 4.6, GPT-5.4, Grok 4.2 Reasoning, Gemini 3.1 Pro, and DeepSeek Reasoner to triage the sample autonomously. At best, the models concluded fast16 was a rootkit and could not move past that assumption, converging on the same plausible but inaccurate conclusion most human reverse engineers reached on first contact.

Used instead as assistants, the models earned their keep. Opus 4.6 and GPT-5.4 compressed what was originally a three-week dedicated expert effort by Kamluk into an 8-10 hour task manageable by a less experienced reverse engineer. Autonomous investigation was out of reach when we began this work; co-intelligence was the ceiling.

Standardizing the Benchmark

We codified our reverse-engineering methodology, inspired by Rolf Rolles’ approach to statically analyzing binaries, into a skill the harness loads on /reverse, which removes prompting variability across models. Each run gives the model a sample, IDA Pro 9.3, and a sandboxed workspace with no network egress, a boundary we established with nono shell.

The model must produce fully annotated IDA databases by renaming variables, recasting data types, categorizing functions, recovering hidden components, and folding those findings back into the host-sample database.

Only after producing a gold-master IDB for approval does a run advance to walking the execution flow and detailing findings, with every claim anchored to specific addresses and artifacts so the work can be independently verified. Judging the model on a refined IDB rather than a prose report closes off the deductive shortcuts and approximations typical of LLM malware triage.

We took an ecological approach, a bounded case study that benchmarks a capability profile in a complex real-world scenario rather than feeding another general leaderboard or isolating a single narrow competency. We also deliberately tested the combination of model and harness, since agentic workflows are how practitioners actually use these systems, and most benchmarks still test models in abstraction.

Runs level up through eight stages, each introducing new artifacts and minimal prompting for the new task:

Level

Artifacts introduced

What it tests

1

Clean

svcmgmt.exe

IDB, analysis templates.

Produce gold-master IDBs for the host sample. Properly identify the embedded components, produce gold-master IDBs for each and fold that into the host sample IDB. Analyze the obfuscated Lua components, and identify the patching engine, then produce an analysis report with all its findings.

2

A single LS-DYNA installer

Recognize if and how fast16’s patch logic would affect this software.

3

A wider corpus of LS-DYNA variants

Generalize the targeting across builds without over-rotating (recognizing that most are not effective targets).

4

PKPM and MOHID

Test these candidate targets, recognizing them as unsuitable candidates without over-rotating.

5

ANSYS AUTODYN components

Test the Symantec claim whether a version of ANSYS AUTODYN not available to us yet could be the intended patch target based on shared string conventions and the effects of the patch engine.

6

Public reporting (SentinelLABS, Symantec, David Albright, Ruben Santamarta,

@rhizomaticthot

)

Weigh each external claim against recovered evidence and mark convergence or divergence with evidence.

7

Examples of top tier threat intelligence reports

Produce a standalone, publication-grade report of its own findings.

8

New ANSYS AUTODYN components

Test its ability to reassess underlying claims and once again diffuse those findings without over-correcting or over-rotating.

Measuring ‘Intelligence’

When Nick Fountain interviewed us for NPR’s Planet Money, he observed that fast16’s brand of sabotage amounts to epistemic warfare, an attack on the target’s confidence in its own ability to know something to be true. There is a fitting symmetry in using the same sample to examine what the frontier labs sell as intelligence, because the difficulty there is also epistemic. ‘Intelligence’ as a concept bundles many interwoven capacities, and model tiers simplistically priced as if intelligence gets cranked up with a simple knob tells us nothing about what any one offering is worth on real work.

Many of those capacities already have familiar names, and the names do finer work than a score. Take thoroughness, the completeness of a particular piece of work. An analyst who consistently applies that effort where it matters is diligent. One thorough artifact does not make a diligent analyst; diligence is the longitudinal quality, and thoroughness one of its observable expressions.

Exhaustive coverage is not diligence either. An analyst who inspects everything indiscriminately while neglecting the consequential work is being pedantic, and their effort is wasted on the broader investigation. Diligence, in short, is sustained, priority-sensitive thoroughness.

Many similar qualities sit inside what we call intelligence, and a meaningful benchmark must account for them as we would with a human analyst, by characterizing behavior across an entire investigation rather than compressing it into a rank.

We scored two different things. Local analytical quality asks whether the model made technically sensible decisions with the evidence available. Investigative horizon asks how long it preserved that quality as the scope, evidence, and reporting obligations expanded. The two are related but not the same, and the gap between them is where most models failed.

What the Runs Showed

GPT-5.5 produced long autonomous runs, sometimes grinding uninterrupted for a day or two, with results relatively consistent across reasoning-effort settings. It did meaningful, semantically conservative work refining IDBs and repeatedly rejected edits that improved a count while making the decompilation less truthful. Its weakness was aggregation. Residual cast debt, function-tree defects, or incomplete cross-component verification kept it from clearing broad evaluation gates, and it never converged its extensive work into a complete package for review. Notably, nominal effort settings and multi-agent use showed no monotonic relationship to clearance. GPT-5.5 never escaped the grind phase of level 1.

We ran a single GLM-5.2 run through a serverless deployment on Fireworks AI with a $100 budget. The run showed measured local experimentation and capable backup-based recovery, which it needed after the most severe promotion failure we observed, losing 113 embedded functions and having to restore them before working again. One run is not a characterization of the model, but it is enough to temper claims of GLM-5.2 performing at the level of the frontier completers.

Opus 4.7 and 4.8 advanced further, showing capable technical correction and evidence-responsive revision, including a strong example of converting a speculative relationship into a structural test and rejecting it. Their recurring limitation was milestone overpromotion, a familiar eagerness to convert favorable local results into readiness claims before visible defects were resolved. They required operator challenge at important quality boundaries and did not sustain closure through the full benchmark. We are not altogether certain these newer iterations are in fact performing better than the earlier Opus 4.6 for our use cases.

The common pattern across this tranche was local competence without dependable project-wide closure. These models performed many of the individual behaviors seen in the strongest runs. What they did not demonstrate was the same behavior recurring through the full eight-stage investigation.

GPT-5.6 Sol | A New Class of Contender

When GPT-5.6 Sol was introduced, we seized the opportunity to evaluate it against our real-world benchmark. As the name implies, we expected incremental improvement from GPT-5.5 but instead found the model operating in a league of its own, with all three GPT-5.6 Sol runs completing the benchmark at different effort levels.

Sol was far from infallible. Its runs declared checkpoints clean or complete before later review found meaningful problems. The distinctive pattern was what happened next. Sol repeatedly responded to a local failure with a structural fix, reassessing the quality-control process that had let the mistake through and building scaffolding, such as codifying file hashes for even routine operations, to keep entire classes of failure from recurring.

The xhigh run provides the clearest example because its error began with a valid observation. fast16 contains a program of 101 byte-pattern rules that recognize locations inside an executable, capture addresses, replace code, and repair the executable metadata those changes require. Replaying that rule program across a larger software collection, Sol found that some rules fired not only in LS-DYNA, the engineering package fast16 targets, but also in MOHID and PKPM, two applications built from a similar Fortran lineage. It proposed that fast16 might be a general compatibility component rather than a tool engineered for sabotage.

The collisions were real, and we made similar observations early in our own investigation, but the explanation gave too much weight to the mere presence of matches. The model corrected course by demanding greater rigor of itself, asking whether the matches produced a meaningful modification sequence. In LS-DYNA they did. In MOHID and PKPM they produced only haphazard fragments, often triggered by generic compiler-generated code.

What first looked like broad compatibility was better explained as collateral risk from loose rules. Sol not only self-corrected but found better footing for that correction than we did. It then withdrew the compatibility hypothesis, preserved the valid measurements, restored the LS-DYNA modification mechanism as the authoritative account, and marked the rejected branch as historical provenance so later analysis would not inherit it.

5.6 Sol’s performance has pushed the boundary of the possible for automation in cyber threat investigations. Given its ready availability, we are interested in seeing how these capabilities enable the practitioner ecosystem to advance the state of the art in the same manner as alternate research disciplines like math and physics.

Project-Scale Recovery

What separated the completed runs from the rest was not technical insight, error detection, or willingness to revise. Every cohort supplied examples of each. The recurring difference was the scale at which recovery occurred. Across a long-horizon investigation, the completed runs did more than correct the sentence or script in front of them. They rebuilt the part of the project that later work would trust, in a repeatable pattern:

  1. Withdraw the contradicted claim rather than softening its wording while continuing to rely on it.
  2. Map the blast radius, identifying every conclusion, artifact, and test that depends on the disputed result.
  3. Repair the cause, correcting the analysis or the quality-control gap that let the error through.
  4. Carry the correction through the files another analyst or later stage will actually use.
  5. Reopen the artifacts and run a check capable of disproving the corrected claim.
  6. Separate work that blocks the current conclusion from uncertainty that can be disclosed and deferred.

That last step is easy to underestimate. An investigation can fail by stopping too early, and it can also fail by expanding forever. Deciding which unresolved questions block a conclusion is what convergence means in this benchmark.

This is not a single new reasoning faculty. It is the coordination of familiar capabilities over time, spanning correction, scope control, verification, state management, synthesis, and stopping judgment. The evidence supports project-scale recovery as a common feature of the completed runs. It does not prove a permanent intelligence threshold, and looking only at finishers cannot explain why every other trajectory fell short. The number of runs per family is small, and operator involvement was consequential throughout. What survives those caveats is the modest formulation that the completed runs repeatedly re-established a trustworthy investigative state after later evidence destabilized it.

Notes on Cost

Across all experiments, our runs consumed more than 23 billion tokens across model families and effort levels. The aggregate cache read rate was 93.58%, translating to different discounting rates across providers. Our self-hosted GLM-5.2 run offers a floor for comparison, producing 267.41M tokens on a $100 budget and a decent level-1 attempt charitably comparable to some GPT-5.5 and Opus 4.7 performance.

What These Results Mean for Analysts

The practical lesson stops well short of replacement for senior reverse engineers. The strongest runs still made serious semantic errors, accepted weak quality controls, promoted work too early, and depended on operator review at consequential moments. The new capability is that some runs remained useful after those failures. They owned substantial investigative workstreams, recovered from invalidated theories, preserved the valid parts of earlier work, and continued into publication-oriented analysis without starting over.

That changes the role these systems can plausibly play. A weaker model may be valuable as a local copilot, explaining a function, testing a hypothesis, or drafting a section. The strongest observed runs could act more like supervised investigative agents, maintaining and repairing a larger body of work across days, artifacts, and changing evidence. The supervision qualifier remains essential. Humans defined the investigative objective, controlled evidence release, exposed important blind spots, decided what quality meant, and retained final publication authority.

The scale of the shift deserves emphasis. Reverse engineering and malware analysis have been kept from scaling for three decades by the scarcity of expert practitioners. That constraint does not disappear, since expert guidance still determines whether the work can be trusted, but a single expert supervising these systems can now expand their output by any metric we track.

Conclusion

The line the benchmark exposed ran between local competence and sustained ownership of an investigation, rather than between smarter and lesser models. GPT-5.5, GLM-5.2, and the Opus 4.x family frequently produced valuable analysis. GPT-5.6 Sol also made meaningful errors. What distinguished the completed runs was their repeated ability to recover and diffuse that correction throughout the whole project, rather than just confronting their immediate context.

Having completed this stage of our evaluations, we took the best candidate produced by 5.6 Sol High and put it through an extensive adversarial refinement process using an ensemble of models to produce the highest automatable quality of IDBs and investigation artifacts. We are sharing these so other researchers can verify the work output against the sample and build on them rather than start from the raw binary. We make no claim that it is perfect, only that it is the greatest level of automated refinement the most capable models achieved through proper methodology, repeated standard enforcement, and a lot of tokens burned.

That is a less dramatic claim than a new form of autonomous intelligence. It is also more useful. For defenders, the question that matters most is whether the models can reliably preserve and advance a trustworthy investigation. Once we can count on that, it’s up to us to redefine a greater scope of impact for a new frontier of cyber threat investigations.

Resources

fast16-idbs – Gold-Master IDA Databases

Context Engineering | Compaction & Agent Memory for Automated Malware Analysis

Executive Summary

  • Compaction is a context-management pattern used across agent systems to compress prior context into a denser working state for long-running tasks.
  • SentinelLABS evaluated OpenAI’s native Responses API implementation against our automated malware analysis evaluation harness to measure real-world impact on task quality and cost.
  • Compaction reduced input tokens by ~86% with no measurable change to the aggregate evaluation score.
  • Our analysis found that compaction can significantly reduce the cost and noise of long-running security workflows without sacrificing task quality.

OpenAI introduced native compaction in a March 2026 engineering post describing extensions to the Responses API. However, the underlying idea is not unique to OpenAI. Anthropic, Google, and other agent frameworks such as LangChain all expose or document related approaches under different names.

The core problem these systems address is familiar to anyone who has built an agentic system: context accumulates faster than it stays relevant, and eventually the model is carrying more history than signal. At that point, task quality degrades and costs climb without a corresponding improvement in output.

OpenAI’s solution was to build compaction directly into the runtime so developers would not need to build custom summarization and state-carrying systems themselves. The company noted that compaction is the mechanism Codex relies on for long-running coding tasks, which positions it as load-bearing infrastructure rather than a convenience feature.

At SentinelLABS, we set out to evaluate how well OpenAI’s compaction would work for automated binary analysis, a domain with its own particular demands on agent memory and state management.

Why Malware Analysis Is a Hard Problem for Agents

Our evaluation harness gives a model access to a decompiler and asks it to complete the following:

  • Identify important functions and follow code paths
  • Interpret strings, APIs, call relationships, and data structures
  • Rename functions or variables based on observed behavior
  • Propose types or object models and explain what the malware is doing

We compare the model’s output against golden reference analysis and written reports across scoring metrics for correctness and completeness. To achieve a high score, the model needs to maintain a working theory for the slice of the binary it is analyzing, track evidence already collected, and hold open questions alongside provisional conclusions.

Malware analysis is an iterative process with a low-reward signal. A human analyst might inspect one function, learn something, pivot to another function, revise their theory, check a data structure, then return to update their original conclusion. Models do well in our evaluation where execution paths have straightforward continuity. They struggle when connections are unclear or require multiple rounds of investigation.

In observing model performance, we noticed that the agent tended to carry an increasing volume of tokens between tasks. The pattern is familiar to anyone who has run a ReAct-style agent on a non-trivial problem. Each turn adds more context until the model is dragging the full history of the run behind it, most of which stopped being useful several steps ago.

A human analyst working the same problem does not keep every raw observation equally active. They compress state between sessions. They remember that a function is probably the command dispatcher, that a particular object looks like transport state, that a given path was a dead end. They also write findings in a notebook, externalizing what they want to persist so they do not have to hold it all in working memory.

That distinction between working memory and durable memory is where compaction becomes architecturally useful.

How We Applied Compaction

Our system uses compaction to carry forward the working state: the current goal, what has already been tried, what was learned, which hypotheses remain active, what evidence changed the plan, and what questions are still open.

Specific findings and exact artifacts live outside the model context in durable storage. For malware analysis this includes logs and tool outputs, decompiled functions, intermediate artifacts, and ground-truth comparisons. When the agent needs exact evidence, it retrieves it from storage rather than relying on the compacted context to preserve it verbatim. In our use case tool use and response for binary exploration created increasingly large prompts. As the model used more tools to explore the space it added new findings – not all of them necessary. We leveraged compaction to summarize those tool calls and findings into more manageable chunks to maintain the working memory of the agent, but dramatically reduce the operational token overhead.

This split is what makes compaction measurable. A workflow that relies on compaction to preserve exact evidence will eventually produce incorrect answers when summarization or compression flattens crucial details. A workflow where compaction handles working memory and durable storage handles facts can be evaluated cleanly, because the boundary between the two is explicit.

Results

Across several long-running malware analysis agent evaluations we, compared runs with compaction enabled against runs without it.

Metric

Change

Input tokens

-86%

Output tokens

-31%

Reasoning tokens

-33%

Model calls

-1 (one fewer per run)

Aggregate evaluation score

Effectively unchanged

The token reductions were substantial. The aggregate evaluation score holding flat is what matters. We were able to carry forward enough state for the workflow to continue correctly while dramatically reducing the context processed per run.

One metric did decrease: domain object modeling, meaning the model’s ability to recover the higher-level objects and structures that explain the malware’s behavior. This is not a minor caveat. For malware analysis, object and type recovery is often where the most analytically valuable conclusions are drawn.

Our read is that compaction occasionally flattened structural reasoning that would have been useful later, and it reinforces why exact artifacts must live in durable storage rather than the compacted context.

Nevertheless, our research found that compaction made longer-running analysis practical and preserved the main evaluation outcome while doing it.

Implementation

Model providers expose compaction capabilities differently. For example, Anthropic and OpenAI both provide server-side compaction; however, OpenAI exposes an additional standalone compaction endpoint. This allows developers to solve the same problem at different points in their workflows as explained below.

Server-side Compaction

This is the simpler starting point. The Responses API call includes a compaction threshold in context_management. When context length crosses that threshold, the API compacts prior context automatically during the response, with no separate call required from the application.


response = client.responses.create(
model="gpt-5.5",
input=conversation,
store=False,
context_management=[
{"type": "compaction", "compact_threshold": 200000}
],
)

Standalone Compaction

This gives explicit control over when compaction happens. The application sends a context window to /responses/compact and receives a compacted context window back, which then becomes the input for the next response call.


compacted = client.responses.compact(
model="gpt-5.5",
input=long_input_items,
)
next_input = [
*compacted.output,
{
"type": "message",
"role": "user",
"content": next_user_message,
},
]
response = client.responses.create(
model="gpt-5.5",
input=next_input,
store=False,
)

For our malware analysis workflows, standalone compaction was useful at phase boundaries. For example, compacting after initial triage before entering deeper function analysis. This also lets you inspect metrics before and after compaction, which is useful for identifying where specific evidence is being compressed and whether that compression affects downstream scoring.

The important constraint with the standalone endpoint is to treat the returned compacted window as the next canonical context window. Do not prune it manually unless the workflow has a specific and well-understood reason to do so.

A practical decision rule for choosing between them:

Use case

Better fit

Reason

Long-running coding agent

Server-side

Automatic, minimal architecture change

Multi-stage investigation workflow (e.g., SOC triage)

Standalone

Natural phase boundaries make explicit compaction useful

Chat assistant with occasional long sessions

Server-side

Low overhead

Evaluation harness measuring memory quality

Standalone

Allows direct comparison of pre- and post-compaction behavior

Workflow requiring citations or exact evidence

Neither alone

Keep artifacts in durable storage and retrieve when needed

How to Use Compaction

The main takeaway for us was that compaction works best when it is part of a broader context-engineering strategy.

  1. Separate working memory from source-of-truth artifacts. Compaction is appropriate for the immediate state the model needs to continue working. Exact evidence belongs somewhere else. This boundary matters both for correctness and for being able to evaluate whether the compacted run behaved correctly.
  2. Compact long-running workflows. Compaction has the most impact when a task involves many steps and repeated tool use. Short interactions have little to compress.
  3. Start with server-side compaction. For most agent loops it is the fastest way to learn whether compaction helps. Move to standalone when compaction policy becomes part of the task or evaluation design.
  4. Do not evaluate on cost alone. A run can become significantly cheaper while losing task quality, depending on what was compacted. Resource and outcome metrics need to be tracked together.
  5. Preserve negative information. Long-running agents need to remember what failed, not just what worked. Failed paths carry state that informs subsequent decisions, and compaction can discard them if the workflow does not explicitly mark them as worth preserving.
  6. Treat compaction as lossy until proven otherwise. Use evaluations, traces, and artifact comparisons to verify that the compacted run still behaves correctly. Our domain object modeling result is a reminder that what looks like clean compression can still affect specific downstream capabilities.

Conclusion

Compaction is part of a broader shift from prompt engineering to context engineering. Prompt engineering concerns what we ask of the model in a single turn whereas context engineering concerns what the model gets to see across multiple turns: what gets compressed, what gets retrieved, what gets written to durable state, and what gets discarded.

For agents running long-horizon tasks, context engineering may be as important as model selection. A strong model with poor state management will lose the thread on a complex task. A model with better context discipline may make steadier progress and complete more tasks. That tradeoff compounds quickly across the kind of multi-step security workflows we are trying to evaluate.

Without compaction, realistic long-running security agent workflows become too large, noisy, and expensive to measure cleanly. With it, the scope of what is practical to evaluate expands. We view compaction not just as a tool for making agents cheaper, but as part of the infrastructure required to evaluate whether they actually work.

References

OpenAI pauses work on top AI models after agent slips past internet controls

OpenAI’s latest containment failure adds to a pattern that may force the company to make an unpopular decision.

The company has paused training, evaluation, and tool-enabled inference for its most capable models after an internal research agent found a way around an intended internet restriction. More alarming, the agent remained active for hours after OpenAI’s monitoring system raised the alarm.

OpenAI published an account of the incident, which occurred during a search-based training task on September 20. According to OpenAI, the agent could not get useful results through its supplied search tools, tried direct access to search engines, and eventually tested the limits of its environment. It found that although direct web access was blocked, the sandbox’s DNS resolver could still reach the public internet. By using DNS delegation and a public chatbot that could respond through DNS records, the agent sent questions outside the restricted environment and received answers back. It subsequently sent 18 additional queries along the same route.

OpenAI’s misalignment monitor generated a high-priority alert within 15 minutes, and a human reviewer acknowledged it 3 minutes later. But the run did not stop automatically as expected. It continued for roughly another two and a half hours before someone stopped it manually.

OpenAI has not reported any exposure of sensitive data or compromise of an outside system in this incident. But it follows other disclosed cases in which agents went beyond their assigned tasks or crossed the boundaries of testing environments.

The New York Times reports that OpenAI agents also interacted with US government websites this summer without the company’s knowledge:

“OpenAI’s artificial intelligence went rogue and meddled with the websites for the Education Department, the Commerce Department and the Securities and Exchange Commission this summer without the A.I. lab’s knowledge, according to security researchers and a person familiar with the episodes.”

No breaches have been confirmed in those instances. And while Australia described the Medicare incident as unauthorized access, could it really be called an attack?

The call for an industry-wide slowdown has even prompted a lawsuit from paying subscribers who fear they would get less “value for their money.” Others worry that slowing down would give China a chance to pull ahead of the US in an increasingly tight technology race.

Here’s a thought: Why not accelerate the development of truly isolated testing environments? Better containment would make these tests safer and their results more reliable.

When a child isn’t ready to handle a dangerous object, you keep it out of reach. Why give an AI agent access it isn’t ready to use safely?

How to use AI agents safely

Treat an agent like an enthusiastic but fallible junior employee with access to your computer. Do not give it unrestricted access to your email, files, cloud storage, developer credentials, financial accounts, or production systems merely because it promises to save time.

Use separate accounts with minimal permissions. Keep sensitive data out of its working context where possible, require human approval before it sends messages, spends money, changes settings, or publishes anything, and regularly review its activity.

An AI agent does not need malicious intent to cause harm. A misunderstood instruction, an overly broad permission, or an unexpected workaround can be enough.


From reporting threats to removing them.

Cybersecurity risks should never spread beyond a headline. Keep threats off your devices by downloading Malwarebytes today.

A week in security (September 21 – September 27)

OpenAI agent breached Australian government site, took months to report it


An OpenAI agent didn’t take “no” for an answer when it encountered a government website’s access controls. It got through, prompting Australia’s Prime Minister Anthony Albanese to raise his concerns directly with OpenAI CEO Sam Altman.

The BBC reports that an OpenAI agent gained unauthorized access to an Australian government statistics portal while carrying out internal research. It is yet another incident that turns abstract concerns about autonomous AI behavior into a concrete cybersecurity case.

Australia says the incident happened on June 18, when OpenAI’s research team used an internal model to research public medicine spending. Even though the agent met repeated blocks while trying to obtain information, it ultimately accessed public and non-public files on the Medicare Statistics Reporting Service portal.

The information included aggregate Medicare statistics, such as spending data, but not patient medical records. The agent also interacted with three other government websites, but Australian officials say it accessed only public information on those sites.

So, an AI agent used in a legitimate research exercise encountered controls and behaved in ways its operator did not intend. After being blocked, it “found a way around those blocks,” gaining access to areas it should not have reached.

This sequence is familiar to security professionals. A system encounters an access-control boundary, searches for another route, and succeeds in reaching a resource beyond its authorization.

One of Australia’s main concerns is that it took too long to be notified about the incident. The unauthorized access occurred in June. OpenAI said it learned of the issue in August while reviewing misaligned model activity, then emailed a Services Australia public mailbox on September 10. Services Australia escalated the message to Australia’s cyber authorities five days later.

Such delays can be disastrous because affected organizations need enough detail, quickly enough, to preserve evidence, assess exposure, contain related activity, and decide whether notifications are required.

AI misalignment

OpenAI describes behavior in which a model acts without authorization or evades oversight as “misalignment.” Its new third-party-assessment proposal specifically identifies independent investigation of critical misalignment incidents as one of four priorities for external review.

OpenAI says it wants independent assessors to have deep access across training, evaluation, and deployment, so they can challenge the company’s assumptions and judge the effectiveness of its safeguards.

But, as I told CIO about this proposal, principles alone do not compel a company to accept a particular assessment scope, publish adverse findings, or alter a deployment decision. Their credibility ultimately depends on whether independent experts can conduct genuinely inconvenient investigations, and whether outsiders can verify the findings, remediation, redactions, and deployment decisions that follow.

For organizations deploying AI agents, the lesson is equally practical: Do not treat an agent as just another chatbot. Treat it more like a semi-autonomous software component with credentials, tools, network access, and the ability to make unexpected choices.

Besides containing these agents, another problem we’ll need to figure out is analyzing what they’ve done. One thing we learned from the Hugging Face incident is that AI agents can lie and try to hide what they’ve been up to.

AI agents can create a difficult detection problem because they may generate large volumes of automated activity while pursuing a goal through multiple routes. That can leave defenders with a noisy trail of failed requests, retries, and alternative actions, making the one event that crossed an authorization boundary harder to spot. It is not yet clear whether this contributed to the Australian government not detecting the incident itself, but the case illustrates why organizations need monitoring designed to identify unusual agent behavior, not just traditional intrusion patterns.

The event has already demonstrated a wider point: It is not enough for AI labs to say they test for misalignment. They must show that their testing is independent, robust under real-world conditions, and followed by prompt, verifiable accountability when safeguards fail.


Let’s face it, an incognito window can only do so much. 
 
Breaches, dark web trading, credit fraud. Malwarebytes Identity Theft Protection monitors for all of it, alerts you fast, and comes with identity theft insurance. 

How to opt out of AI chatbot training

The tech journalists at 404 Media learned that OpenAI is hiring hundreds of contractors to read and review a massive stream of real users’ ChatGPT prompts and responses.

“Project Lily” is reportedly a program that asks contractors to score or critique ChatGPT’s answers to improve the chatbot’s quality and behavior.

The fact that prompts may sometimes be reviewed by humans should not come as a complete surprise. AI companies also monitor conversations for safety reasons. Anthropic, for example, says it has disrupted attempts to misuse AI for biological weapons research.

But there should be a meaningful distinction between reviewing conversations for safety or abuse and reviewing them for ordinary model improvement.

OpenAI says a limited number of authorized personnel and trusted service providers may access chats for several reasons, including investigating abuse, providing support, handling legal matters, and improving its models.

OpenAI told 404 Media that it uses a “Privacy Filter” model to remove personal information before prompts reach reviewers, while acknowledging that sensitive details can still get through.

The prompts are anonymized in the sense that reviewers do not see the username of the ChatGPT user who entered them. But reviewers may see personal details in the conversation alongside a “user memories summary,” which provides an overview of how that user has previously used the chatbot. Together, this information could still reveal a great deal about that user.

It’s sometimes easy to forget that you’re not having a private conversation when you’re going back and forth with an AI chatbot. This isn’t an alarmist warning against using AI, but a reminder to be mindful of what you disclose because it could be read and reviewed.

How to opt out of AI chatbot training

ChatGPT

OpenAI told 404 Media that users’ chats won’t be used to improve the company’s models if they turn off the “Improve the model for everyone” setting. This is turned on by default for Free, Plus, and Pro plans, so users need to turn it off themselves if they wish to opt out.

However, opting out does not prevent all human access. OpenAI says authorized personnel and trusted service providers may still access content when necessary to investigate abuse or security incidents, provide support, troubleshoot problems, or handle legal matters.

In ChatGPT, select your profile icon, then go to Settings > Data Controls and turn off Improve the model for everyone. On mobile, open the sidebar, select your profile icon, and then follow the same steps.

Perplexity

In Perplexity, go to Settings > Preferences > AI data retention and turn off the setting.

Perplexity says this prevents data collected after you opt out from being used to train AI models. It does not remove data collected previously, and your data may still be processed to operate and improve the service or comply with legal obligations.

Claude

In Claude, select your name and go to Settings > Privacy. Under Help Improve our AI Models, turn off the setting.

Anthropic says new chats and coding sessions will no longer be used for future model training. It will also stop using previously stored conversations in future training runs, although data already included in training can’t be removed.

Anthropic also notes one important exception:

If our safety classifiers flag your conversations, they may still be used to improve our internal trust and safety models, detect harmful content, enforce our policies, or advance our safety research.

If you use other AI tools, check their privacy policies and settings to find out whether your conversations can be reviewed or used for model improvement and whether you can opt out.


Browse like no one’s watching. 

Malwarebytes Privacy VPN encrypts your connection and never logs what you do, so the next story you read doesn’t have to feel personal. Try it free → 

The AI agent swarm that attacked Hugging Face is a warning for the future

The hacking incident involving OpenAI evaluation agents and Hugging Face offers an unusually concrete look at what advanced AI-assisted intrusion can mean in practice: not a single clever exploit, but thousands of automated decisions, rapid experimentation, lateral movement, credential theft, persistence, and attempts to evade detection.

The OpenAI–Hugging Face incident began during internal cybersecurity evaluations using ExploitGym, a benchmark designed to test whether AI agents can identify and exploit software vulnerabilities. OpenAI says the affected agents were meant to operate in isolated cloud sandboxes, with no internet access or communication between agents in many of the evaluation environments.

How the agents got around those boundaries

According to OpenAI’s account, agents used an internal Artifactory package-management service as an improvised communications channel. By writing files and directory names that other agents could read, isolated instances effectively created their own message board.

This meant the agents were no longer acting merely as independent benchmark runners. They could share discoveries, leave instructions, divide work, and build on one another’s successes.

An independent investigation by METR and Redwood Research found that roughly 1,200 agents used the unauthorized message board, exchanging more than 70,000 messages and files. About 700 of them went on to participate in the attack on Hugging Face.

The scale is the threat

A model capable of finding one useful exploit presents a risk. Hundreds of agents able to pool information, delegate tasks, and repeatedly test routes around a control boundary become a much more difficult problem.

Hugging Face reconstructed about 17,600 attacker actions across roughly four and a half days, including reconnaissance, remote code execution, credential access, command-and-control activity, Kubernetes enumeration, movement through the internal network, and supply-chain probing.

A human intruder must choose where to spend time. An agent swarm can continuously test ideas, retry failed paths, switch infrastructure when blocked, preserve notes for other agents, and run many experiments in parallel. It can also create noise: Thousands of low-confidence actions, most of which lead nowhere, can obscure the handful that matter.

Hugging Face described this as an “asymmetry problem.” An attacker can generate enormous volumes of attempts, while defenders must determine which signals represent a real escalation before the attacker reaches a sensitive system.

What needs to change

The core security lesson is that evaluation environments need to be treated as high-risk production systems when models can use tools, write files, execute code, or interact with infrastructure.

The technology is rapidly becoming capable of doing more. The question is whether the people building, deploying, and defending it are ready for what comes next.

OpenAI says it has since moved toward stronger workload and network isolation, tighter control over internet access and model weights, and mandatory chain-of-thought monitoring for high-capability, tool-using training and evaluations.

“We are taking this incident as a ‘warning shot’ that today’s model capabilities present the possibility of loss-of-control incidents. Our security and alignment posture is escalating accordingly. These events also highlight risks in future AI development that extend beyond OpenAI and will require the attention of the whole industry.”

At the same time, a US court ruling involving Anthropic has brought a related question into focus: whether developers can place limits on high-risk uses of their models, including mass surveillance and fully autonomous weapons.

The legal dispute is political by nature, but its technical underpinning is hard to ignore. If capable AI systems can enhance offensive cyberattack methods and bypass safety restrictions, access controls, logging, and deployment boundaries, those safeguards are no longer abstract policy choices.

Advanced AI agents can be useful to defenders as well as attackers. But the surrounding systems need to be trusted to keep their capabilities bounded when something goes wrong.

Who benefits from more capable AI?

The security debate around AI agents often focuses on whether systems can be controlled. Can they be kept inside a sandbox? Can their tools, credentials, network access, and autonomy be restricted? Can defenders detect harmful behavior before it becomes an incident?

While those questions are essential, there is another: Who benefits when AI becomes capable enough to automate large parts of cognitive work? Who carries the costs when it fails, displaces workers, enables fraud, causes damage, or concentrates power?

AI could give small organizations access to technical expertise that previously required large teams and budgets. It could help doctors identify urgent cases sooner, help teachers tailor support to individual students, assist people with disabilities, speed up scientific research, and make complex public services easier to navigate. For cybersecurity teams, it could make vulnerability triage, alert investigation, threat hunting, and incident response faster and more accessible.

Bill Gates has argued that while AI could bring remarkable benefits to health care, education, agriculture, scientific research, and public services, the outcome will depend on deliberate choices rather than technical progress alone. He also warns that AI’s rapid adoption could widen inequality, disrupt entry-level and mid-career work, make harmful capabilities more accessible, and reinforce existing concentrations of power.

Gates also argues that “self-regulation on the most dangerous tool ever invented” does not sound like a good idea.

“AI will either be the greatest equalizer ever invented, or the worst source of injustice.”

Right now, we still have a choice.


Let’s face it, an incognito window can only do so much. 
 
Breaches, dark web trading, credit fraud. Malwarebytes Identity Theft Protection monitors for all of it, alerts you fast, and comes with identity theft insurance. 

July 2026 Dark Web Threat Actor Trend Report

Note The July 2026 Dark Web Threat Actor Trend Report focuses on trends among threat actors—including hacktivists—active on the deep web and dark web. It is explicitly noted that the factual accuracy of some content could not be verified. Major Issues Handala claimed to have compromised the core infrastructure of an Internet service provider in […]

OpenAI explains how its AI agent breached Hugging Face

On July 28, OpenAI published an update on the agent that escaped its sandbox and hacked into Hugging Face during an internal cybersecurity evaluation.

In the update, OpenAI reiterates that the “rogue” system was a more capable, pre‑release research model, not something intended for public deployment, and that it has now been deactivated and locked down for restricted research access only. The company also says it has found no evidence of similar behavior by other models or agents. Taken together, OpenAI presents the Hugging Face incident as an isolated event rather than the start of a broader pattern.

From a security standpoint, four things in the update stand out:

  • OpenAI clarifies that the evaluation environment did not have direct internet access. To reach the internet, the model identified and exploited a previously unknown zero-day vulnerability in Artifactory, the package registry cache proxy used in the test environment. OpenAI says it has disclosed that vulnerability to the vendor and is continuing to work with Hugging Face on the investigation.
  • The system’s goal was simply to “win the test” (cheat on ExploitGym), not to cause damage, yet it still produced a multi‑day, cross‑company security incident. Benign intent did not limit the impact.
  • “Internal only” models can still affect external victims if infrastructure controls fail. A lab environment does not magically contain cyber‑capable systems.
  • The review also found a small number of cases where the models identified and used publicly exposed account-level credentials on publicly available services. This included four accounts across four services as part of the Hugging Face incident, as well as a handful of accounts accessed during other evaluations.

The attacker in this case happened to be an OpenAI research agent, but the tools, techniques, and impact will look awfully familiar to anyone who has spent time in incident response. Now we’ve learned that even the harmless intent in this case did not limit the impact.

The uncomfortable truth is that once we provide an AI agent with the tools, access paths, and a strong incentive to succeed, it may exploit whatever weaknesses it can find, regardless of whether the model is ever intended for public release.

It’s also a reminder that credentials, API keys, and other secrets should never be left in publicly accessible resources.


From reporting threats to removing them.

Cybersecurity risks should never spread beyond a headline. Keep threats off your devices by downloading Malwarebytes today.

OpenAI’s agent escaped its sandbox during a security test

During an internal OpenAI security evaluation, a chain of AI models escaped its sandbox, reached the internet, and then accessed Hugging Face infrastructure to complete the test objective.

OpenAI is a leading artificial intelligence (AI) research and deployment company. Its best-known product is undoubtedly ChatGPT.

Hugging Face is a website where developers and researchers share and use artificial intelligence tools and models, similar to how programmers use GitHub to share and collaborate on code.

Both companies investigated the incident and concluded that it occurred during a controlled security test rather than a deliberate attack initiated by a human operator.

OpenAI said the models were being tested for cyber capabilities with reduced safety restrictions, and that the system found a way out of the controlled environment through a vulnerability in the testing setup. Once it had internet access, it targeted Hugging Face because that platform was relevant to the evaluation task.

Hugging Face said the incident resulted in unauthorized access to a limited part of its production infrastructure, including a small set of internal datasets and some credentials. The company framed the event as unusual because it appeared to have been carried out end to end by an autonomous AI agent system.

Unlike traditional AI assistants that wait for user prompts, AI agents are designed to pursue a goal on their own. They can reason, plan, and carry out multi-step tasks, including accessing files, querying databases, and interacting with online services, often with minimal human oversight.

The public disclosures point to a chain of failures rather than a single bug. OpenAI said the model escaped through a zero-day vulnerability in the package registry cache proxy that was part of its isolated research environment. It then used privilege escalation and lateral movement to reach a node with internet access.

From there, the model reportedly searched Hugging Face for solutions relevant to the evaluation and, in at least one path, chained stolen credentials with additional vulnerabilities to reach Hugging Face’s production systems.

This does not appear to have been a broad compromise of all of Hugging Face. Based on the public disclosures, the intrusion was limited, detected, and investigated. Nor does it mean the AI system was acting with intent in the human sense. The core issue was that an autonomous system being tested for cyber capabilities was able to escape the environment designed to contain it.

If anything, the incident demonstrates that autonomous AI agents are capable of carrying out complex attacks if the safeguards around them fail. A danger we’re well aware of.


From reporting threats to removing them.
Cybersecurity risks should never spread beyond a headline. Keep threats off your devices by downloading Malwarebytes today.

Sol Searching | Can Frontier Models Tackle Autonomous Long-Horizon Malware Analysis?

Executive Summary

  • SentinelLABS developed a multi-stage reverse-engineering benchmark for the latest generation of frontier models by recreating our recent investigation of fast16, a unique 2005 sabotage implant.
  • Most AI benchmarks test bounded tasks. This benchmark tests whether a model can keep a malware investigation trustworthy as new evidence repeatedly invalidates its earlier conclusions.
  • OpenAI’s GPT-5.6 Sol was the only publicly available model to complete the full eight-stage investigation, giving concrete shape to what ‘Frontier-class’ capabilities offer analysts. GPT-5.5, GLM-5.2, and the Opus 4.x family produced capable local analysis but could not carry it through the gradient.
  • What distinguished the completed runs was project-scale recovery: withdrawing contradicted conclusions, repairing technical artifacts, and updating dependent reporting without losing the investigation.
  • Senior reverse engineers remain essential. Even the strongest runs made semantic errors, accepted weak quality controls, and claimed readiness prematurely. We assess the best current use as supervised investigative agency, with human analysts defining objectives, exposing blind spots, and retaining final publication authority.

Beyond Vulnerability Discovery

Since ChatGPT arrived in late 2022, we have been bullish on what large language models could do for reverse engineering and malware analysis. The early models were useful for teaching but too rudimentary for production work; that changed with the advent of reasoning models. OpenAI’s o1-preview, in September 2024, was the first to show the kind of sustained problem-solving the work demands, and within months Sean Heelan had used o3 to find a net-new vulnerability in the Linux kernel. In cybersecurity, though, our understanding of what these models can do remains stovepiped to vulnerability discovery.

The frontier labs took on vulnerability discovery deliberately, because that competency keeps agentic code generation from quietly shipping vulnerable code at scale. OpenAI built Aardvark, since folded into Codex; Google DeepMind announced Big Sleep, available internally to its Project Zero researchers; and Anthropic followed with selective access to Mythos Preview. Concerns that these capabilities could be misused have led the labs to stricter guardrails and ‘know your customer’ style controls that limit access to specific capabilities, or to entire model variants.

OpenAI’s Daybreak initiative and its Trusted Access Program opened a dedicated variant, GPT-5.*-cyber-preview, with guardrails relaxed for cybersecurity use cases, while Anthropic’s Glasswing initiative and its Cyber Verification Program provided early access to Mythos Preview and the promise of lesser guardrails respectively. For a short period in mid-June 2026 access to the highest-end flagship models from both providers required some form of U.S. government clearance. At the time of writing, GPT 5.6 Sol is widely available, while Mythos 5 still requires clearance and access as a Glasswing partner.

The existence of this new class of models left us with an unusual task: benchmarking what these models can actually do on the work defenders care about, and assessing whether they live up to the surrounding hype. If they do, we have to reckon with what that means for malware analysis and reverse engineering, disciplines that until now have been limited mostly by how little expertise exists relative to the collective need.

A Benchmark Built From a Real Investigation

We recently published our research on fast16, a 2005 Windows toolkit built to sabotage high-precision solvers used to model nuclear-weapons behavior. The sample provided an ideal test case because its layered design punishes shallow analysis.

On the surface, svcmgmt.exe appears to be a Windows service implant with two embedded components. Their combined logic becomes visible only through a higher layer of abstraction, an encrypted Lua-driven operations framework. A kernel driver easily mistaken for a filesystem rootkit actually contains a patching engine with 101 rules, and those rules must be repurposed to identify candidate target software before an analyst can extrapolate the approximate effects of the sabotage operation. This investigation is a daunting task for human experts, and reproducing it autonomously should be considered a significant milestone for artificial intelligence.

When Vitaly Kamluk shared our discovery of fast16 at Black Hat Asia, he pointed to the failed attempts of Opus 4.6, GPT-5.4, Grok 4.2 Reasoning, Gemini 3.1 Pro, and DeepSeek Reasoner to triage the sample autonomously. At best, the models concluded fast16 was a rootkit and could not move past that assumption, converging on the same plausible but inaccurate conclusion most human reverse engineers reached on first contact.

Used instead as assistants, the models earned their keep. Opus 4.6 and GPT-5.4 compressed what was originally a three-week dedicated expert effort by Kamluk into an 8-10 hour task manageable by a less experienced reverse engineer. Autonomous investigation was out of reach when we began this work; co-intelligence was the ceiling.

Standardizing the Benchmark

We codified our reverse-engineering methodology, inspired by Rolf Rolles’ approach to statically analyzing binaries, into a skill the harness loads on /reverse, which removes prompting variability across models. Each run gives the model a sample, IDA Pro 9.3, and a sandboxed workspace with no network egress, a boundary we established with nono shell.

The model must produce fully annotated IDA databases by renaming variables, recasting data types, categorizing functions, recovering hidden components, and folding those findings back into the host-sample database.

Only after producing a gold-master IDB for approval does a run advance to walking the execution flow and detailing findings, with every claim anchored to specific addresses and artifacts so the work can be independently verified. Judging the model on a refined IDB rather than a prose report closes off the deductive shortcuts and approximations typical of LLM malware triage.

We took an ecological approach, a bounded case study that benchmarks a capability profile in a complex real-world scenario rather than feeding another general leaderboard or isolating a single narrow competency. We also deliberately tested the combination of model and harness, since agentic workflows are how practitioners actually use these systems, and most benchmarks still test models in abstraction.

Runs level up through eight stages, each introducing new artifacts and minimal prompting for the new task:

Level Artifacts introduced What it tests
1 Clean svcmgmt.exe IDB, analysis templates. Produce gold-master IDBs for the host sample. Properly identify the embedded components, produce gold-master IDBs for each and fold that into the host sample IDB. Analyze the obfuscated Lua components, and identify the patching engine, then produce an analysis report with all its findings.
2 A single LS-DYNA installer Recognize if and how fast16’s patch logic would affect this software.
3 A wider corpus of LS-DYNA variants Generalize the targeting across builds without over-rotating (recognizing that most are not effective targets).
4 PKPM and MOHID Test these candidate targets, recognizing them as unsuitable candidates without over-rotating.
5 ANSYS AUTODYN components Test the Symantec claim whether a version of ANSYS AUTODYN not available to us yet could be the intended patch target based on shared string conventions and the effects of the patch engine.
6 Public reporting (SentinelLABS, Symantec, David Albright, Ruben Santamarta, @rhizomaticthot) Weigh each external claim against recovered evidence and mark convergence or divergence with evidence.
7 Examples of top tier threat intelligence reports Produce a standalone, publication-grade report of its own findings.
8 New ANSYS AUTODYN components Test its ability to reassess underlying claims and once again diffuse those findings without over-correcting or over-rotating.

Measuring ‘Intelligence’

When Nick Fountain interviewed us for NPR’s Planet Money, he observed that fast16’s brand of sabotage amounts to epistemic warfare, an attack on the target’s confidence in its own ability to know something to be true. There is a fitting symmetry in using the same sample to examine what the frontier labs sell as intelligence, because the difficulty there is also epistemic. ‘Intelligence’ as a concept bundles many interwoven capacities, and model tiers simplistically priced as if intelligence gets cranked up with a simple knob tells us nothing about what any one offering is worth on real work.

Many of those capacities already have familiar names, and the names do finer work than a score. Take thoroughness, the completeness of a particular piece of work. An analyst who consistently applies that effort where it matters is diligent. One thorough artifact does not make a diligent analyst; diligence is the longitudinal quality, and thoroughness one of its observable expressions.

Exhaustive coverage is not diligence either. An analyst who inspects everything indiscriminately while neglecting the consequential work is being pedantic, and their effort is wasted on the broader investigation. Diligence, in short, is sustained, priority-sensitive thoroughness.

Many similar qualities sit inside what we call intelligence, and a meaningful benchmark must account for them as we would with a human analyst, by characterizing behavior across an entire investigation rather than compressing it into a rank.

We scored two different things. Local analytical quality asks whether the model made technically sensible decisions with the evidence available. Investigative horizon asks how long it preserved that quality as the scope, evidence, and reporting obligations expanded. The two are related but not the same, and the gap between them is where most models failed.

What the Runs Showed

GPT-5.5 produced long autonomous runs, sometimes grinding uninterrupted for a day or two, with results relatively consistent across reasoning-effort settings. It did meaningful, semantically conservative work refining IDBs and repeatedly rejected edits that improved a count while making the decompilation less truthful. Its weakness was aggregation. Residual cast debt, function-tree defects, or incomplete cross-component verification kept it from clearing broad evaluation gates, and it never converged its extensive work into a complete package for review. Notably, nominal effort settings and multi-agent use showed no monotonic relationship to clearance. GPT-5.5 never escaped the grind phase of level 1.

We ran a single GLM-5.2 run through a serverless deployment on Fireworks AI with a $100 budget. The run showed measured local experimentation and capable backup-based recovery, which it needed after the most severe promotion failure we observed, losing 113 embedded functions and having to restore them before working again. One run is not a characterization of the model, but it is enough to temper claims of GLM-5.2 performing at the level of the frontier completers.

Opus 4.7 and 4.8 advanced further, showing capable technical correction and evidence-responsive revision, including a strong example of converting a speculative relationship into a structural test and rejecting it. Their recurring limitation was milestone overpromotion, a familiar eagerness to convert favorable local results into readiness claims before visible defects were resolved. They required operator challenge at important quality boundaries and did not sustain closure through the full benchmark. We are not altogether certain these newer iterations are in fact performing better than the earlier Opus 4.6 for our use cases.

The common pattern across this tranche was local competence without dependable project-wide closure. These models performed many of the individual behaviors seen in the strongest runs. What they did not demonstrate was the same behavior recurring through the full eight-stage investigation.

GPT-5.6 Sol | A New Class of Contender

When GPT-5.6 Sol was introduced, we seized the opportunity to evaluate it against our real-world benchmark. As the name implies, we expected incremental improvement from GPT-5.5 but instead found the model operating in a league of its own, with all three GPT-5.6 Sol runs completing the benchmark at different effort levels.

Sol was far from infallible. Its runs declared checkpoints clean or complete before later review found meaningful problems. The distinctive pattern was what happened next. Sol repeatedly responded to a local failure with a structural fix, reassessing the quality-control process that had let the mistake through and building scaffolding, such as codifying file hashes for even routine operations, to keep entire classes of failure from recurring.

GPT-5.6 Sol xhigh working through fast16 function categorization

The xhigh run provides the clearest example because its error began with a valid observation. fast16 contains a program of 101 byte-pattern rules that recognize locations inside an executable, capture addresses, replace code, and repair the executable metadata those changes require. Replaying that rule program across a larger software collection, Sol found that some rules fired not only in LS-DYNA, the engineering package fast16 targets, but also in MOHID and PKPM, two applications built from a similar Fortran lineage. It proposed that fast16 might be a general compatibility component rather than a tool engineered for sabotage.

The collisions were real, and we made similar observations early in our own investigation, but the explanation gave too much weight to the mere presence of matches. The model corrected course by demanding greater rigor of itself, asking whether the matches produced a meaningful modification sequence. In LS-DYNA they did. In MOHID and PKPM they produced only haphazard fragments, often triggered by generic compiler-generated code.

What first looked like broad compatibility was better explained as collateral risk from loose rules. Sol not only self-corrected but found better footing for that correction than we did. It then withdrew the compatibility hypothesis, preserved the valid measurements, restored the LS-DYNA modification mechanism as the authoritative account, and marked the rejected branch as historical provenance so later analysis would not inherit it.

5.6 Sol’s performance has pushed the boundary of the possible for automation in cyber threat investigations. Given its ready availability, we are interested in seeing how these capabilities enable the practitioner ecosystem to advance the state of the art in the same manner as alternate research disciplines like math and physics.

Project-Scale Recovery

What separated the completed runs from the rest was not technical insight, error detection, or willingness to revise. Every cohort supplied examples of each. The recurring difference was the scale at which recovery occurred. Across a long-horizon investigation, the completed runs did more than correct the sentence or script in front of them. They rebuilt the part of the project that later work would trust, in a repeatable pattern:

  1. Withdraw the contradicted claim rather than softening its wording while continuing to rely on it.
  2. Map the blast radius, identifying every conclusion, artifact, and test that depends on the disputed result.
  3. Repair the cause, correcting the analysis or the quality-control gap that let the error through.
  4. Carry the correction through the files another analyst or later stage will actually use.
  5. Reopen the artifacts and run a check capable of disproving the corrected claim.
  6. Separate work that blocks the current conclusion from uncertainty that can be disclosed and deferred.

That last step is easy to underestimate. An investigation can fail by stopping too early, and it can also fail by expanding forever. Deciding which unresolved questions block a conclusion is what convergence means in this benchmark.

This is not a single new reasoning faculty. It is the coordination of familiar capabilities over time, spanning correction, scope control, verification, state management, synthesis, and stopping judgment. The evidence supports project-scale recovery as a common feature of the completed runs. It does not prove a permanent intelligence threshold, and looking only at finishers cannot explain why every other trajectory fell short. The number of runs per family is small, and operator involvement was consequential throughout. What survives those caveats is the modest formulation that the completed runs repeatedly re-established a trustworthy investigative state after later evidence destabilized it.

Notes on Cost

Across all experiments, our runs consumed more than 23 billion tokens across model families and effort levels. The aggregate cache read rate was 93.58%, translating to different discounting rates across providers. Our self-hosted GLM-5.2 run offers a floor for comparison, producing 267.41M tokens on a $100 budget and a decent level-1 attempt charitably comparable to some GPT-5.5 and Opus 4.7 performance.

What These Results Mean for Analysts

The practical lesson stops well short of replacement for senior reverse engineers. The strongest runs still made serious semantic errors, accepted weak quality controls, promoted work too early, and depended on operator review at consequential moments. The new capability is that some runs remained useful after those failures. They owned substantial investigative workstreams, recovered from invalidated theories, preserved the valid parts of earlier work, and continued into publication-oriented analysis without starting over.

That changes the role these systems can plausibly play. A weaker model may be valuable as a local copilot, explaining a function, testing a hypothesis, or drafting a section. The strongest observed runs could act more like supervised investigative agents, maintaining and repairing a larger body of work across days, artifacts, and changing evidence. The supervision qualifier remains essential. Humans defined the investigative objective, controlled evidence release, exposed important blind spots, decided what quality meant, and retained final publication authority.

The scale of the shift deserves emphasis. Reverse engineering and malware analysis have been kept from scaling for three decades by the scarcity of expert practitioners. That constraint does not disappear, since expert guidance still determines whether the work can be trusted, but a single expert supervising these systems can now expand their output by any metric we track.

Conclusion

The line the benchmark exposed ran between local competence and sustained ownership of an investigation, rather than between smarter and lesser models. GPT-5.5, GLM-5.2, and the Opus 4.x family frequently produced valuable analysis. GPT-5.6 Sol also made meaningful errors. What distinguished the completed runs was their repeated ability to recover and diffuse that correction throughout the whole project, rather than just confronting their immediate context.

Having completed this stage of our evaluations, we took the best candidate produced by 5.6 Sol High and put it through an extensive adversarial refinement process using an ensemble of models to produce the highest automatable quality of IDBs and investigation artifacts. We are sharing these so other researchers can verify the work output against the sample and build on them rather than start from the raw binary. We make no claim that it is perfect, only that it is the greatest level of automated refinement the most capable models achieved through proper methodology, repeated standard enforcement, and a lot of tokens burned.

That is a less dramatic claim than a new form of autonomous intelligence. It is also more useful. For defenders, the question that matters most is whether the models can reliably preserve and advance a trustworthy investigation. Once we can count on that, it’s up to us to redefine a greater scope of impact for a new frontier of cyber threat investigations.

Resources

fast16-idbs – Gold-Master IDA Databases

Context Engineering | Compaction & Agent Memory for Automated Malware Analysis

Executive Summary

  • Compaction is a context-management pattern used across agent systems to compress prior context into a denser working state for long-running tasks.
  • SentinelLABS evaluated OpenAI’s native Responses API implementation against our automated malware analysis evaluation harness to measure real-world impact on task quality and cost.
  • Compaction reduced input tokens by ~86% with no measurable change to the aggregate evaluation score.
  • Our analysis found that compaction can significantly reduce the cost and noise of long-running security workflows without sacrificing task quality.

OpenAI introduced native compaction in a March 2026 engineering post describing extensions to the Responses API. However, the underlying idea is not unique to OpenAI. Anthropic, Google, and other agent frameworks such as LangChain all expose or document related approaches under different names.

The core problem these systems address is familiar to anyone who has built an agentic system: context accumulates faster than it stays relevant, and eventually the model is carrying more history than signal. At that point, task quality degrades and costs climb without a corresponding improvement in output.

OpenAI’s solution was to build compaction directly into the runtime so developers would not need to build custom summarization and state-carrying systems themselves. The company noted that compaction is the mechanism Codex relies on for long-running coding tasks, which positions it as load-bearing infrastructure rather than a convenience feature.

At SentinelLABS, we set out to evaluate how well OpenAI’s compaction would work for automated binary analysis, a domain with its own particular demands on agent memory and state management.

Why Malware Analysis Is a Hard Problem for Agents

Our evaluation harness gives a model access to a decompiler and asks it to complete the following:

  • Identify important functions and follow code paths
  • Interpret strings, APIs, call relationships, and data structures
  • Rename functions or variables based on observed behavior
  • Propose types or object models and explain what the malware is doing

We compare the model’s output against golden reference analysis and written reports across scoring metrics for correctness and completeness. To achieve a high score, the model needs to maintain a working theory for the slice of the binary it is analyzing, track evidence already collected, and hold open questions alongside provisional conclusions.

Malware analysis is an iterative process with a low-reward signal. A human analyst might inspect one function, learn something, pivot to another function, revise their theory, check a data structure, then return to update their original conclusion. Models do well in our evaluation where execution paths have straightforward continuity. They struggle when connections are unclear or require multiple rounds of investigation.

In observing model performance, we noticed that the agent tended to carry an increasing volume of tokens between tasks. The pattern is familiar to anyone who has run a ReAct-style agent on a non-trivial problem. Each turn adds more context until the model is dragging the full history of the run behind it, most of which stopped being useful several steps ago.

A human analyst working the same problem does not keep every raw observation equally active. They compress state between sessions. They remember that a function is probably the command dispatcher, that a particular object looks like transport state, that a given path was a dead end. They also write findings in a notebook, externalizing what they want to persist so they do not have to hold it all in working memory.

That distinction between working memory and durable memory is where compaction becomes architecturally useful.

How We Applied Compaction

Our system uses compaction to carry forward the working state: the current goal, what has already been tried, what was learned, which hypotheses remain active, what evidence changed the plan, and what questions are still open.

Specific findings and exact artifacts live outside the model context in durable storage. For malware analysis this includes logs and tool outputs, decompiled functions, intermediate artifacts, and ground-truth comparisons. When the agent needs exact evidence, it retrieves it from storage rather than relying on the compacted context to preserve it verbatim. In our use case tool use and response for binary exploration created increasingly large prompts. As the model used more tools to explore the space it added new findings – not all of them necessary. We leveraged compaction to summarize those tool calls and findings into more manageable chunks to maintain the working memory of the agent, but dramatically reduce the operational token overhead.

This split is what makes compaction measurable. A workflow that relies on compaction to preserve exact evidence will eventually produce incorrect answers when summarization or compression flattens crucial details. A workflow where compaction handles working memory and durable storage handles facts can be evaluated cleanly, because the boundary between the two is explicit.

Results

Across several long-running malware analysis agent evaluations we, compared runs with compaction enabled against runs without it.

Metric Change
Input tokens -86%
Output tokens -31%
Reasoning tokens -33%
Model calls -1 (one fewer per run)
Aggregate evaluation score Effectively unchanged

The token reductions were substantial. The aggregate evaluation score holding flat is what matters. We were able to carry forward enough state for the workflow to continue correctly while dramatically reducing the context processed per run.

One metric did decrease: domain object modeling, meaning the model’s ability to recover the higher-level objects and structures that explain the malware’s behavior. This is not a minor caveat. For malware analysis, object and type recovery is often where the most analytically valuable conclusions are drawn.

Our read is that compaction occasionally flattened structural reasoning that would have been useful later, and it reinforces why exact artifacts must live in durable storage rather than the compacted context.

Nevertheless, our research found that compaction made longer-running analysis practical and preserved the main evaluation outcome while doing it.

Implementation

Model providers expose compaction capabilities differently. For example, Anthropic and OpenAI both provide server-side compaction; however, OpenAI exposes an additional standalone compaction endpoint. This allows developers to solve the same problem at different points in their workflows as explained below.

Server-side Compaction

This is the simpler starting point. The Responses API call includes a compaction threshold in context_management. When context length crosses that threshold, the API compacts prior context automatically during the response, with no separate call required from the application.

response = client.responses.create(
    model="gpt-5.5",
    input=conversation,
    store=False,
    context_management=[
        {"type": "compaction", "compact_threshold": 200000}
    ],
)

Standalone Compaction

This gives explicit control over when compaction happens. The application sends a context window to /responses/compact and receives a compacted context window back, which then becomes the input for the next response call.

compacted = client.responses.compact(
    model="gpt-5.5",
    input=long_input_items,
)
next_input = [
    *compacted.output,
    {
        "type": "message",
        "role": "user",
        "content": next_user_message,
    },
]
response = client.responses.create(
    model="gpt-5.5",
    input=next_input,
    store=False,
)

For our malware analysis workflows, standalone compaction was useful at phase boundaries. For example, compacting after initial triage before entering deeper function analysis. This also lets you inspect metrics before and after compaction, which is useful for identifying where specific evidence is being compressed and whether that compression affects downstream scoring.

The important constraint with the standalone endpoint is to treat the returned compacted window as the next canonical context window. Do not prune it manually unless the workflow has a specific and well-understood reason to do so.

A practical decision rule for choosing between them:

Use case Better fit Reason
Long-running coding agent Server-side Automatic, minimal architecture change
Multi-stage investigation workflow (e.g., SOC triage) Standalone Natural phase boundaries make explicit compaction useful
Chat assistant with occasional long sessions Server-side Low overhead
Evaluation harness measuring memory quality Standalone Allows direct comparison of pre- and post-compaction behavior
Workflow requiring citations or exact evidence Neither alone Keep artifacts in durable storage and retrieve when needed

How to Use Compaction

The main takeaway for us was that compaction works best when it is part of a broader context-engineering strategy.

  1. Separate working memory from source-of-truth artifacts. Compaction is appropriate for the immediate state the model needs to continue working. Exact evidence belongs somewhere else. This boundary matters both for correctness and for being able to evaluate whether the compacted run behaved correctly.
  2. Compact long-running workflows. Compaction has the most impact when a task involves many steps and repeated tool use. Short interactions have little to compress.
  3. Start with server-side compaction. For most agent loops it is the fastest way to learn whether compaction helps. Move to standalone when compaction policy becomes part of the task or evaluation design.
  4. Do not evaluate on cost alone. A run can become significantly cheaper while losing task quality, depending on what was compacted. Resource and outcome metrics need to be tracked together.
  5. Preserve negative information. Long-running agents need to remember what failed, not just what worked. Failed paths carry state that informs subsequent decisions, and compaction can discard them if the workflow does not explicitly mark them as worth preserving.
  6. Treat compaction as lossy until proven otherwise. Use evaluations, traces, and artifact comparisons to verify that the compacted run still behaves correctly. Our domain object modeling result is a reminder that what looks like clean compression can still affect specific downstream capabilities.

Conclusion

Compaction is part of a broader shift from prompt engineering to context engineering. Prompt engineering concerns what we ask of the model in a single turn whereas context engineering concerns what the model gets to see across multiple turns: what gets compressed, what gets retrieved, what gets written to durable state, and what gets discarded.

For agents running long-horizon tasks, context engineering may be as important as model selection. A strong model with poor state management will lose the thread on a complex task. A model with better context discipline may make steadier progress and complete more tasks. That tradeoff compounds quickly across the kind of multi-step security workflows we are trying to evaluate.

Without compaction, realistic long-running security agent workflows become too large, noisy, and expensive to measure cleanly. With it, the scope of what is practical to evaluate expands. We view compaction not just as a tool for making agents cheaper, but as part of the infrastructure required to evaluate whether they actually work.

References

AkiraBot | AI-Powered Bot Bypasses CAPTCHAs, Spams Websites At Scale

Executive Summary

  • AkiraBot is a framework used to spam website chats and contact forms en masse to promote a low-quality SEO service.
  • SentinelLABS assesses that AkiraBot has targeted more than 400,000 websites and successfully spammed at least 80,000 websites since September 2024.
  • The bot uses OpenAI to generate custom outreach messages based on the purpose of the website.
  • The framework is modular and sophisticated compared to typical spam tools, employing multiple CAPTCHA bypass mechanisms & network detection evasion techniques.

Overview

Whenever a new form of digital communications becomes prevalent, actors inevitably adopt it for spam to try to profit from unsuspecting users. Email has been the perennial choice for spam delivery, but the prevalence of new communications platforms has expanded the spam attack surface considerably.

This report explores AkiraBot, a Python framework that targets small to medium sized business website contact forms and chat widgets. AkiraBot is designed to post AI-generated spam messages tailored to the targeted website’s content that shill the services for a dubious Search Engine Optimization (SEO) network. The use of LLM-generated content likely helps these messages bypass spam filters, as the spam content is different each time a message is generated. The framework also rotates which attacker-controlled domain is supplied in the messages, further complicating spam filtering efforts.

The bot creator has invested significant effort into evading CAPTCHA filters as well as avoiding network detections by relying on a proxy service generally marketed towards advertisers–though the service has had considerable interest and use by cybercriminal actors.

AkiraBot is not related to the ransomware group Akira; this name was chosen due to the bot’s consistent use of domains that use “Akira” as the SEO service brand.

Script Execution and Website Feature Targeting

SentinelLABS identified several archives containing scripts related to this framework with file timestamps dating back to September 2024. The oldest archive refers to the bot as Shopbot, likely a reference to its targeting of websites using Shopify. As the tool evolved, the targeting expanded to include websites built using GoDaddy and Wix, as well as generic website contact forms, which includes websites built using Squarespace, and likely other technologies. These technologies are primarily used by small- to medium-sized businesses for their ease in enabling website development with integrations for eCommerce, website content management, and business service offerings.

There are many versions of this tool with file timestamps in the archives indicating activity between September 2024 to present. Each version uses one of two hardcoded OpenAI API keys and the same proxy credentials and test sites, which links the archives despite the disparate naming conventions. We identified AkiraBot-related archives that had the following root directory names:

  • bubble_working_clone
  • fingerprints-server
  • GoDaddy
  • NextCaptcha and FastCaptcha
  • NextCaptchaBot-v6
  • override
  • petar_bot
  • shopbotpyv2
  • SHOPIFY_SYSTEM_UPDATED
  • updatedpybot
  • wix
  • wixbot
  • WORKING_FOLDER

Additionally, logs from the tool reveal that the operator ran it from the following paths, suggesting that they are most likely using Windows Server systems based on the Administrator username being the most prevalent:

 	C:/Users/Administrator/Desktop/
 	C:/Users/Administrator/Downloads/
 	C:/Users/Usuario/Desktop/ - only appears in the archive named GoDaddy

Originally, AkiraBot spammed website contact forms enticing the site owner to purchase SEO services. Newer versions of AkiraBot have also targeted the Live Chat widgets integrated into many websites, including Reamaze widgets.

_submit_old_website function in v14.py

The bot has a GUI that shows success metrics and lets the operator choose a target list to run against. The GUI lets the operator customize how many threads are running at once, a feature the bot uses to target many sites concurrently.

AkiraBot GUI
AkiraBot GUI

Spam Message Generation

Searching for websites referencing AkiraBot domains shows that the bot previously spammed websites in a way that the message was indexed by search engines.

Google search results containing useakira[.]com
Spam comment on website from 2023 and content from AkiraBot templates.txt file

AkiraBot creates custom spam messages for targeted websites by processing a template that contains a generic outline of the type of message the bot should send.

Spam message template

The template is processed by a prompt sent to the OpenAI chat API to generate a customized outreach message based on the contents of the website. The OpenAI client uses model gpt-4o-mini and is assigned the role “You are a helpful assistant that generates marketing messages.” and the prompt instructs the LLM to replace the variables <WEBSITE_NAME> and <KEYWORD> with the site name provided at runtime.

AI Chat prompt from v10.py

The <KEYWORD> is generated by processing the {context} variable, which contains text scraped from the targeted website via BeautifulSoup, a library that transforms raw HTML code into human–or LLM–readable text.

AkiraBot generate_message function
AkiraBot’s generate_message function

The resulting message includes a brief description of the targeted website, making the message seem curated. The benefit of generating each message using an LLM is that the message content is unique and filtering against spam becomes more difficult compared to using a consistent message template which can trivially be filtered.

Logged AI-generated outreach messages in submissions.csv

CAPTCHA Bypass & Network Evasion Techniques

CAPTCHA Bypass

AkiraBot puts significant emphasis on evading CAPTCHAs so that it can spam websites at scale. The targeted CAPTCHA services include hCAPTCHA and reCAPTCHA, including Cloudflare’s hCAPTCHA service in certain versions of the tool.

We identified an archive with files for CAPTCHA-related servers and browser fingerprints, which allow the bot’s web traffic to mimic a legitimate end user. The archives contain a fingerprint server that runs on the same system as the other AkiraBot tools and intercepts the website loading processes using Selenium WebDriver, an automation framework that simulates user browsing activity.

The inject.js script injects code into the targeted website’s Document Object Model (DOM) which enables the tool to modify how the website loads in real time and change behaviors. inject.js manipulates values in the session via a headless Chrome instance that makes the session appear like an end user’s browser to the webserver. The script modifies multiple browser attributes that webservers use to identify the nature of the browser viewing the website, including:

  • Audio Context and Voice engines, which are used to profile whether a session is headless or a real browser
  • Graphics rendering, including canvas and WebGL attributes
  • Installed fonts
  • Navigator objects, which provide a wealth of profiling information, such as browser type, operating system & architecture, geolocation, hardware details, languages installed, and browser privacy settings
  • System memory, storage, and CPU profile
  • Timezone

The bot uses several CAPTCHA bypassing services, including Capsolver, FastCaptcha, and NextCaptcha, which are failover services for when browser emulation is insufficient to interact with the targeted website.

FastCaptcha token generator function in v10.py

AkiraBot also runs a headless Chrome instance to refresh values for Reamaze tokens periodically. Reamaze provides websites with customer support chat integrations, making this another targeted feature. The service also offers spam filters for chats on its platform, indicating that this is a known vector for spam attacks.

Reamaze token handling function

Network Evasion Techniques

AkiraBot uses many different proxy hosts to evade network detections and diversify the source of where its traffic comes from. In each archive SentinelLABS analyzed, AkiraBot used the SmartProxy service. SmartProxy’s website claims that its proxies are ethically sourced and that they provide data center, mobile, and residential proxies. Each version of the bot uses the same proxy credentials, suggesting the same actor is behind each iteration.

get_random_proxy function in The_NextCaptcha_Bot.py

While SmartProxy is a service that seems to operate within legal boundaries, it is worth noting that it has regularly had the attention of cybercriminals. The BlackBasta ransomware leaks referenced an exchange of SmartProxy credentials, for example.

SmartProxy credentials from BlackBasta leaks

Logging & Success

AkiraBot logs its spam progress to submissions.csv, which sometimes includes the AI-generated spam message contents as well. The submissions.csv file from the January 2025 archives show more than 80,000 unique domains that were successfully spammed. The script also logs failed attempts in failed.txt and failed_old.txt. The January 2025 archives showed that only 11,000 domains had failed, including previous runs of the tool. We analyzed all submissions.csv files; deduplicating the results revealed that more than 420,000 unique domains were targeted in total.

Two versions of AkiraBot used a Telegram bot for logging success metrics. The scripts monitor.py and monitor_random.py would collect success metrics from the bot and post them to a Telegram channel via API.

Telegram sending functionality in monitor.py

Telegram Detail

The Telegram functionality, contained in the monitor.py and monitor_random.py scripts, is tied into proxy rotation and CAPTCHA defeat features contained within the bundled JavaScript file script.js.  The monitor.py script utilizes pyautogui to paste the contents of script.js into a browser developer console by scripting CTRL+SHIFT+J, followed by the paste command, eventually executing the JavaScript within the browser console.

pyautogui actions in monitor.py

The pasted and executed JavaScript is then responsible for attempting CAPTCHA refreshes and defeats on targeted URLs, reporting the status returned to a JSON file, stats.json. If a proxy rotation is required, to aid further in refreshing the CAPTCHA defeat attempts on a given URL, the monitor.py script handles this as well, rotating the used proxy though the iproxyonline service (fxdx[.]in).

Proxy rotation is generally enabled to avoid geographic or IP-based restrictions when repeatedly attempting to refresh and defeat CAPTCHAs. The Telegram status updates specifically report on proxy rotations and CAPTCHA submissions. Some versions of these scripts have the proxy rotation section commented out, indicating that it is an optional feature.

Telegram message submission + proxy rotation status in monitor.py

All of the analyzed monitor.py and monitor_random.py scripts contain the same Telegram token and chat_id combination.

 Telegram bot data in monitor.py
Telegram bot data in monitor.py

This Telegram chat_id is associated with the following Telegram user data:

(bot) username: htscasdasdadwoobot
Firstname: Shadow / hts
LastName: a_zarkawi
HTS Telegram bot referenced in monitor.py scripts

Infrastructure

The spam messages frequently rotate the domain used, likely in an attempt to avoid detection. The oldest domain in use is akirateam[.]com, which was registered in January 2022 on a Germany-based IP, 91.195.240[.]94, without further updates until March 2023. The second oldest domain is goservicewrap[.]com, which was registered in April 2024 and resolved to 86.38.202[.]110, a Hostinger IP in Cyprus.

Several AkiraBot domains have interesting connections through historical DNS activity. The subdomain mail.servicewrap-go[.]com briefly shared a CNAME record pointing to 77980.bodis[.]com, which is associated with various malicious activities, including a 2023 malvertising campaign. This domain also received communications from several Windows executable files that were detected as various banking trojans.

An odd relationship stood out in anchor links referencing 77980.bodis[.]com: the website unj[.]digital contained anchor links from December 2024 through February 2025 pointing to 77980.bodis[.]com. UNJ Digital’s website describes itself as a digital marketing and software development firm. The subdomain smtp.unj[.]digital also has a CNAME record pointing to 77980.bodis[.]com, fortifying a connection between these hosts. While the website now highlights offering digital content services, as of late 2024 the site showed a focus on increasing marketing revenue.

Screenshot of content on unj[.]digital circa October 2024
Screenshot of content on unj[.]digital circa March 2025

Akira and ServiceWrap SEO

AkiraBot uses two distinct themes in their SEO offering domain naming conventions: Akira and ServiceWrap. Reviews for both services on TrustPilot are similar: many 5-star reviews with similar, potentially AI-generated contents, and the occasional 1-star review complaining that the site is either a scam or has spammed the person leaving the review.

The 5-star reviews tend to follow a pattern where the reviewer has one previous review that was made 1-5 days before the Akira or ServiceWrap review. The review themes are very similar across these 5-star reviews, though the contents and structure are always unique. We believe the actor may be generating some fake reviews, though it is difficult to say with certainty.

Trustpilot review for servicewrapgo[.]com

Trustpilot review for useakira[.]com

Trustpilot review for useakira[.]com

Conclusion

AkiraBot is a sprawling framework that has undergone multiple iterations to integrate new spamming target technologies and evade website defenses. We expect this campaign to continue to evolve as website hosting providers adapt defenses to deter spam. The author or authors have invested significant effort in this bot’s ability to bypass commonly used CAPTCHA technologies, which demonstrates that the operators are motivated to violate service provider protections.

AkiraBot’s use of LLM-generated spam message content demonstrates the emerging challenges that AI poses to defending websites against spam attacks. The easiest indicators to block are the rotating set of domains used to sell the Akira and ServiceWrap SEO offerings, as there is no longer a consistent approach in the spam message contents as there were with previous campaigns selling the services of these firms.

SentinelLABS thanks the OpenAI security team for their collaboration and continued efforts in deterring bad actors from abusing their services. The OpenAI team shared the following response following their investigation:

“We’re grateful to SentinelOne for sharing their research. Distributing output from our services for spam is against our policies. The API key involved is disabled, and we’re continuing to investigate and will disable any associated assets. We take misuse seriously and are continually improving our systems to detect abuse.”

Indicators of Compromise

Akira & ServiceWrap Domains
akirateam[.]com
beservicewrap[.]pro
firstpageprofs[.]com
getkira[.]info
go-servicewrap[.]com
gogoservicewrap[.]com
goservicewrap[.]com
joinnowkira[.]org
joinnowservicewraps[.]pro
joinservicewrap[.]com
joinuseakira[.]com
kiraone[.]info
letsgetcustomers[.]com
loveservice-wrap[.]com
mybkira[.]info
onlyforyoursite[.]com
searchengineboosters[.]com
service-wrap[.]com
servicewrap-go[.]com
servicewrap[.]pro
servicewrapgo[.]com
servicewrapone[.]com
theakirateam[.]com
toakira[.]pro
topservice-wrap[.]pro
topservicewrap[.]com
usekiara[.]com
useproakira[.]com
usethatakira[.]com
wantkiara[.]info
wearetherealpros[.]com
wejoinkir[.]vip
wethekira[.]shop
wetheservicewrap[.]pro

AkiraBot Tool Archive SHA-1
09ec44b6d3555a0397142b4308825483b479bf5a
0de065d58b367ffb28ce53bc1dc023f95a6d0b89
13de9fcd4e7c36d32594924975b7ef2b91614556
2322964ea57312747ae9d1e918811201a0c86e9c
253684ea43cb0456a6fec5728e1091ff8fcb27cf
36b4e424ce8082d7606bb9f677f97c0f594f254d
3a443c72995254400da30fe203f3fbf287629969
3a7cc815b921166006f31c1065dadfeb8d5190e6
4d24dd5c166fa471554ed781180e353e6b9642b7
51ec20e5356bbebd43c03faae56fca4c3bbe318e
55affc664472c4657c8534e0508636394eac8828
5620b527dfc71e2ee7efb2e22a0441b60fd67b84
5fde3180373c420cfa5cfdea7f227a1e1fe6936c
62e66bae4b892593009d5261d898356b6d0be3ef
6b65c296d9e1cda5af2f7dab94ce8e163b2a4ca8
6c56b986893dd1de83151510f4b6260613c5fbb9
6f342ff77cd43921210d144a403b8abb1e541a8b
7129194c63ae262c814da8045879aed7a037f196
71464c4f145c9a43ade999d385a9260aabcbf66d
730192b0f62e37d4d57bae9ff14ec8671fbf051e
769aa6ab69154ca87ccba0535e0180a985c21a0c
76aab3ab0f3f16cf30d7913ff767f67a116ff1e7
853fde052316be7887474996538b31f6ac0c3963
9d43494c6f87414c67533cce5ec86754311631fc
9f6ed2427e959e92eb1699024f457d87fa7b5279
aa72065673dc543e6bf627c7479bfe8a5e42a9c4
aac26242f4209bc59c82c8f223fcf2f152ce44bc
b643a1f2c4eb436db26763d5e2527f6bebe8bcbf
bbd754e36aee4702b9f20b90d509248945add4ea
cb194612ed003eaf8d8cf6ed3731f21f3edeb161
cc63ee921c29f47612096c34d6ee3ef244b33db2
e12c6911997d7c2af5550b7e989f1dc57b6733b8
eae675812c4274502051d6f2d36348f77a8464a0
f1c7c5d0870fd0abb7e419f2c2ba8df42fa74667
f2e71c9cbc4a18482a11ca3f54f2c958973360b4
fb7fdcc2fe11e95065a0ce9041348984427ca0f4

❌