❌

Visualização de leitura

Atividade: O que é OSINT (open source intelligence}


Rogério Souza é um Expert na plataforma Criminal Player, especializado em investigação digital, OSINT (Inteligência de Fontes Abertas) e investigação defensiva para advogados criminalistas. 


Seus principais conteúdos e atuações incluem:

  • Aulas sobre Investigação Digital: Aborda a recuperação de dados, análise de metadados (usando ferramentas como GeoSetter e ExifTool) e esteganografia para extração de informações forenses em imagens e documentos. 

  • OSINT no Processo Penal: Discute o uso de fontes abertas para localização de indivíduos e análise de dados, em colaboração com o advogado Alexandre Morais da Rosa, focando nas vulnerabilidades da internet e implicações legais. 

  • Participação em Podcast: Foi entrevistado no Criminal Player Podcast #319, junto com Eduardo Moura e Alexandre Morais da Rosa, discutindo a importância da prova digital na defesa criminal e técnicas de contranarração. 

  • Perfil Profissional: Descrito como autodidata com experiência em monitoramento de redes sociais, análise de vínculos na internet e varredura em ambientes computacionais, atuando como suporte na produção de provas para a advocacia criminal. 


Acesse o APP

https://criminalplayer.com.br/rogerio-souza/

What behavioral data reveals about AI value

Taylor Paletta was glancing at two versions of the same customer-service interaction on her monitor. As director of support and digital success at the enterprise software company, Ninety, she could read the support chat in one window while watching the customer’s product session in another. The customer had already spent several minutes trying to solve the problem, including twice attempting the sequence the AI agent would eventually recommend.

The chat transcript alone looked reasonably positive and successful. The customer asked a question, the AI agent responded promptly and the case appeared to move toward resolution. Yet the session recording spun a different story altogether. The customer was being asked to retrace steps that had already failed, while the AI agent had no awareness of what they had done before opening the support widget. Both records contained accurate data; however, only the behavioral record explained the customer’s actual experience.

Paletta’s team addressed this apparent systemic issue by feeding behavioral session summaries into their customer support AI agent before the conversation begins, not after. The AI agent can now see what the customer did inside the product, where the process broke down and which steps have already failed. Moreover, when the interaction escalates, the human agent inherits the same context rather than reconstructing the story from scratch. Tickets with that behavioral context now resolve at 79%, six points higher than tickets without it.

A six-point improvement may not sound dramatic, yet it is a real gain tied to a specific change in how the work gets done, resulting in real revenue. Additionally, and perhaps more importantly, it illustrates a measurement challenge well beyond customer support. That is, many organizations know how much AI they have deployed, but they have far less visibility into whether AI changed the work or improved the outcome.

Indeed, MIT researchers examining U.S. enterprise AI deployments reported roughly $35 billion to $40 billion committed, while 95% of organizations reported no measurable return. The problem is that companies tend to measure what their systems make easy to count — licenses, logins, prompts, sessions and features activated. Then they use those measures as questionable proxies for value, not realizing or acknowledging that activity actually may be inversely related to value.

Customer service activity is not value

Customer service, as much as any business function, makes activity-versus-value distinction especially lucid. Common customer support AI applications don’t capture behavioral data and therefore can create more effort for customers and agents when issues are escalated. Applications informed by behavioral data, however, may produce fewer interactions precisely because they resolve more issues correctly the first time. Therefore, prompt volume or time in the application can be ambiguous measures. Sometimes, more customer interaction indicates more friction rather than more value.

This suggests distinguishing between different types of behavioral signals that show AI is merely available or being used versus signals that show work is actually changing:

  1. Provisioning signals include seats purchased, licenses assigned and accounts activated, which tell you what the organization made available.
  2. Engagement signals include logins, sessions, prompts and time in the application, which tell you that activity occurred. Both are useful operational measures; nonetheless, they offer limited evidence about whether the service improved.
  3. Displacement signals go further by showing which human steps disappeared, which handoffs were eliminated and whether AI output survives into the finished work.
  4. Friction signals capture rework, repeat attempts, abandonment, escalation, rage clicking and silent workarounds.

Displacement and friction-related measures are particularly aligned with economic value because they reveal what changed in the process and what the customer (or employee) had to do differently as a result.

At Ninety, for example, AI-generated session summaries now arrive inside the agent’s ticketing workflow. Previously, an agent handling a difficult case might open another application, scrub through a session replay, locate the point of failure and then reconstruct the story while the customer waited. With behavioral context already attached to the ticket, much of that work can disappear. Consequently, the organization can measure fewer applications opened, fewer handoffs, shorter resolution paths and less manual reconstruction rather than merely reporting that an AI feature was used.

Behavioral data changes the conversation, literally

Behavioral data does more than make the AI more efficient; it changes what the AI knows about the customer at the moment a decision has to be made. In service, this becomes important because a correct answer can still produce a poor experience when it arrives without context. Paletta’s team, for instance, found that some customers tired of AI conversations even when the answers were technically accurate, but the interaction felt cold, repetitive or unnecessarily difficult.

“Traditional adoption metrics have little to say about that kind of problem,” says Scott Voigt, co-founder and CEO of Fullstory. “Behavioral signals, however, can reveal repeated attempts, hesitation, abandonment, rage clicking or a pattern of moving back and forth through the same workflow.”

These types of signals can then trigger a different response, including routing the customer to a person before frustration compounds. In other words, behavioral data becomes part of the service logic rather than merely another source for retrospective reporting.

Paletta describes some of these branching experiences as a “choose your own quest” model, in which observed behavior influences the next path, and AI handles the decision until human intervention becomes appropriate. Furthermore, because the path is based on what customers actually do rather than what designers assumed they would do, the organization can refine the experience continuously as new patterns appear.

Measuring the work, not the worker

There is, however, an important governance issue. Once executives realize that conventional AI metrics reveal too little, the reflex may be to monitor individuals more closely. That approach can easily distort the very behavior the organization is trying to understand, since employees who feel personally tracked and scored may experiment less openly, conceal failed attempts or move work into channels that are harder to observe.

A more useful unit of analysis is generally not the employee but the work: the workflow, journey, handoff or decision.  Instead of asking how many prompts a particular support agent entered, ask where agents still have to reconstruct context manually, which cases require repeated escalation, where AI output routinely needs correction, and whether someone’s effort is rising or falling. Similarly, rather than judging people by an isolated session, look for aggregate patterns showing where people overall stall, repeat themselves, abandon a path or seek human help.

Moreover, this approach tends to produce better data because the purpose of the instrumentation is easier to defend. Instrumentation intended to improve a process is fundamentally different from instrumentation used to grade an employee; once people begin optimizing their behavior for the score, the measurement itself corrupts the signal. The former can reveal where the service design is failing; the latter may encourage people to change their behavior simply to “game the system.”

Starting the customer support journey before they do

One of Paletta’s more interesting measures extends the same thinking beyond Ninety’s own support environment. Customers now frequently consult public AI models before they visit a company’s support site. Consequently, an external system the company does not control may already be functioning as an informal first layer of customer service, interpreting company content and shaping the customer’s expectations before a formal support interaction begins.

So, the Ninety team compiled the company’s help center and blog content into JSON, tested how frontier models such as ChatGPT and Gemini alone answer questions about the product, and built a scoring system for answer quality. The scoring system helps the team identify where Ninety’s source material produces weak answers so they can improve the underlying content.

This expansion of what behavioral data includes not only what users do inside the sanctioned AI application, but also the observable choices they make around it, e.g., whether they abandon one channel for another, whether they repeatedly seek clarification, whether they bypass an AI agent and whether they arrive at support after already trying to solve the problem elsewhere. Indeed, those behaviors often reveal dissatisfaction or disengagement earlier than a survey, complaint or renewal discussion.

The business case for behavioral data

Return, then, to the customer who had already tried the same troubleshooting sequence twice. The support transcript could reasonably have been counted as a successful AI interaction, and a conventional customer service analysis dashboard might have added another prompt, another active user and another resolved conversation to its totals. Yet those measures would still have missed the fact that the customer was repeating failed work because the AI lacked behavioral context.

The customer who had already attempted the same troubleshooting sequence twice could easily have registered as an AI success: another active user, another prompt, another conversation apparently resolved. Yet almost every conventional measure would have missed the part that mattered — the customer was doing unnecessary work because the AI lacked the context to know better.

Behavioral data connects what the AI did to what happened around it, what the customer had already attempted, what the employee no longer had to do, where friction disappeared or compounded, and whether the process itself improved. For CIOs trying to establish the business value of AI, behavioral data answers “What happens better, faster, different or not at all because of AI?” rather than simply “How much are people using AI?”

Os usuários podem monitorar outras pessoas em tempo real para fins logísticos ou de segurança

CCTV: como uma ferramenta de código aberto expôs a localização de usuários do Telegram | OSINT Brasil RDS Consultoria / OSINT Brasil">

$  

OSINT · Privacidade Digital · Contrainteligência

CCTV: a ferramenta de código aberto que transformou o Telegram em um mapa de rastreamento em tempo real

Como o recurso "Pessoas Próximas" virou vetor de geolocalização, o que a repercussão global do caso ensina sobre exposição digital, e o que diz a lei brasileira sobre esse tipo de monitoramento.

Análise Analítico de Dados · OSINT Brasil ·
"Quem não controla a informação, vira alvo dela." — Rogério Souza

O que foi o caso CCTV

Em 2024, um projeto de código aberto batizado Close-Circuit Telegram Vision (CCTV) ganhou notoriedade internacional por demonstrar, na prática, uma fragilidade conceitual em um recurso que milhões de pessoas usam sem pensar duas vezes: o "Pessoas Próximas" do Telegram, criado originalmente para sugerir contatos e canais locais.

A ferramenta automatizava um processo que, isoladamente, qualquer usuário do Telegram poderia repetir manualmente: consultar a distância aproximada informada pelo aplicativo entre a conta que faz a busca e outras contas próximas. Ao repetir essa consulta a partir de múltiplos pontos simulados, era possível aplicar um raciocínio de trilateração — a mesma lógica geométrica usada por GPS e por técnicas clássicas de GEOINT — para convergir sobre a localização real de um alvo, com precisão relatada na faixa de 50 a 100 metros.

Ponto de virada: em 6 de setembro de 2024, o Telegram desativou o recurso "Pessoas Próximas" em nível de plataforma. Isso encerrou de forma definitiva o funcionamento de todas as ferramentas construídas sobre esse vetor, incluindo o CCTV. O caso ilustra um padrão recorrente em OSINT: recursos de conveniência de UX frequentemente carregam superfícies de exposição que só se tornam visíveis quando alguém as instrumentaliza publicamente.

Por que o caso repercutiu tanto

A cobertura do caso não ficou restrita a um nicho técnico. Veículos e comunidades de segurança em pelo menos quatro idiomas noticiaram o tema — da imprensa especializada em tecnologia à imprensa investigativa russa, passando por publicações de segurança na Itália e na Espanha. O padrão de repercussão é um indicador clássico de que a ferramenta tocou em uma preocupação real e generalizada: a sensação de que aplicativos de mensageria, mesmo os que se posicionam como focados em privacidade, podem carregar funcionalidades cujo risco não é comunicado com clareza ao usuário final.

Do ponto de vista de quem trabalha com Threat Intelligence e investigação digital defensiva, o episódio é um estudo de caso relevante sobre três frentes que se cruzam:

  • Superfície de exposição por design — recursos pensados para conveniência (encontrar pessoas/canais perto de você) podem ser reaproveitados como primitivas de rastreamento quando automatizados em escala.
  • Assimetria entre usuário comum e agente malicioso — a maioria dos usuários não tem ideia de que uma funcionalidade de "descoberta local" pode ser convertida em ferramenta de perseguição (stalking) por qualquer pessoa com conhecimento básico de scripting.
  • Velocidade de resposta da plataforma — o desligamento do recurso, embora tardio em relação à circulação pública da ferramenta, mostra que pressão pública e cobertura de imprensa continuam sendo um dos poucos mecanismos efetivos de correção rápida quando não há regulação específica em tempo real.

A lógica técnica, em nível conceitual

Sem reproduzir instruções operacionais — o que não é o objetivo deste artigo nem de qualquer conteúdo produzido pela OSINT Brasil —, vale entender a lógica subjacente para fins de conscientização defensiva:

  1. O aplicativo informa uma distância aproximada entre duas contas quando ambas têm o recurso de descoberta local ativo.
  2. Repetindo essa consulta a partir de coordenadas de referência diferentes (um processo de deslocamento simulado), obtêm-se múltiplos "raios" de distância até o mesmo alvo.
  3. A interseção geométrica desses raios — o mesmo princípio usado por sistemas de posicionamento por satélite — converge para uma área cada vez menor, até aproximar a localização real com margem de dezenas de metros.

Essa lógica não é exclusiva do Telegram. Qualquer serviço que exponha "distância até outro usuário" sem limitar a granularidade, a frequência de consulta ou o comportamento automatizado (via API) está sujeito ao mesmo tipo de abuso. É por isso que, em auditorias de exposição digital, um dos pontos de verificação padrão da metodologia OSINT Brasil é justamente mapear quais aplicativos do cliente expõem, mesmo que de forma aproximada, sinais de proximidade geográfica.

Enquadramento jurídico no Brasil

Ferramentas com essa finalidade — rastrear a localização de uma pessoa sem consentimento, para fins de monitoramento, controle ou vigilância — esbarram em pelo menos três frentes do ordenamento jurídico brasileiro:

Lei do Stalking (Lei nº 14.132/2021)

Incluiu no Código Penal o crime de perseguição (art. 147-A), que criminaliza perseguir alguém reiteradamente, por qualquer meio, ameaçando sua integridade física ou psicológica, restringindo sua capacidade de locomoção ou, de qualquer forma, invadindo ou perturbando sua esfera de liberdade ou privacidade. O uso de uma ferramenta de geolocalização não consentida para monitorar deslocamentos de uma pessoa se encaixa diretamente nesse tipo penal quando há reiteração e finalidade de vigilância.

LGPD (Lei nº 13.709/2018)

Dados de geolocalização são dados pessoais e, dependendo do contexto (por exemplo, quando revelam rotina, endereço residencial ou deslocamentos que permitem inferir características sensíveis), podem se aproximar do regime mais rigoroso do art. 11. O tratamento sem base legal — e monitoramento oculto de terceiros certamente não se enquadra nas hipóteses do art. 7º — configura ilícito civil, sujeito a indenização por danos morais e, no caso de agentes de tratamento formais, a sanções administrativas da ANPD.

Marco Civil da Internet (Lei nº 12.965/2014)

Reforça a proteção à privacidade e à intimidade como princípios da disciplina do uso da internet no Brasil (art. 3º, incisos II e III), servindo de base complementar em ações que discutam responsabilidade de provedores de aplicação diante de vazamentos de funcionalidade que facilitem rastreamento não consentido.

Nota sobre jurisprudência recente: tribunais superiores brasileiros vêm consolidando, ao longo de 2025 e 2026, o entendimento de que o tratamento de dados pessoais sem base legal adequada gera dever de indenizar quando há exposição concreta de intimidade — e o STJ tem atuado para uniformizar decisões sobre compartilhamento indevido de dados pessoais, inclusive sob o CPC (arts. 927 e 1.036), buscando reduzir divergências entre tribunais de segunda instância. Na esfera criminal, o STF já assentou que provas obtidas a partir de dados de geolocalização ou conteúdo telemático sem autorização judicial são nulas em investigações penais — precedente que reforça, por analogia, a ilicitude de qualquer coleta de localização à margem do devido processo.

Lições defensivas: como reduzir sua superfície de exposição

Vetor de riscoAção recomendada
Recursos de "descoberta por proximidade"Desative funcionalidades de geolocalização social sempre que não forem estritamente necessárias.
Compartilhamento de localização em tempo realRestrinja a contatos específicos e por tempo limitado, nunca de forma permanente.
Metadados em fotos e storiesRemova metadados de GPS antes de publicar (revisão EXIF), especialmente em conteúdo próximo à residência ou local de trabalho.
Apps de terceiros com permissão de localizaçãoAudite periodicamente quais aplicativos têm acesso contínuo (não apenas "durante o uso").
Padrões de rotina expostos publicamenteEvite postar em tempo real; publique com atraso quando o conteúdo revelar padrões de deslocamento previsíveis.

Cenários prospectivos

O desligamento do recurso pelo Telegram resolve o vetor específico do CCTV, mas não elimina o problema estrutural. Alguns cenários prováveis para os próximos ciclos:

  • Migração do vetor para outras plataformas — qualquer aplicativo que ainda exponha distância aproximada entre usuários (redes de namoro, apps de encontros, redes sociais de nicho) permanece candidato a réplicas conceituais da mesma técnica.
  • Pressão regulatória crescente — a tendência, tanto na União Europeia (DSA/GDPR) quanto no Brasil (agenda da ANPD), é de exigir de plataformas testes de "privacy by design" mais rigorosos antes do lançamento de recursos sociais baseados em proximidade.
  • Judicialização de casos concretos — é razoável esperar um aumento de ações envolvendo a Lei do Stalking combinadas a pedidos de indenização sob a LGPD, à medida que vítimas de monitoramento digital não consentido buscam reparação civil e criminal simultaneamente.
  • Uso em due diligence e investigação defensiva — o caso já se consolidou como referência didática em treinamentos de OSINT e threat intelligence, justamente pelo caráter reproduzível do princípio geométrico por trás da técnica.

Conclusão

O caso CCTV não foi apenas sobre uma ferramenta específica — foi sobre como um detalhe aparentemente inofensivo de design de produto pode se transformar em vetor de vigilância em escala quando cai nas mãos certas (ou erradas). Para profissionais de segurança da informação, investigação digital e compliance, o episódio reforça uma regra permanente: toda funcionalidade que revela proximidade, distância ou presença de um usuário é, por definição, uma funcionalidade de geolocalização — e deve ser tratada com o mesmo rigor jurídico e técnico que qualquer outro dado sensível.

Conteúdo produzido pela OSINT Brasil para fins de conscientização em segurança da informação e investigação digital defensiva. Este artigo não reproduz nem incentiva o uso de ferramentas de rastreamento não consentido de pessoas, prática que pode configurar crime de perseguição (art. 147-A do Código Penal) e ilícito civil sob a LGPD.

Stone, parchment or laser-written glass? Scientists find new way to preserve data

Hard disks and magnetic tape have a limited lifespan, but glass storage developed by Microsoft could last millennia

Some cultures used stone, others used parchment. Some even, for a time, used floppy disks. Now scientists have come up with a new way to keep archived data safe that, they say, could endure for millennia: laser-writing in glass.

From personal photos that are kept for a lifetime to business documents, medical information, data for scientific research, national records and heritage data, there is no shortage of information that needs to be preserved for very long periods of time.

Continue reading...

© Photograph: Tetra Images/Erik Isakson/Getty Images

© Photograph: Tetra Images/Erik Isakson/Getty Images

© Photograph: Tetra Images/Erik Isakson/Getty Images

A biological 0-day? Threat-screening tools may miss AI-designed proteins.

On Thursday, a team of researchers led by Microsoft announced that they had discovered, and possibly patched, what they're terming a biological zero-day—an unrecognized security hole in a system that protects us from biological threats. The system at risk screens purchases of DNA sequences to determine when someone's ordering DNA that encodes a toxin or dangerous virus. But, the researchers argue, it has become increasingly vulnerable to missing a new threat: AI-designed toxins.

How big of a threat is this? To understand, you have to know a bit more about both existing biosurveillance programs and the capabilities of AI-designed proteins.

Catching the bad ones

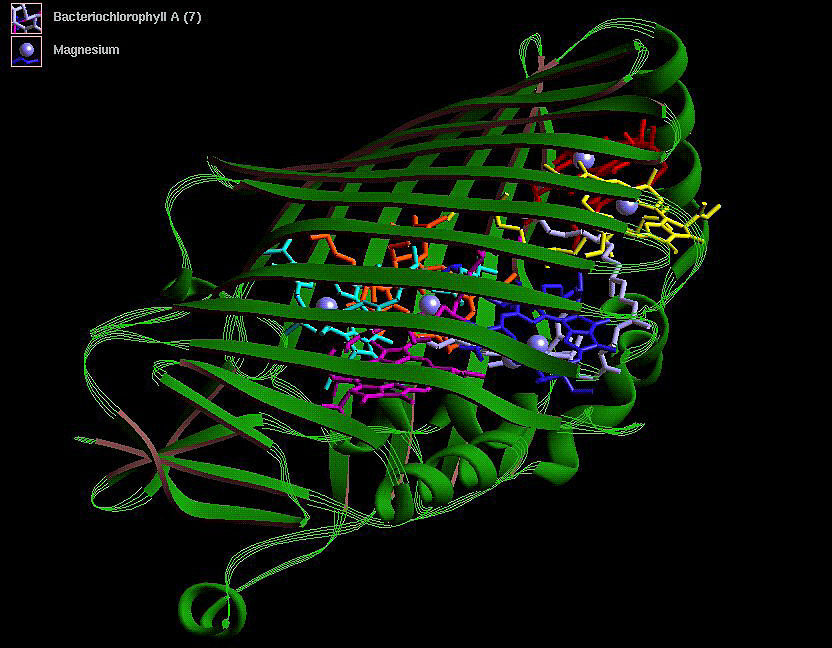
Biological threats come in a variety of forms. Some are pathogens, such as viruses and bacteria. Others are protein-based toxins, like the ricin that was sent to the White House in 2003. Still others are chemical toxins that are produced through enzymatic reactions, like the molecules associated with red tide. All of them get their start through the same fundamental biological process: DNA is transcribed into RNA, which is then used to make proteins.

Read full article

Comments

© Historical / Contributor

❌