A Oracle publicou sua Atualização Crítica de Patch (CPU) de outubro de 2026, com 1.295 novas correções em dezenas de produtos. Segundo análise da Tenable, a atualização aborda 1.209 CVEs únicos, incluindo 95 falhas de severidade crítica. A Tenable informa que 439 CVEs foram classificados como alta severidade e 582 como média. O Oracle Fusion […]
A Cisco anunciou na quarta-feira (21) correções para 34 vulnerabilidades que afetam as linhas Expressway Series, IOS XR, Snort 3 e produtos de Unified Communications. Entre as falhas estão defeitos críticos que podem levar à execução de comandos, ao bypass de autenticação e a ataques de XSS. A empresa afirmou não ter conhecimento de exploração […]
O Node.js lançou atualizações de segurança para as ramificações 26.x, 24.x e 22.x com o objetivo de corrigir dez vulnerabilidades, incluindo quatro falhas de alta severidade que afetam consultas DNS, verificações de certificados TLS e descompressão Brotli. As versões corrigidas são 26.12.1, 24.22.1 e 22.23.4, segundo os detalhes de lançamento. O desfecho mais grave possível […]
A equipe de segurança do PHP alertou administradores a se prepararem para atualizações de segurança emergenciais nesta quarta-feira (21) para corrigir duas vulnerabilidades críticas, após informações sobre as falhas terem vazado antes da divulgação programada. Em comunicado publicado nesta terça-feira (20), o time de desenvolvimento do PHP informou que pretende liberar as correções às 14h […]
A BeyondTrust alertou clientes na quinta-feira, 15 de outubro de 2026, para corrigirem uma falha crítica no Remote Support (RS) explorada em ataques zero-day desde o fim de agosto. O produto é a solução corporativa de suporte remoto da empresa, usada por service desks de TI e equipes de atendimento ao cliente para solucionar problemas […]
Uma nova versão do Curl foi publicada com a correção de mais de vinte vulnerabilidades, incluindo uma falha de execução remota de código (RCE) encontrada pela empresa de inteligência artificial Anthropic. Apesar de permitir execução remota de código, o impacto da CVE-2026-92392 foi classificado como “alto”, e não crítico. Segundo o mantenedor do Curl, Daniel […]
I’ve spent more than 20 years running IT and security for organizations across California and around the country. Over that time, my team has taken over, deployed and cleaned up Microsoft 365 environments for law firms, commercial real estate companies, manufacturers, healthcare practices and schools. We’ve supported more than 7,500 users along the way.
After working with that many tenants, the biggest takeaway is simple: most Microsoft 365 security problems aren’t especially sophisticated. Usually, a control was never turned on, only covered part of the organization, or somebody made an exception years ago to keep something working and it was never revisited. Microsoft gives organizations a lot to work with. More often than not, the problem is how the environment was configured and maintained, not a lack of security tools.
These are the issues we run into most often and the areas I’d look at first.
Most environments are still running on their original settings
When we first assess a tenant, we often find that nobody has really gone back through the security settings since it was originally set up. MFA may cover some users but not everybody. Legacy authentication is still allowed. There are too many global administrators. Nobody is quite sure when audit logging was last reviewed.
Last year we took over a 45-person medical practice that had been on Microsoft 365 for almost a decade. We found nine global administrator accounts, including two belonging to employees who had left years earlier. MFA was enabled, but only for the physicians. The front desk and billing staff, who handled the most patient data, had none.
Usually, nobody intentionally ignored security. The company grew, email kept working, people got busy and the original setup stayed in place. We see this constantly. Something working every day doesn’t necessarily mean it is configured the way you would want it configured today.
For a smaller organization without dedicated identity management, Microsoft’s security defaults are a good place to start. They require MFA and block legacy authentication without adding another license. As the environment gets more complex, and assuming the licensing supports it, conditional access gives you much more control over who can sign in, from where and from what device.
MFA is the starting point, not the finish line
At this point, most business leaders know MFA needs to be enabled. What still gets missed is the idea that turning it on somehow finishes the job.
Attackers have adjusted to MFA. Push fatigue attacks still work because eventually somebody may approve a prompt just to make it stop. Adversary-in-the-middle phishing kits can steal a live session token and get around standard MFA altogether. OAuth consent phishing is another issue: a user can be tricked into approving a malicious application through what looks like a legitimate Microsoft or Google consent screen. At that point, changing the user’s password may not even remove the access.
A few months ago, a paralegal at a law firm we support clicked what looked like a shared document from opposing counsel and signed in through a convincing Microsoft login page. She had MFA and completed the prompt, but the page was relaying her session in real time. Within minutes the attacker was in her mailbox from overseas. We caught it through an impossible-travel alert, revoked the session and reset the account before any client data left.
There are a handful of things we normally tighten up here. Use number matching in the authenticator app. Put administrators and other high-risk users on phishing-resistant methods such as FIDO2 keys or passkeys. Don’t let users approve any third-party application they want. And where licensing allows it, use conditional access so a password or stolen session by itself isn’t enough to get into the environment.
Legacy authentication remains the open side door
This one still surprises a lot of executives. They know MFA is enabled and assume that means every sign-in is protected. That isn’t always the case. Legacy protocols such as POP, IMAP and older SMTP connections don’t support MFA, which can leave a path around the control.
Microsoft has retired a lot of legacy authentication already, but we still come across exceptions that were left in place for an old scanner, a line-of-business application or sometimes one user’s device. Find out what actually still needs it, fix or replace that dependency, and close the exception. We have seen organizations leave a security hole open for years because of one multifunction printer.
Licensing determines what security is actually available
Licensing is another area that causes a surprising amount of confusion. Two plans can sound almost identical while giving the IT team very different security capabilities. Office 365 E3 and Microsoft 365 E3 are a good example: Microsoft 365 E3 includes Intune device management and Entra ID P1 conditional access, while Office 365 E3 does not.
We once had a healthcare client with a departing employee who kept a company laptop with patient records on it. Leadership assumed we could lock or wipe it remotely. We couldn’t. They were licensed for Office 365 E3, not Microsoft 365 E3, so the device had never been enrolled in Intune. We got the laptop back, but only after several uncomfortable days, and they upgraded their licensing the following week.
So before putting together a security roadmap, I would first confirm exactly what licenses are in place and what those licenses actually include. We’ve had more than one situation where leadership assumed a security capability was available simply because the Microsoft plan name sounded similar.
Email is still where most incidents begin
For us, email is still where a large percentage of incidents start. It may be a credential phishing page, a malicious link, or an inbox rule created after somebody has already gained access to the account.
Business email compromise is especially dangerous because the attacker often doesn’t do anything obvious right away. They get into a mailbox, create forwarding rules or hide replies, and wait. The goal may simply be to sit there until an invoice or wire transfer gives them an opportunity. According to the FBI’s Internet Crime Complaint Center, reported cybercrime losses reached $16.6 billion in 2024, and BEC continues to be one of the more expensive categories of fraud.
At one law firm, an attacker compromised a mailbox and created a rule that quietly moved any email containing “invoice” or “wire” into an unused folder. Two weeks later, a client received updated wiring instructions for a settlement payment from what looked like the firm’s own account. The client called to confirm before sending the funds, and that phone call is the only reason the money didn’t go out.
We normally put several controls around this. Block automatic forwarding to outside domains. Alert when inbox rules are created or changed. Most importantly, have an internal policy that any change to payment or wiring instructions gets confirmed verbally using a phone number you already know. That last one has nothing to do with cybersecurity software, but it can stop a very expensive mistake.
Privileged accounts need their own standard
The global administrator list should be short, intentional and documented. We also don’t want somebody using the same privileged account to read email and browse the web all day. It sounds basic, but we correct this all the time.
Use separate administrative accounts, put phishing-resistant MFA on them, and use just-in-time elevation where the licensing supports it. A compromised global administrator account gives an attacker an enormous amount of control, so we treat those accounts differently from a normal user.
Logging only helps if it’s configured before you need it
When something does happen, we immediately need to know what happened, when it started and what the attacker touched. If the right logging wasn’t enabled beforehand, or the retention period is too short, sometimes you simply can’t reconstruct the whole incident after the fact.
I’d much rather configure logging on day one and never use it than reconstruct an incident from partial data. CISA’s Secure Cloud Business Applications (SCuBA) baselines are an excellent, free reference for which settings to enable and how to verify them.
Where I would start
Microsoft 365 can be a very secure platform. In most environments we take over, the issue isn’t that Microsoft was missing some critical security feature. It’s usually a relatively short list of settings, permissions and exceptions that accumulated over time.
If I were reviewing an environment this quarter, these are the four things I would verify first:
Administrative access is minimal and protected with phishing-resistant MFA.
Legacy authentication is blocked.
MFA covers every user, and users can’t approve third-party apps unchecked.
You would have complete logs if something happened tomorrow.
Those four checks won’t solve every security problem, but they eliminate a lot of the issues we repeatedly find when we’re brought in to assess an environment or clean up after an incident.
type: Vulnerabilidade zero-day de execução remota de código explorada em ataques sector: Não informado initial_vector: Interface de gerenciamento do PAN-OS, com credenciais válidas e acesso de rede actor: Não informado exposed_data: Não informado records_count: Não informado incident_date: Não informado cve: CVE-2026-0322 keywords: PAN-OS, CVE-2026-0322, zero-day, firewall, Palo Alto Networks, execução remota de código A Palo […]
A Ivanti pediu a clientes nesta terça-feira que corrijam imediatamente uma vulnerabilidade zero-day explorada ativamente no gateway de acesso remoto Ivanti Connect Secure (ICS). Rastreada como CVE-2026-104935, a falha de bypass de autenticação de alta gravidade afeta as versões 22.8R2.4 e anteriores, 25.1.2.2 e anteriores, e 25.1.1.1 e anteriores, conforme comunicado da empresa. Segundo a […]
O GitLab informou nesta segunda-feira que corrigiu uma vulnerabilidade que poderia permitir a um atacante executar código remotamente em um servidor afetado. A falha de gravidade crítica, rastreada como CVE-2026-97229, decorreu da falha dos servidores GitLab Community Edition e Enterprise Edition em verificar a entrada do usuário quanto a texto malicioso, segundo o documento de […]
A Adobe publicou dez novos avisos de segurança para informar clientes sobre cerca de 140 vulnerabilidades encontradas e corrigidas em seus produtos. As falhas afetam aplicações como Commerce, Photoshop, ColdFusion, Substance 3D, Dimension, FrameMaker e Bridge, conforme os avisos publicados nesta terça-feira. As atualizações do Adobe ColdFusion tratam 32 vulnerabilidades, incluindo falhas críticas que podem […]
A SAP corrigiu 20 falhas de segurança em diversos produtos nas atualizações de outubro de 2026, incluindo uma vulnerabilidade de gravidade máxima no Cloud SDK para Python. Rastreada como CVE-2026-89111, a falha pode ser explorada por atacantes remotos sem privilégios para roubar credenciais, conforme comunicado da empresa publicado nesta terça-feira. O SDK Python da SAP […]
Celulares baratos e de marcas pouco conhecidas estão chegando a consumidores brasileiros e de outros países com malware embutido no firmware do sistema operacional Android (e portanto impossível de ser removido). Uma das possibilidades de uso do malware pelos seus controladores é utilizar o dispositivo em redes de bots para a venda de ataques DDoS […]
A inteligência artificial não reduziu o mercado de bug bounty no Brasil. Ampliou. É o que aponta levantamento da BugHunt, plataforma que acompanha mais de 27 mil hackers, segundo comunicado da empresa. Entre setembro de 2025 e setembro de 2026, o número de pesquisadores ativos, que enviaram ao menos um relatório de vulnerabilidade, cresceu 115% […]
O Google publicou na terça-feira uma atualização de segurança do Chrome 155 que corrige 247 vulnerabilidades, incluindo quatro falhas de gravidade crítica. Todas as quatro falhas críticas são problemas de use-after-free e afetam os componentes Chromecast, Browser, Navigation e Track do Chrome, registrados como CVE-2026-106382, CVE-2026-106197, CVE-2026-106358 e CVE-2026-106347. Uso de IA na descoberta de […]
A SonicWall publicou hotfixes para corrigir uma falha de falsificação de requisição do lado do servidor (SSRF) de gravidade máxima em appliances da série SMA1000. Registrada como CVE-2026-102255, a vulnerabilidade foi encontrada na interface Appliance WorkPlace dos modelos SMA1000 6210, 7210 e 8200v, mas não afeta a linha SMA 100 Series nem o SSL-VPN que […]
The US Federal Bureau of Investigation has removed an Accenture contractor working on its PeopleSoft installation over their role in a data breach that exposed personal details of FBI employees, Reuters reported Monday.
“To date, our review has determined that the incident occurred as the result of a security failure of a platform managed by a third-party organization — after a contractor failed to implement a security patch explicitly issued to secure the platform,” FBI Cyber Division Assistant Director Brett Leatherman told Reuters. “As such, the FBI has removed the contractor and taken all necessary steps to both mitigate any further risk and protect our workforce.”
Accenture was the third-party organization Leatherman would not identify, “two sources familiar with the matter” told Reuters.
As for the unnamed, unpatched platform, Reuters’ sources said that was Oracle PeopleSoft, the HR system that hacker group ShinyHunters claimed to have exploited in last month’s break-in.
Traditionally, preventing online fraud relied on point-in-time proof of identity: enter the correct password, complete a biometric verification, or pass a liveness check, and gain access. To defeat these controls, fraudsters had to steal credentials and other identity evidence from a real user, which was difficult to execute and scale. Today, widespread access to AI enables fraudsters to fabricate or imitate legitimate identities by combining exposed credentials with synthetic media designed to evade identity verification. Consequently, identity checks are no longer sufficient as they capture a moment in time. Even when someone passes a check, it does not mean the account itself can be trusted.
One convincing interaction can be faked. A consistent pattern of legitimate behavior is much harder to manufacture. Modern fraud prevention must move beyond stateless decisions toward a stateful trust model. Traditional identity verification asks, “Can this person pass the check right now?” A stateful approach additionally asks, “Does it fit what we know about this account and its established behavior?” At Cloudflare, trust is continually earned and reassessed at each interaction against historical behavioral, network, and device patterns.
Cloudflare’s Account Abuse Protection (AAP) creates stateful account overviews to help website owners detect and investigate abuse across login and signup activity. Customers configure an identifier from their existing login or signup flow, such as an email address, username, or phone number. Cloudflare cryptographically hashes that value to create a privacy-preserving, per-domain Hashed User ID. Within AAP, a Hashed User ID represents an account and anchors its activity. With each login or signup, AAP adds the event and relevant network and device signals observed at Cloudflare’s edge. Over time, this accumulated history establishes context for the account’s typical behavior, making meaningful deviations easier to identify and giving fraud teams (i.e., the designated personnel for Security Intelligence, Investigations, Trust & Safety, or Risk & Compliance) a stronger foundation for investigation.
Today, we are introducing a new fraud dashboard for Account Abuse Protection, available first to Early Access customers. The workspace brings together account overviews built from activity observed across a website’s configured login and signup flows. It allows fraud analysts to view their entire user population, identify suspicious trends, and move from aggregate activity patterns into specific account investigations.
Dashboard overview: From population visibility to individual account depth
The dashboard is designed as an investigative funnel. When a suspicious event has been identified, fraud teams can review the account population overview to understand the scale and shape of suspicious patterns without needing to investigate every account individually.
Teams can review total login and signup volume, see how many accounts generated those events, and view the unique IP addresses and devices observed across those accounts. Country and ASN breakdowns provide additional context about where the activity was observed.
The account population overview helps fraud teams answer questions such as:
Did login or signup volume change unexpectedly?
Are failed logins or leaked credential matches increasing?
Which accounts show the highest login failure rates?
Are events concentrated in particular countries, ASNs, or times of day?
Did a sudden signup increase coincide with shared characteristics?
Which accounts may have been affected by the attack?
From there, fraud teams can determine the campaign’s scope, prioritize accounts for manual review, reconstruct what happened within those accounts, and decide how to respond.
AAP in Action: Investigating a credential stuffing attack
Consider a fraud prevention or security analyst team investigating unusual login activity. The team opens the Account Abuse Protection dashboard to determine how broadly a credential stuffing attack may have affected its users. The dashboard allows analysts to investigate from total event traffic all the way to individual accounts that warrant review. The individual account view provides the history and context needed to reconstruct what happened and determine the appropriate response.
1. Spot the anomaly. The investigation begins in the account population overview, where the fraud team determines whether suspicious activity is isolated or part of a broader campaign. An increase in failed login activity prompts the team to examine Leaked credential check results on login events.
In this example, a leaked credential summary shows that approximately 2.4K events produced a leaked username or password result, compared with 11.7K events where credentials were classified as clean. This pattern is an investigative lead, not confirmation that every affected account was compromised.
The team can now focus on accounts associated with leaked credential matches. Are multiple accounts connected to the same IP addresses or ASNs? Does an individual account suddenly appear across an unusually high number of IP addresses? These relationships help define the potential scope of the credential stuffing campaign and identify the accounts that should be prioritized for review. Analysts can also look at the dashboard for concentration across particular IP addresses, ASNs, locations, or devices.
2. Narrow the field of investigation. Filters help narrow the account population to specific accounts with the most concerning combination of signals and identify which ones warrant manual review. For example, filters can be set to look at accounts with at least three failed logins, at least three leaked credential matches, and observed from at least five unique IP addresses.
From this filtered cohort, analysts can select the specific Hashed User IDs, whose recent activity requires the most urgent attention.
3. Investigate an account. Analysts can review login attempts, identify new devices or locations, and reconstruct how activity unfolded. Using the event table, they can compare earlier clear events with later suspicious activity, pinpoint when the pattern began, and determine whether it was a single event or a series of repeated attempts. Each event includes a Ray ID that analysts can use to look up associated information in Security Events.
4. Decide how to respond. If review confirms that an account was compromised, analysts can begin their established recovery process. They can also use the Hashed User ID in a WAF rule to challenge or block future requests associated with it.
A closer look at an individual account
An individual account view provides another layer of depth for investigation. It summarizes the login and signup activity observed for that account, including its login success rate, leaked credential matches, and most frequently associated networks, locations, and devices. Analysts can then examine the individual events behind the account summary. Each event includes its timestamp, Ray ID, and any mitigation applied. A Cloudflare Ray ID is an identifier given to every request that goes through Cloudflare, that teams can use to look up associated information in Security Events.
This detailed summary and event log helps answer questions such as:
Was this a single login event or part of a series of repeated attempts?
Did that login introduce a new country, network, IP address, or device?
Did the user’s behavior change afterward?
What happened before and after a suspicious event?
Did concentrated login activity follow shortly after signup?
Did signup and subsequent login activity use different network or device characteristics?
Viewed together, these signals help fraud teams determine whether an account requires recovery, restricting access, or another response, depending on how the customer wants to treat these accounts. When there is enough evidence, analysts can use the Hashed User ID in a WAF rule to challenge or block future requests associated with that identifier.
Designed to minimize unnecessary data exposure
Account Abuse Protection provides account level context while also giving Cloudflare customers control over who can access account information. This launch introduces two new roles (i.e., access levels): Account Abuse Protection and Account Abuse Protection PII. The Account Abuse Protection role controls access to the dashboard, while the Account Abuse Protection PII role controls access to additional account-level PII (e.g., email) . We encourage Customer Administrators to assign these roles on a need-to-know basis, based on what each team member needs to investigate.
The Account Abuse Protection PII role is also required to create or update Logpush jobs containing PII. Separating these permissions helps customers apply least privilege access to both dashboard and data export workflows.
Take the next step in account protection today
The new dashboard is available first to Account Abuse Protection Early Access customers. Bot Management Enterprise customers interested in these capabilities can sign up for Early Access. Prospective Bot Management Enterprise customers can use the same form to contact our team.
Bot detections help customers understand whether activity is automated. Account Abuse Protection adds account level overview to help fraud teams investigate whether login and signup activity appears authentic and consistent with legitimate use. Together, these capabilities help website owners address automated and human-driven abuse across account creation and login.
Today, we are launching Application Profiles, a seamless way to enforce a positive security policy. By analyzing the structure and format of HTTP requests and identifying deviations, Cloudflare can help you significantly reduce the attack surface area.
Every customer we speak to wants to know how we can protect them from attacks that use frontier AI models. This has become the number one priority for anyone working in security. Large language models (LLMs) allow even non-technical people to launch attacks with a single prompt. LLMs can generate malicious payloads, test known techniques, and probe applications autonomously by mutating their tactics based on the feedback from the application or the Web Application Firewall (WAF).
Our tools have changed to stay a step ahead of the attackers. Managed WAF rules and machine learning-based detections remain essential for detecting techniques such as SQL injection, cross-site scripting, remote code execution, and new CVEs, including many variations of those attacks. The answer can’t simply be “patch faster”: this is not sustainable, and it doesn’t work if you haven’t completely mapped your vulnerabilities.
What if you could learn what good requests look like by analyzing your traffic structure? Instead of looking only for requests that resemble known attacks, we could allow only requests that conform with what we expect. By doing this, we’d dramatically reduce the attack surface area. For example, if the search field in your query doesn’t expect special characters, we can only accept alphanumeric strings. This would already prevent a vast library of known attacks.
But we don’t stop here. Once we have learned the structure and format of your HTTP requests, we can infer the goal of each operation and then understand what the application ultimately does. With this information, we can identify and prioritize the most critical and vulnerable operations and fields you should take care of first.
Cloudflare already supports positive security for APIs through Schema Learning and Schema Validation. We are now extending this protection to web applications through Application Schema Profiles. You onboard an application, we learn its profile, and then we start to deploy an always-on detection that identifies non-conformity. All automated and enriched by powerful analytics.
We are opening a closed beta to invited Enterprise customers without API Security; customers with API Security already have access.
Validating requests based on learned profiles
Schema Profiles periodically learn the expected request structure from observed traffic. After a profile is available, an always-on validation layer is automatically deployed on live traffic. For every request, the detection evaluates whether it conforms or not with the profile, and it adds the result as metadata, augmenting the information already associated with the request. The signal does not take action by itself: customers can analyze past traffic in Security Analytics and decide where enforcement is appropriate and create Security Rules to block non-conforming requests. Requests to operations without a profile are not classified by this feature.
Unlike Managed Rules, failing validation does not require a request to match a known attack signature. A value outside an expected range, an unknown enum value, an invalid universally unique identifier (UUID), or unexpected characters — all can be identified because they differ from the learned profile.
Below we describe the learning process, which evaluates only the structure and format of the request. When enough traffic has been observed, we learn that the path expects a UUID variable and that product_id is an integer and what its boundaries are. When product_id contains a string, it will be flagged as a violation. Similarly, Cloudflare can identify malformed UUID values and, when the customer enables enforcement, prevent non-UUID input from reaching the corresponding handler. These simple filters reduce the range of inputs an attacker can send, preventing the vast majority of typical attack vectors, such as SQL injection, cross-site scripting, remote code execution and more.
Non-conforming does not always mean malicious. An application release, a new client, or an unusual but valid request may also introduce a difference. We recommend starting in observation mode, so customers can review a profile's effect before enforcement.
Learn the expected structure of requests
To determine the anticipated request structure for a web or API application, Schema Profiles routinely analyze observed traffic. Each profile may include the following, depending on the application traffic:
Path variables
Query parameters
Headers and cookies
Body structure (JSON body or form-encoded)
For each field, the system learns its data type (integer, string, boolean, arrays, UUID or enum) and constraints such as numeric ranges, short enumerations, string lengths, and character classes.
Learning applies to operations that customers select for profiling. In Web Assets, an operation is Cloudflare's term for an operation identified by its HTTP method, hostname pattern, and path pattern. Web Assets continuously discovers operations and lists them under Web Assets > Operations. Customers can also add operations manually. Profiling doesn’t automatically start for discovered operations, while manually created operations do trigger profiling when created. For discovered operations, the customer must intentionally select Learn profile from the operation's overflow menu.
After profiling is enabled, Cloudflare collects qualifying traffic and runs learning automatically once a week for each zone, using the most recent successful traffic. An operation needs at least 1,000 requests that received a 2xx response in the previous seven days to learn fields, and at least 10,000 to learn data boundaries. Successful requests can include bots and scanners, so customers should review a learned profile before enforcing it. Our roadmap includes allowing customers to trigger learning on demand and excluding automated traffic.
Once learned, profiles can be reviewed by selecting View details of the operation and finding the learned schema in the Security overview panel. If a learned schema is not shown, Cloudflare is still collecting data for the profile. Customers can also export the profile as an OpenAPI v3 schema file.
Learned profiles update each week as application traffic changes. New fields are added and fields that are no longer observed are removed, so validation tracks how the application changes. Customers can pin and save the learned schema by downloading the learned schema and uploading it to Schema Validation.
Review before you block
Security Analytics now includes a new Profile Analysis tab. Customers can select a validation profile and see traffic trends, including how many requests did not conform to the learned profile during the previous seven days.
Customers can review the conforming and non-conforming traffic. They can drill into violations and review sampled logs to see where the violation occurred, which field was affected, and why it failed validation. Violations are classified into ten reasons, including type mismatches, values outside a learned range, and invalid formats.
Once a team understands the effect, it can use Security Rules to act on the signal. A rule can cover an entire application or be limited to selected paths, operations, or fields. Teams control where to monitor and where to block.
Positive security for web and API traffic
Traditional WAF learning modes can build detailed positive-security policies, but they often require operators to review suggestions, stage changes, and maintain policy entities. Cloudflare Schema Profiles expose validation as a request field cf.schema_validation.learned.violated, allowing customers to combine it with request properties, Bot Score, Attack Score, and other signals in a single Security Rule. By creating simple rules, teams can combine detections and define precisely when Cloudflare should take action.
Two other classes of fields are available to create more targeted rules. First, there are fields that collect where the violation occurred. For example, based on our initial example, if the value of product_id query parameter does not conform with the profile, the following field will be populated cf.schema_validation.uploaded.query.violated_parameters = ["product_id"]. This allows customers to create rules that enforce positive security only on specific fields or exclude them from the enforcement.
The second class of field collects new parameters that are not present in the profile. This is useful when you want to handle requests with new parameters (e.g. when deploying a new version of your application), or restrict your posture even further by blocking any parameters that were not detected or defined in the past.
Use case
Field
Location values
Example
Identify where in the request the violation occurred
Coming up: critical field analysis, how we help you roll out positive security
Even with a flexible enforcement design, customers tell us that deploying a positive security policy is operationally complex. A large application can have thousands of operations with tens of thousands of fields. But not all operations and fields carry the same risk. Contextualization and prioritization helps security teams roll out positive security in a controlled and confident manner.
LLMs can help contextualize learned profiles to provide additional insight. For web applications, paths and field names are usually self-explanatory, thus semantic. For example, we piloted running a model hosted on Workers AI across four random applications’ learned profiles. The model successfully identified the link between clientId and account_number across two applications of a system, as well as the common dependency of using One-Time Password (OTP) for enhanced authentication. Highlighting this context enables security teams to prioritize actions such as configuring Rate Limiting Rules to defend against account-focused brute force attacks.
These LLM-powered insights will be accessible directly within the dashboard alongside each operation in Web Assets. Before executing a one-click deployment, teams can evaluate rule recommendations designed to secure these key fields, backed by mitigation simulation using past traffic to gain confidence.
Beyond contextualizing operations with semantic insights and risk indicators, we are developing additional metrics to order operations using historical request trends and signals. This enables security teams to focus mitigation efforts on the highest-priority operations first, including:
Data loss: upward trend of unusual increased data transfer
Reconnaissance activity: high count of unknown parameters
Business criticality: total volume of traffic correlated with the unique session IDs served
What’s available today
Customers with API Security already have access, given that this is an extension of Schema Learning and Schema Validation. We are opening a closed beta to customers without API Security who can test Schema Profiles on production web application traffic, meet with the product team, and provide detailed feedback on profile accuracy, analytics, and enforcement controls. Access is by invitation and does not imply future plan availability. If you are not an API Security customer and want to get access, contact your account team.
The feature supports paths, query parameters, headers, cookies, JSON request bodies, and form-encoded request bodies. Profiles can validate integers, strings, UUIDs, arrays, and enums containing up to three values. Multipart forms, GraphQL, and XML are not supported at this time.
Schema Profiles validate every value when a parameter name is repeated, but they do not enforce parameter uniqueness. They also do not learn and enforce required parameters or block a request solely because it includes a new parameter.
Get ahead of zero-days
Our idea for Application Profiles does not stop at validating request structure. The same workflow can learn other characteristics of what an application expects (such as ASNs or JA4s), explain when traffic deviates from them, and give security teams confidence in defining what “good” looks like. With a Proactive Security workflow, we help security teams get ahead of zero-days!
AI is changing how software is built, tested, and secured, but the speed of development is also creating new challenges for application security teams. As AI coding tools and autonomous agents increase the volume and pace of software development, security teams are facing a growing gap between vulnerability detection, prioritisation, and remediation.
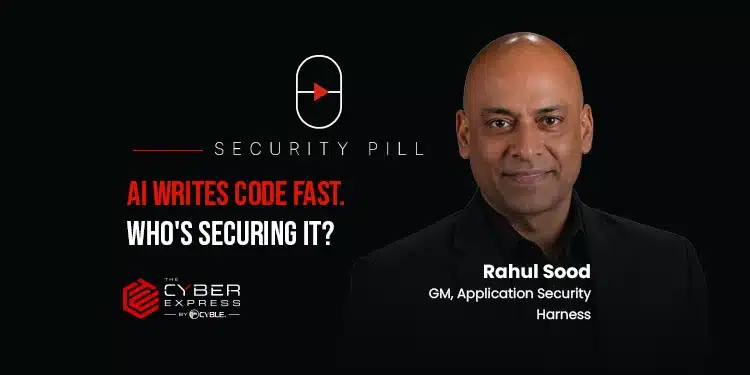
In this interview with Rahul Sood, GM, Application Security at Harness, we explore how AI application security is evolving as developers increasingly rely on AI-assisted coding and software agents. Sood discusses why traditional checkpoint-based security processes are struggling to keep pace, how organisations can bring security controls closer to the point where code is created, and why automated vulnerability remediation could become increasingly important.
The conversation also examines the security risks associated with AI agents that can access repositories, APIs, infrastructure and production environments. Sood explains why identity, least-privilege access, observability and human oversight will become increasingly important as software gains greater autonomy, and why application security will need to address not only what software contains, but also what autonomous systems are authorised to do.
Read the full interview below for Rahul Sood’s perspective on the changing application security landscape and the security challenges emerging as AI takes a more active role in software development.
The Cyber Express: What is the biggest change AI is bringing to the application security landscape?
Rahul Sood: The biggest change is speed. We have spent years making software development faster, and AI has accelerated that dramatically. Security processes, however, haven't accelerated at the same rate.
Most security scanning is still triggered at fixed checkpoints - a pull request, merge, or nightly build - designed for a world where a developer produces a handful of meaningful commits a day.
LLM-based scanning can potentially find 10x more vulnerabilities vs. traditional scanning tools. That sounds great, but it also means the discovery side of the pipeline is now outpacing triage and remediation even more than it already was.
That's where AI agents also become part of the answer, not just part of the problem. An agent can identify something and begin acting on it in close to the same motion, which is exactly the kind of compression this gap needs. The challenge is making sure that speed is matched with the right judgment and oversight.
The Cyber Express: AI coding assistants can introduce insecure code at scale. What should teams be doing differently?
Rahul Sood: The instinct is to assume AI-generated code is introducing more vulnerabilities because AI is somehow worse at writing secure code. I don't think that's the real story. Even if AI wrote code exactly as securely as a person does, the sheer volume of code now being produced would still overwhelm the way most organisations scan for issues today.
Scanning at the commit is already struggling to keep pace, as we discussed. The next step is pushing security further left than that, into the coding tool or agent itself, so secrets detection, dependency checks, and application security testing happen as the code is being written, and those same controls continue through build and deployment rather than starting over at each stage. You need both: controls at the point of creation to cut volume, and a verification layer that confirms what's really going out the door.
I expect the industry to move from automated detection towards much more automated resolution. Systems will increasingly identify an issue, establish whether it is actually exploitable, create a potential fix, verify that fix and then bring a developer in where judgement or approval is required. Human oversight remains important, but it should be concentrated on decisions where human judgement adds value rather than every mechanical step surrounding them.
The Cyber Express: What new security challenges emerge when AI agents can make decisions and take actions?
Rahul Sood: A coding assistant can suggest something insecure, but there are usually other controls between that suggestion and production. An agent with access to APIs, repositories or infrastructure is different. It has been given authority to act. That makes identity, permissions and the scope of that authority fundamental security questions.
One principle I think will become increasingly important is that autonomy should be proportional to the consequence of the action. The more consequential and difficult an action is to reverse, the stronger the controls around it should be.
More broadly, enterprises will need a security architecture for non-human actors: distinct identities, least-privilege access, short-lived credentials, complete auditability and clear boundaries around which decisions an agent can make independently.
The important question isn't how autonomous an agent is. It's what we've given it the authority to do, where the boundaries are, and what happens when it gets a decision wrong.
The Cyber Express: What becomes harder to secure when applications behave dynamically?
Rahul Sood: AI-native applications introduce another layer because some risks only become visible through behaviour. The security question is no longer limited to whether the underlying code contains a known vulnerability. You also need to understand what the system is doing at runtime.
One of the more concerning findings in the AI-native application security research we conducted last year was how basic the visibility problem still was. Many security practitioners told us they didn't have a reliable way of identifying all of the LLMs operating within their environment. That's a significant problem because you cannot meaningfully govern something you don't know exists.
As applications become more dynamic, understanding behaviour becomes just as important as understanding what's in the code.
The Cyber Express: Is shift-left still enough?
Rahul Sood: Shift-left was an important correction because security was happening far too late. But moving security earlier in development doesn't solve the entire problem on its own, since risk doesn't only enter through code. It can come through a dependency, an API, a model interaction, a deployment configuration, or the way an application behaves once it's actually running.
There is also a growing mismatch between how quickly vulnerabilities can be exploited and how long organisations take to remediate them. The 2026 Edgescan Vulnerability Statistics Report puts the average time to close high and critical vulnerabilities at roughly 55 days. At the other end of that equation, exploitation of newly disclosed vulnerabilities can now begin within hours.
Finding a vulnerability earlier is useful, but the more consequential metric is the period between discovery and protection. The next phase of application security is less about moving a scanner to an earlier point in the lifecycle and more about compressing the entire exposure window, from discovery to protection.
The Cyber Express: How can teams identify which risks actually matter?
Rahul Sood: Security teams don't have an alert problem as much as they have a context problem.
A vulnerability can have a severe technical rating and still present relatively little immediate risk if the affected component isn't reachable or exposed. Another vulnerability with a lower score could sit in an internet-facing, business-critical application and deserve immediate attention.
So prioritisation has to move beyond severity. That means combining technical severity with signals like EPSS scores for real-world exploit probability, static reachability analysis to confirm whether a vulnerable path can actually be called, and false-positive reduction to cut out findings that never posed real risk in the first place.
The goal shouldn't be to help a security team process 10,000 alerts faster. It should be to make sure they don't have to treat 10,000 alerts as equally important in the first place.
The Cyber Express: What does a healthy developer–security relationship look like?
Rahul Sood: The healthiest organisations I've seen don't treat security as a handoff between two teams. Developers understand that security is part of building good software, while security teams take responsibility for making the secure path practical.
If following security policy means leaving the developer workflow, opening a ticket, waiting several days and then interpreting a scanner report, people will inevitably look for ways around the process. That's an operating-model problem, not simply a developer behaviour problem.
We saw how wide that gap had become in research we conducted last year. Seventy-four percent of security professionals surveyed said developers viewed security as a blocker to AI innovation.
Security teams should define acceptable risk, policies and guardrails. Engineering teams should then be able to work within those boundaries without constantly asking for permission. That is ultimately what a mature DevSecOps model should achieve. Security becomes part of the engineering system rather than another team standing beside it.
The Cyber Express: What one assumption should organisations rethink today?
Rahul Sood: One assumption I would rethink is that knowing what software contains is enough to understand its security posture.
Application security has traditionally been very good at analysing components: the code, libraries, dependencies, APIs and vulnerabilities that make up an application. But with autonomous software, knowing what it's made of is only part of the picture. We also need to understand the authority we've given it.
An agent may be built from approved components and have no obvious vulnerability in its code, yet still create significant risk because it can access the wrong data, has excessive permissions or can take an action that was never anticipated when those permissions were granted.
We have spent decades building security around software that executes instructions written by people. We are now introducing software that can interpret a goal, decide how to pursue it and interact with other systems along the way.
The security architecture for that world cannot rely only on finding vulnerabilities. It also has to govern delegated authority. I think that will become one of the defining application security problems of the agentic era.
Want to Be Part of Security Pill?
Are you a cybersecurity professional, researcher, CISO or industry expert with insights to share? The Cyber Express is always looking to bring new voices and perspectives to the cybersecurity community.
If you would like to be featured on Security Pill or discuss a potential podcast collaboration, reach out to us at [samiksha.jain@thecyberexpress.com].
Have a story, expertise, or perspective to share? Let’s start the conversation.

 Entrar